<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://www.manuelcastillo.eu/feed.xml" rel="self" type="application/atom+xml" /><link href="https://www.manuelcastillo.eu/" rel="alternate" type="text/html" /><updated>2026-09-09T20:03:24+02:00</updated><id>https://www.manuelcastillo.eu/feed.xml</id><title type="html">Ph.D. Manuel Castillo-Cara</title><subtitle>Manuel Castillo Cara is an Udemy instructor and postdoctoral researcher fellow at Universidad Politécnica de Madrid. Research lines: Wireless Sensor Networks, Distributed Computing, Pattern Recognition and Artificial Intelligence. Manuel Castillo Cara es instructor Udemy e investigador postdoctoral en la Universidad Politécnica de Madrid. Líneas de investigación: Redes de Sensores, Computación Distribuida, Reconocimiento de Patrones e Inteligencia Artificial.</subtitle><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><entry><title type="html">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</title><link href="https://www.manuelcastillo.eu/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/" rel="alternate" type="text/html" title="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" /><published>2026-08-08T00:00:00+02:00</published><updated>2026-08-08T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/08/09-rgb-fusion-structural-stability-mixmethod-ssim</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/"><![CDATA[<div style="background: linear-gradient(135deg, #0f172a 0%, #312e81 38%, #6d28d9 66%, #0f766e 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #ddd6fe; font-weight: 600;">TINTOlib · Clusters · RGB Fusion · Structural Stability</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">RGB Fusion and Structural Stability</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #ede9fe; line-height: 1.55;">How <code>mixMethod</code> combines complementary unsupervised representations across RGB channels and how TINTOlib uses SSIM to select stable representation dimensions.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">mixMethod</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">RGB Fusion</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">SSIM</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">Clusters</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 270px; width: 100%;">
    <img src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="RGB fusion and SSIM-based structural stability in TINTOlib Clusters" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<h2 id="tutorial-metadata">Tutorial metadata</h2>

<ul>
  <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
  <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
  <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
  <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
</ul>

<hr />

<blockquote>
  <p><strong>Series note — Part IV of IV.</strong> This article closes the four-part technical series on the unsupervised representations available through the TINTOlib <code class="language-plaintext highlighter-rouge">Clusters</code> class.</p>

  <ul>
    <li><strong><a href="https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Part I — From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib</a></strong></li>
    <li><strong><a href="https://www.manuelcastillo.eu/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part II — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a></strong></li>
    <li><strong><a href="https://www.manuelcastillo.eu/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part III — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a></strong></li>
    <li><strong>Part IV — RGB Fusion and Structural Stability in TINTOlib:</strong> <code class="language-plaintext highlighter-rouge">mixMethod</code>, channel composition and SSIM-based automatic selection — this article.</li>
  </ul>
</blockquote>

<h2 id="video-overview">Video overview</h2>

<p>The following short video summarizes the main concepts introduced in this final article.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-08-08-09-rgb-fusion-structural-stability.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<h2 id="from-one-representation-to-several-complementary-views">From one representation to several complementary views</h2>

<p>The first three articles in this series examined how a tabular sample can be converted into an image through different unsupervised intermediate representations:</p>

<ul>
  <li>distances to synthetic centroids;</li>
  <li>distances to representative medoids;</li>
  <li>local KNN membership probabilities;</li>
  <li>Gaussian-mixture posterior responsibilities;</li>
  <li>feature-wise density estimates;</li>
  <li>latent Factor Analysis scores.</li>
</ul>

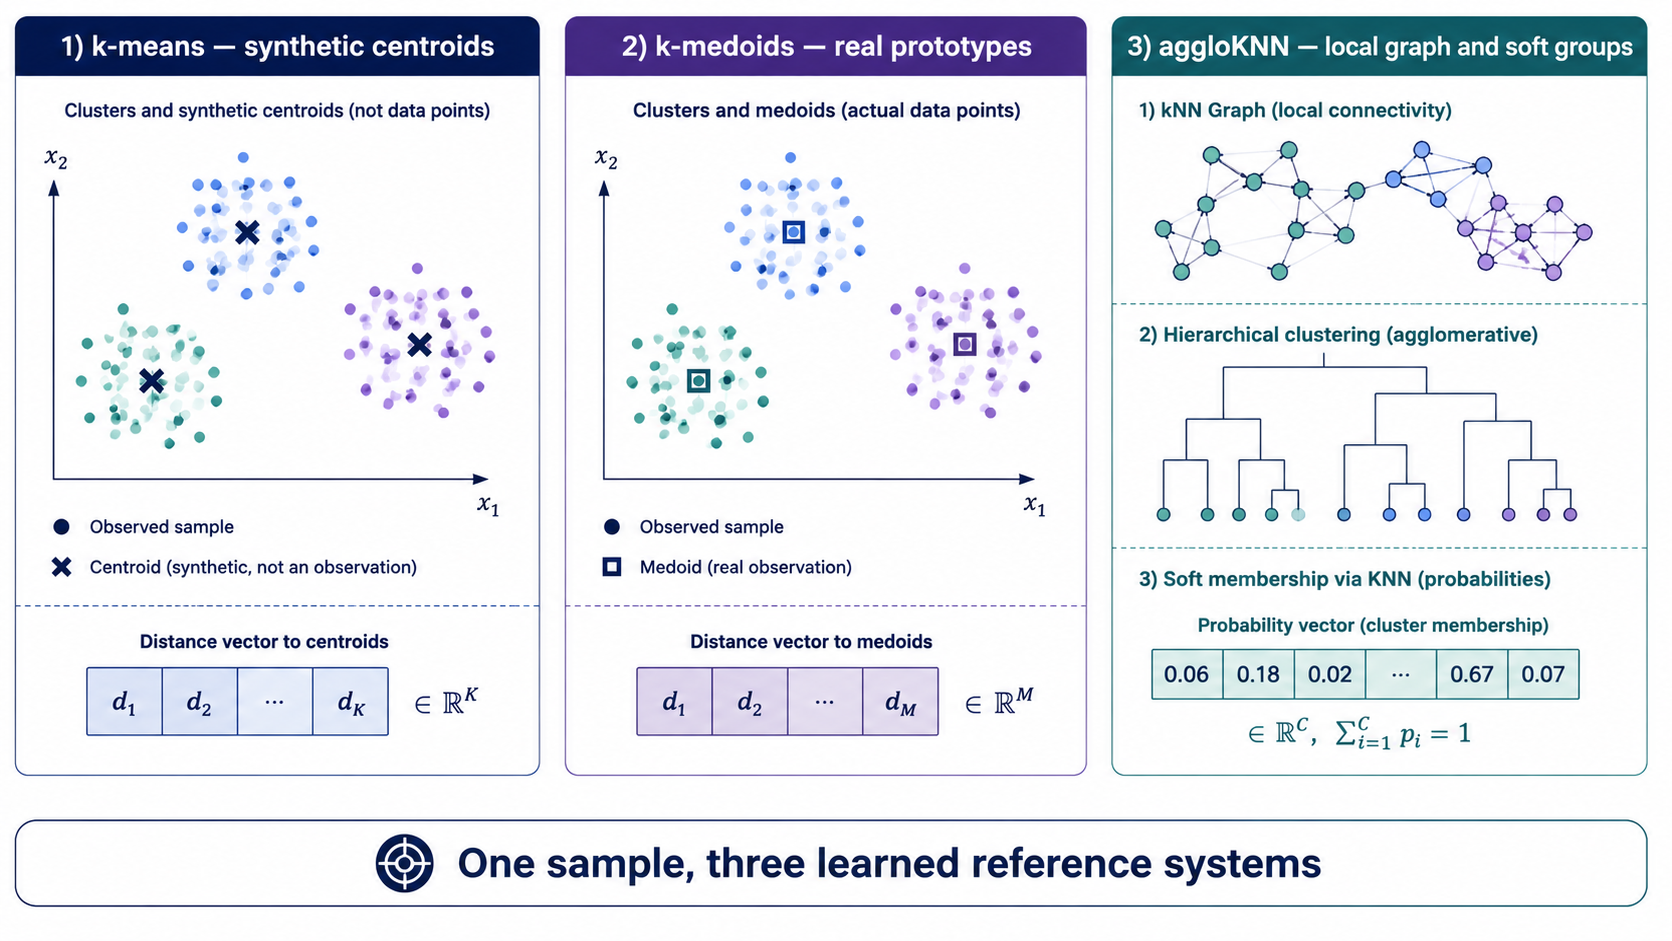
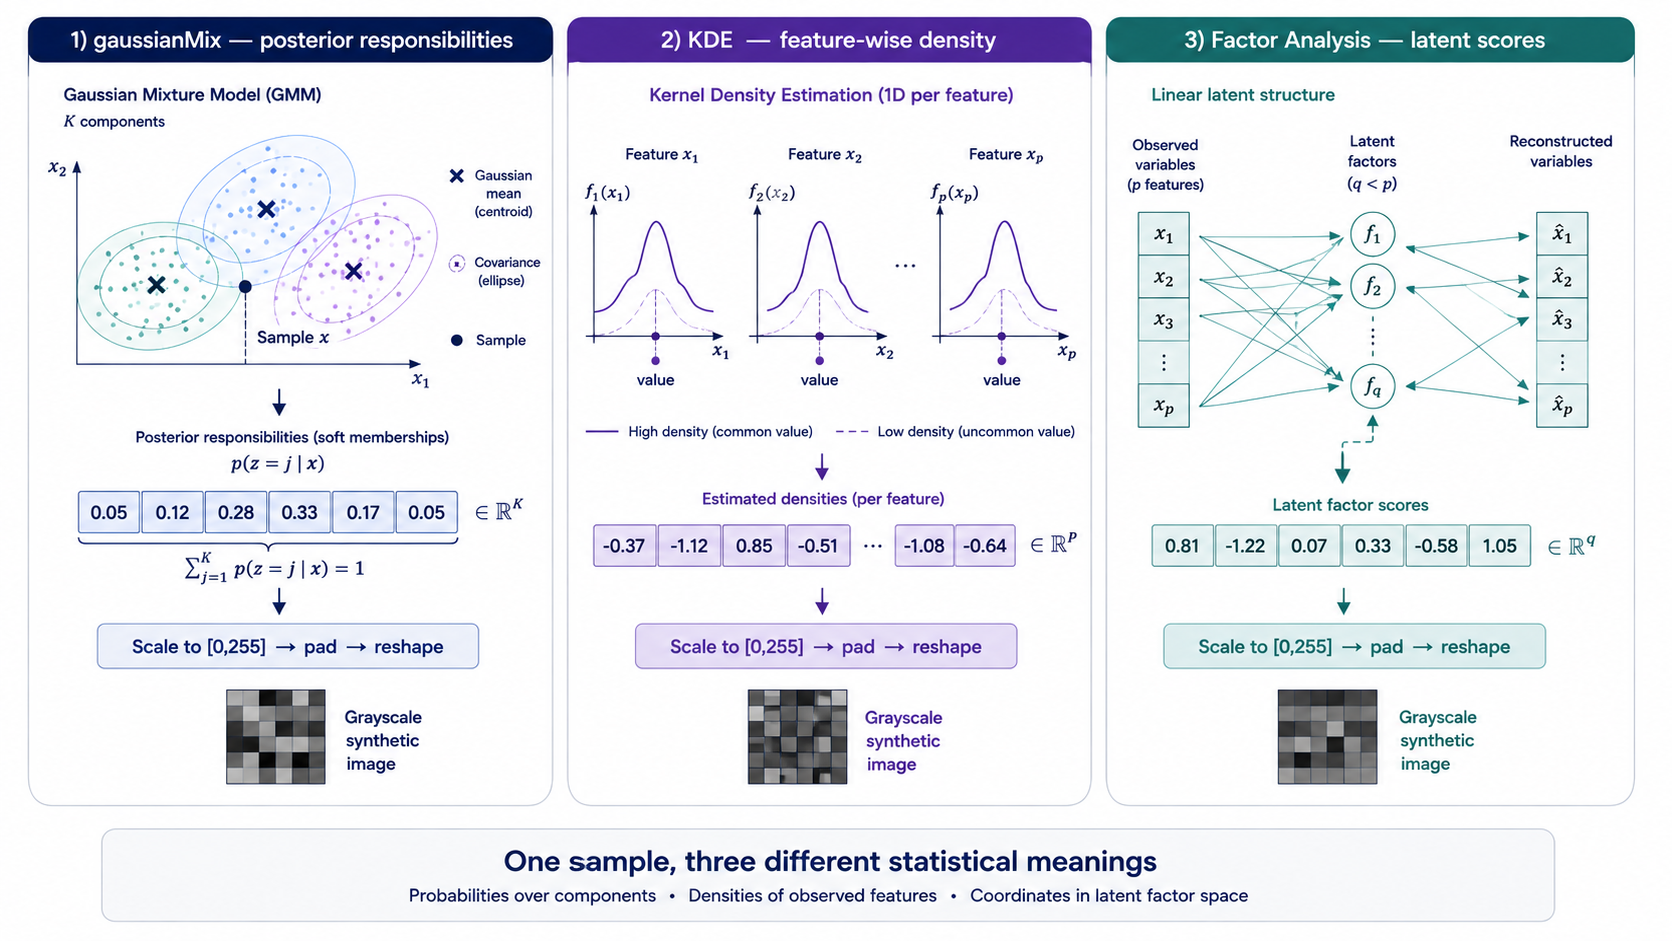
<p>Each representation answers a different question about the same observation. A centroid-distance vector describes <strong>proximity to learned regions</strong>. A Gaussian-mixture vector describes <strong>soft component membership</strong>. A factor-score vector describes <strong>position in a latent covariance structure</strong>.</p>

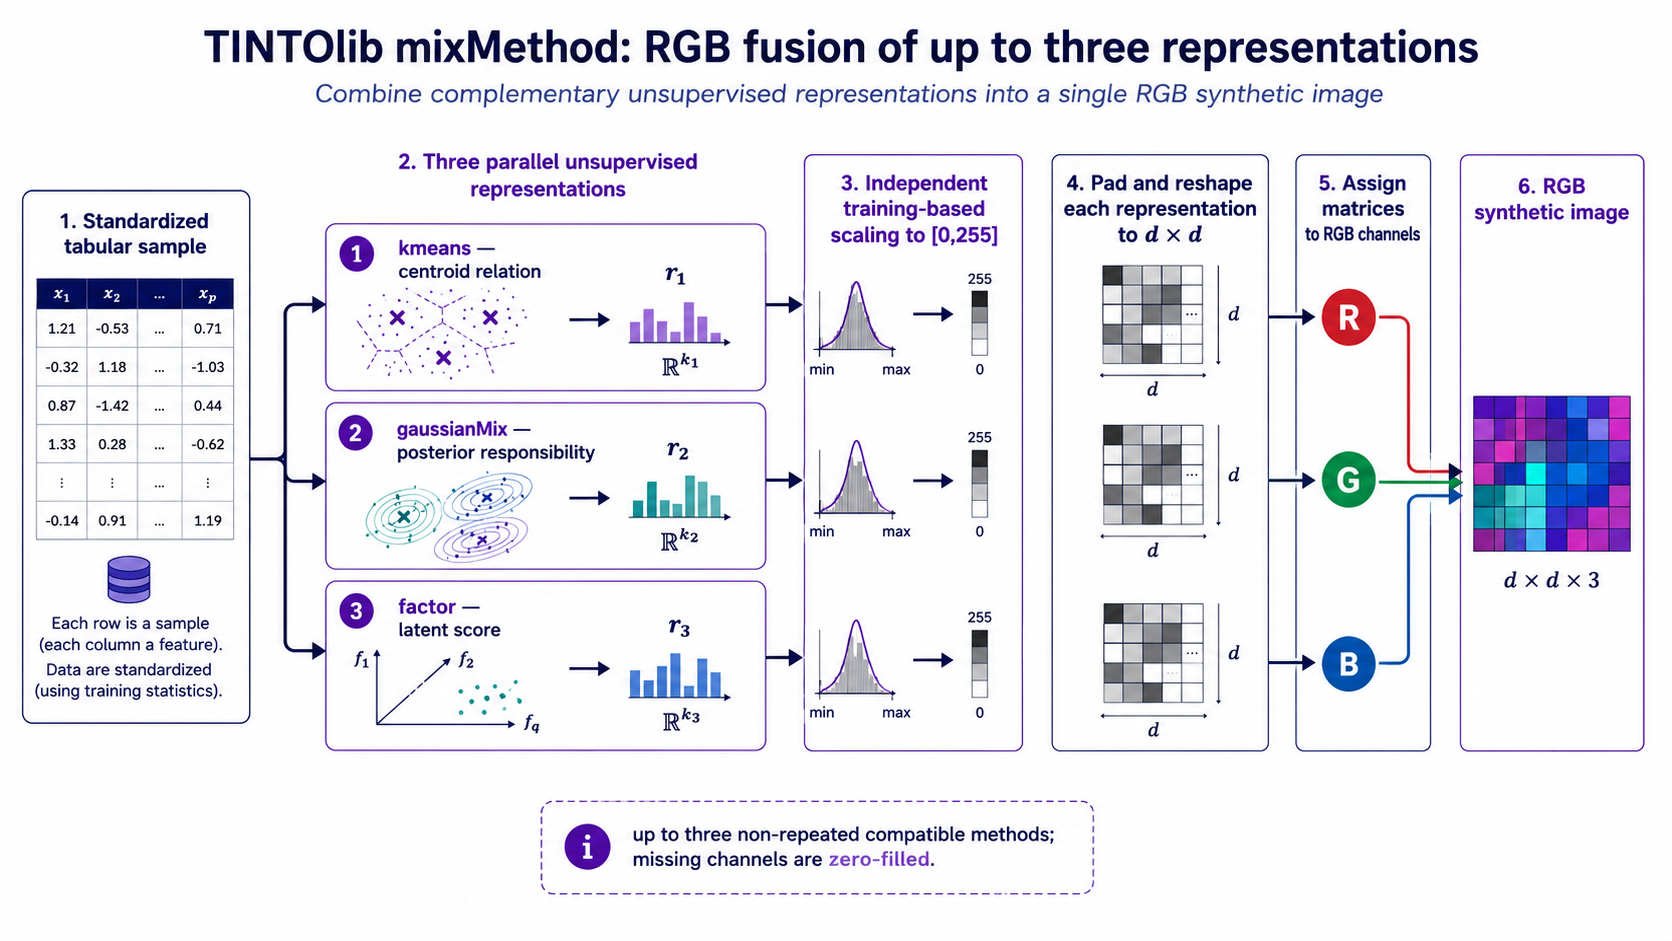
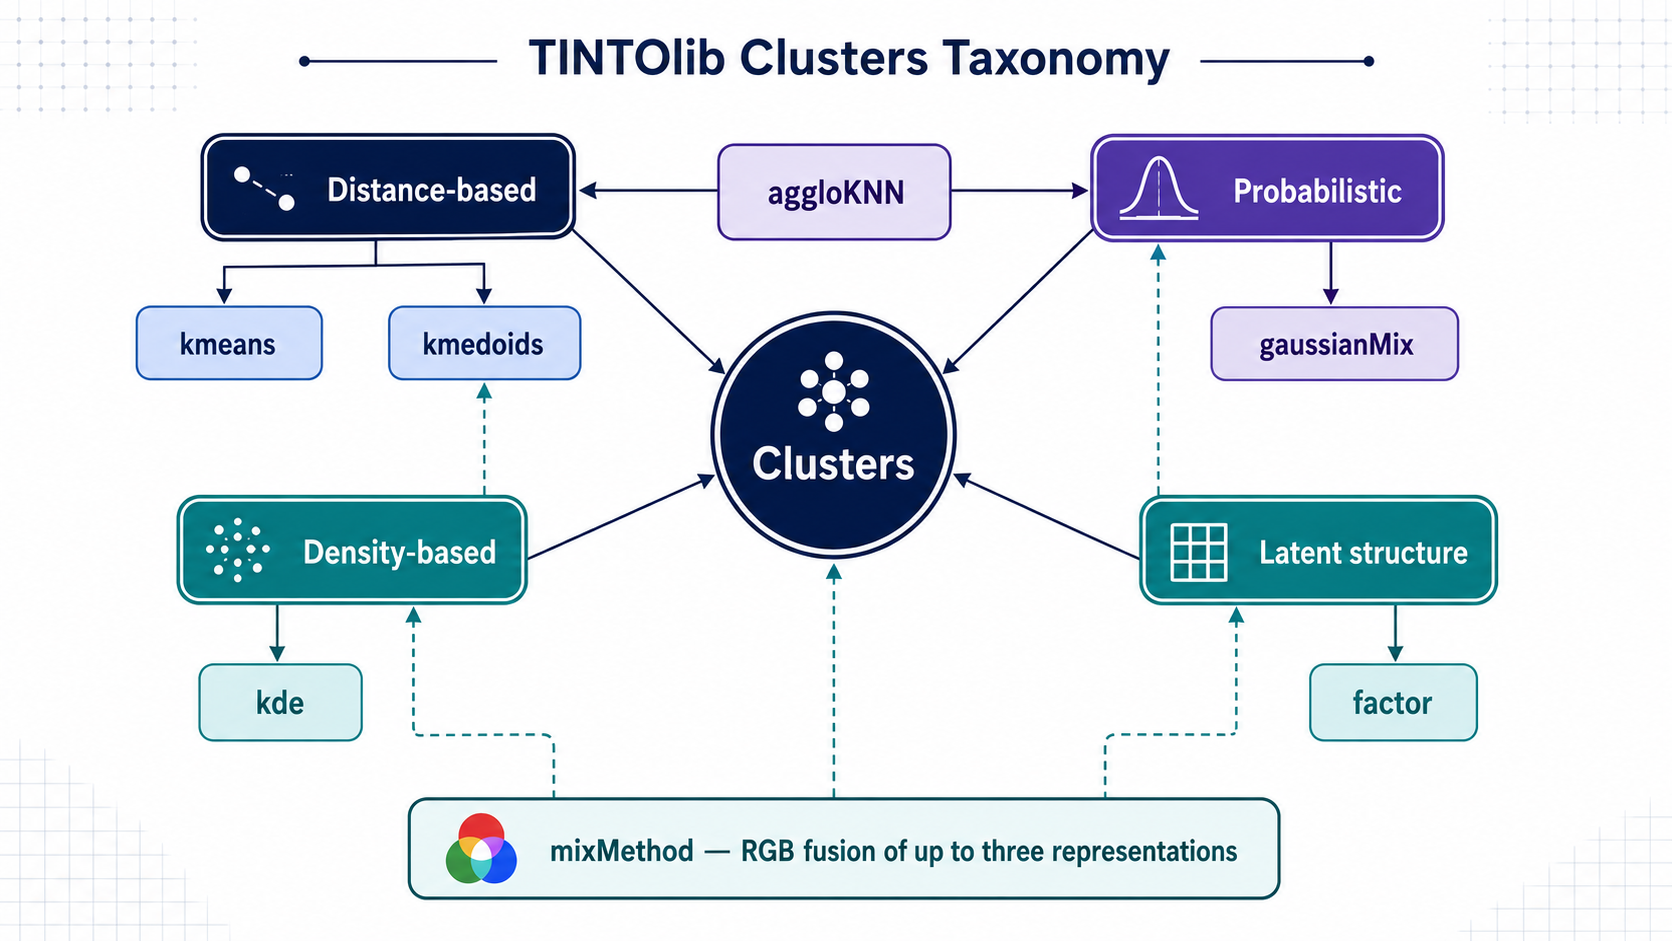
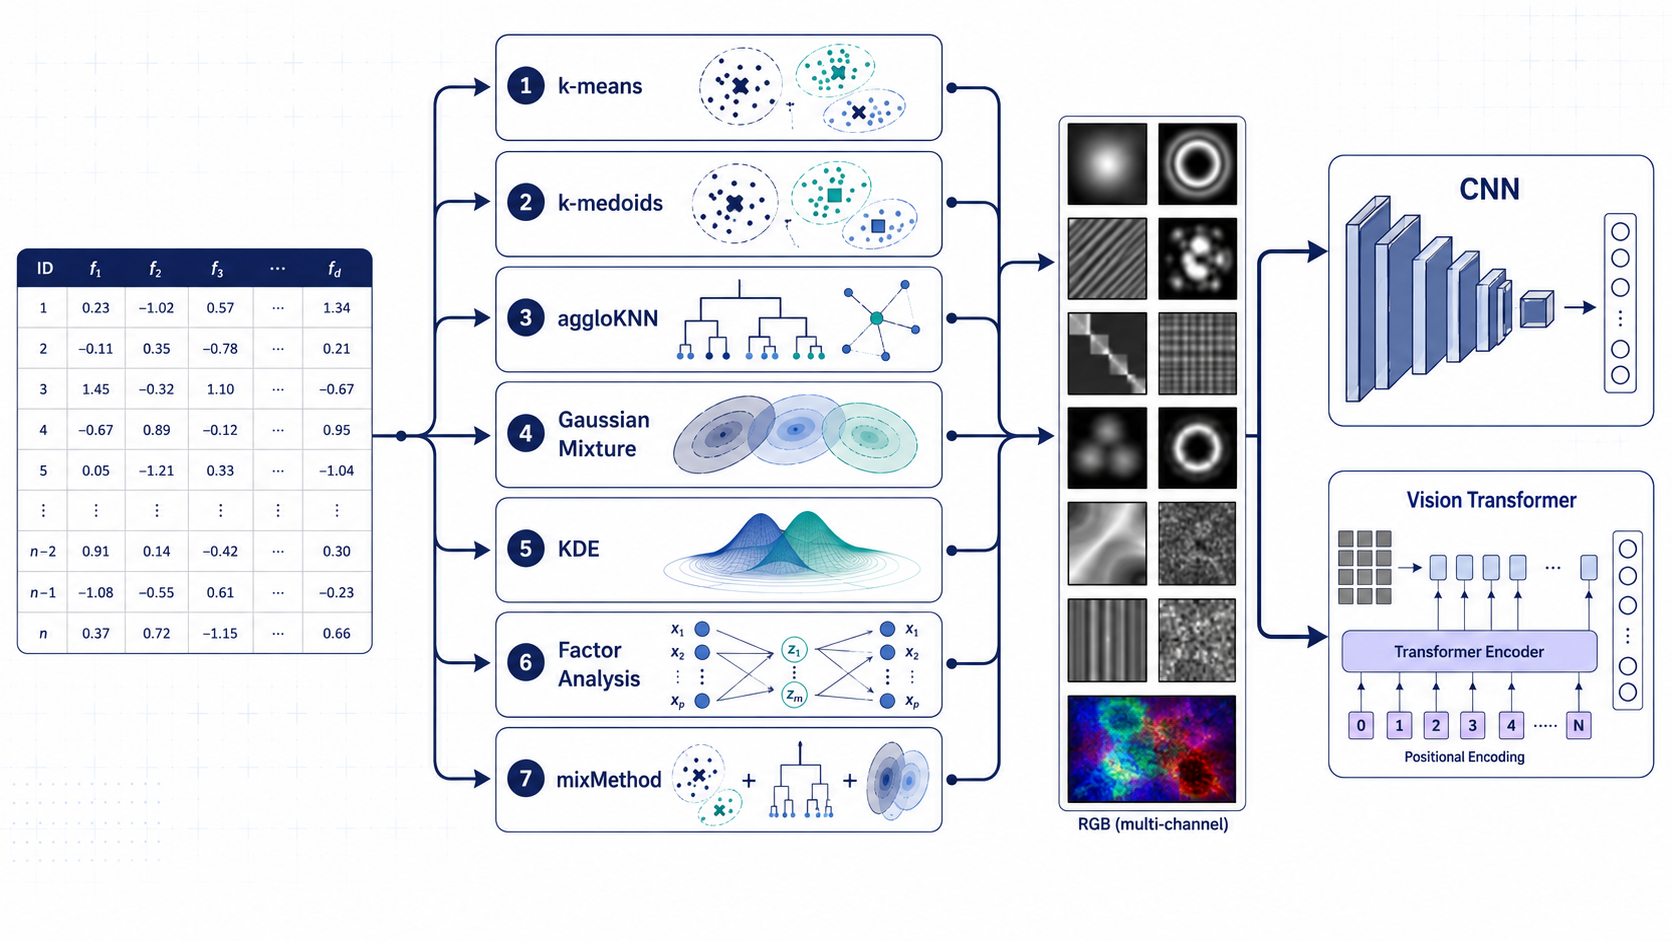
<p><code class="language-plaintext highlighter-rouge">mixMethod</code> introduces a different idea: instead of choosing only one description, it places several compatible representations into different colour channels of the same synthetic image.</p>

<p>Conceptually, for a tabular sample</p>

\[\mathbf{x}_i \in \mathbb{R}^{p},\]

<p>three selected transformations may produce</p>

\[\mathbf{r}_i^{(R)},\quad
\mathbf{r}_i^{(G)},\quad
\mathbf{r}_i^{(B)}
\in \mathbb{R}^{k}.\]

<p>After training-based scaling, padding and square reshaping, they become</p>

\[\mathbf{I}_i^{(R)},
\mathbf{I}_i^{(G)},
\mathbf{I}_i^{(B)}
\in \{0,\ldots,255\}^{d\times d},\]

<p>where</p>

\[d=\left\lceil \sqrt{k} \right\rceil.\]

<p>The final RGB representation is the channel-wise stack</p>

\[\mathbf{I}_i^{(\mathrm{RGB})}
=
\operatorname{stack}
\left(
\mathbf{I}_i^{(R)},
\mathbf{I}_i^{(G)},
\mathbf{I}_i^{(B)}
\right).\]

<p>The key point is that colour is not decorative. It is the visible consequence of combining different statistical descriptions of the same tabular record.</p>

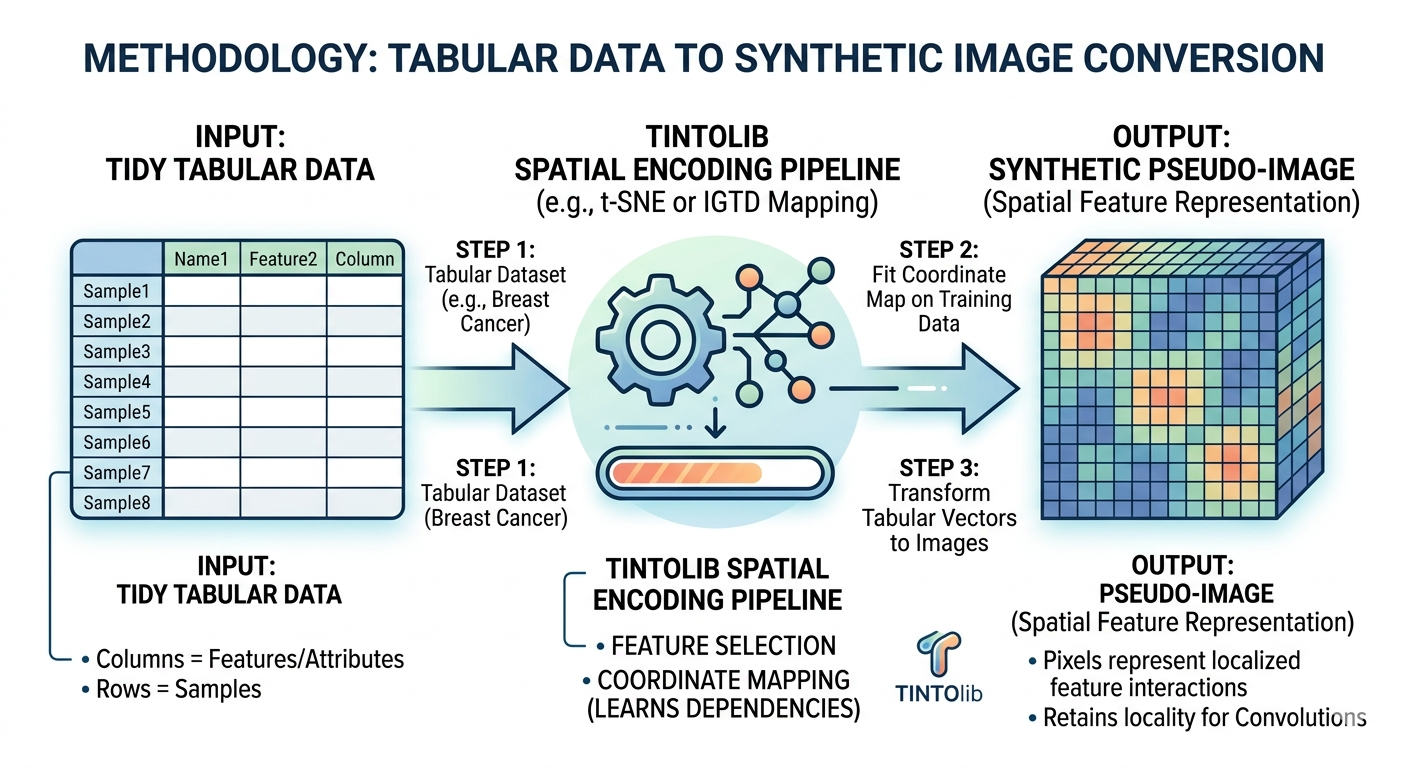
<p><img src="/images/Blog/2026-08-08-09-mixmethod-pipeline.png" alt="TINTOlib mixMethod pipeline" />
<em>(Figure 1. Conceptual workflow of <code class="language-plaintext highlighter-rouge">mixMethod</code>. The same standardized tabular sample is transformed by up to three compatible unsupervised methods. Each intermediate representation is independently scaled to pixel intensities, padded and reshaped, and the resulting matrices are assigned to the red, green and blue channels of one RGB synthetic image.)</em></p>

<h2 id="1-mixmethod-multi-view-synthetic-images">1. <code class="language-plaintext highlighter-rouge">mixMethod</code>: multi-view synthetic images</h2>

<p>The <code class="language-plaintext highlighter-rouge">ensamMethod</code> parameter determines which representations form the RGB image and, importantly, their order.</p>

<p>For example,</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">ensamMethod</span><span class="o">=</span><span class="p">[</span><span class="s">"kmeans"</span><span class="p">,</span> <span class="s">"gaussianMix"</span><span class="p">,</span> <span class="s">"factor"</span><span class="p">]</span>
</code></pre></div></div>

<p>means:</p>

<ul>
  <li><strong>R channel:</strong> k-means representation;</li>
  <li><strong>G channel:</strong> Gaussian-mixture representation;</li>
  <li><strong>B channel:</strong> Factor Analysis representation.</li>
</ul>

<p>If fewer than three methods are supplied, TINTOlib fills the remaining higher channels with zero-valued matrices. Therefore,</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">ensamMethod</span><span class="o">=</span><span class="p">[</span><span class="s">"kmeans"</span><span class="p">,</span> <span class="s">"factor"</span><span class="p">]</span>
</code></pre></div></div>

<p>produces:</p>

<ul>
  <li><strong>R:</strong> k-means;</li>
  <li><strong>G:</strong> factor;</li>
  <li><strong>B:</strong> zeros.</li>
</ul>

<h3 id="which-algorithms-can-be-combined">Which algorithms can be combined?</h3>

<p>The current <code class="language-plaintext highlighter-rouge">mixMethod</code> implementation accepts the following component methods:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Method</th>
      <th style="text-align: center">Available in <code class="language-plaintext highlighter-rouge">mixMethod</code>?</th>
      <th style="text-align: left">Channel semantics before pixel scaling</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmeans</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: left">Distances to centroids, or RBF similarities when enabled</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmedoids</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: left">Distances to representative medoids</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">aggloKNN</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: left">KNN membership probabilities derived from hierarchical pseudo-labels</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">gaussianMix</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: left">Posterior Gaussian-component responsibilities</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">factor</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: left">Latent factor scores</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kde</code></td>
      <td style="text-align: center">✗</td>
      <td style="text-align: left">Per-feature density vector has dataset-dependent dimensionality</td>
    </tr>
  </tbody>
</table>

<p><code class="language-plaintext highlighter-rouge">ensamMethod</code> must be a non-empty list containing at most three <strong>non-repeated</strong> methods. KDE is excluded because its representation dimension is tied to the number of original features rather than to the shared <code class="language-plaintext highlighter-rouge">n_clusters</code> value used to align compatible channels.</p>

<p>When <code class="language-plaintext highlighter-rouge">factor</code> is included, the number of latent factors must also respect the dimensionality constraints imposed by Factor Analysis.</p>

<h3 id="channel-alignment-matters">Channel alignment matters</h3>

<p>An important implementation detail appears when k-means or k-medoids are used as individual grayscale methods. In that case, TINTOlib can reorder the learned references according to proximity before reshaping the representation.</p>

<p>Inside <code class="language-plaintext highlighter-rouge">mixMethod</code>, this reordering is intentionally not applied. Independently reorganizing one channel would break the positional correspondence with the other channels. The RGB representation therefore prioritizes <strong>channel alignment</strong> over the grayscale reference-ordering heuristic.</p>

<p>This distinction is important when interpreting the resulting image: a position $(u,v)$ should be understood as a shared channel index, not as three independently optimized spatial layouts.</p>

<h2 id="actual-channels-versus-the-final-rgb-image">Actual channels versus the final RGB image</h2>

<p>A useful way to understand <code class="language-plaintext highlighter-rouge">mixMethod</code> is to inspect the component channels separately before looking at the colour image.</p>

<p>For a configuration such as</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">ensamMethod</span><span class="o">=</span><span class="p">[</span><span class="s">"kmeans"</span><span class="p">,</span> <span class="s">"gaussianMix"</span><span class="p">,</span> <span class="s">"factor"</span><span class="p">]</span>
</code></pre></div></div>

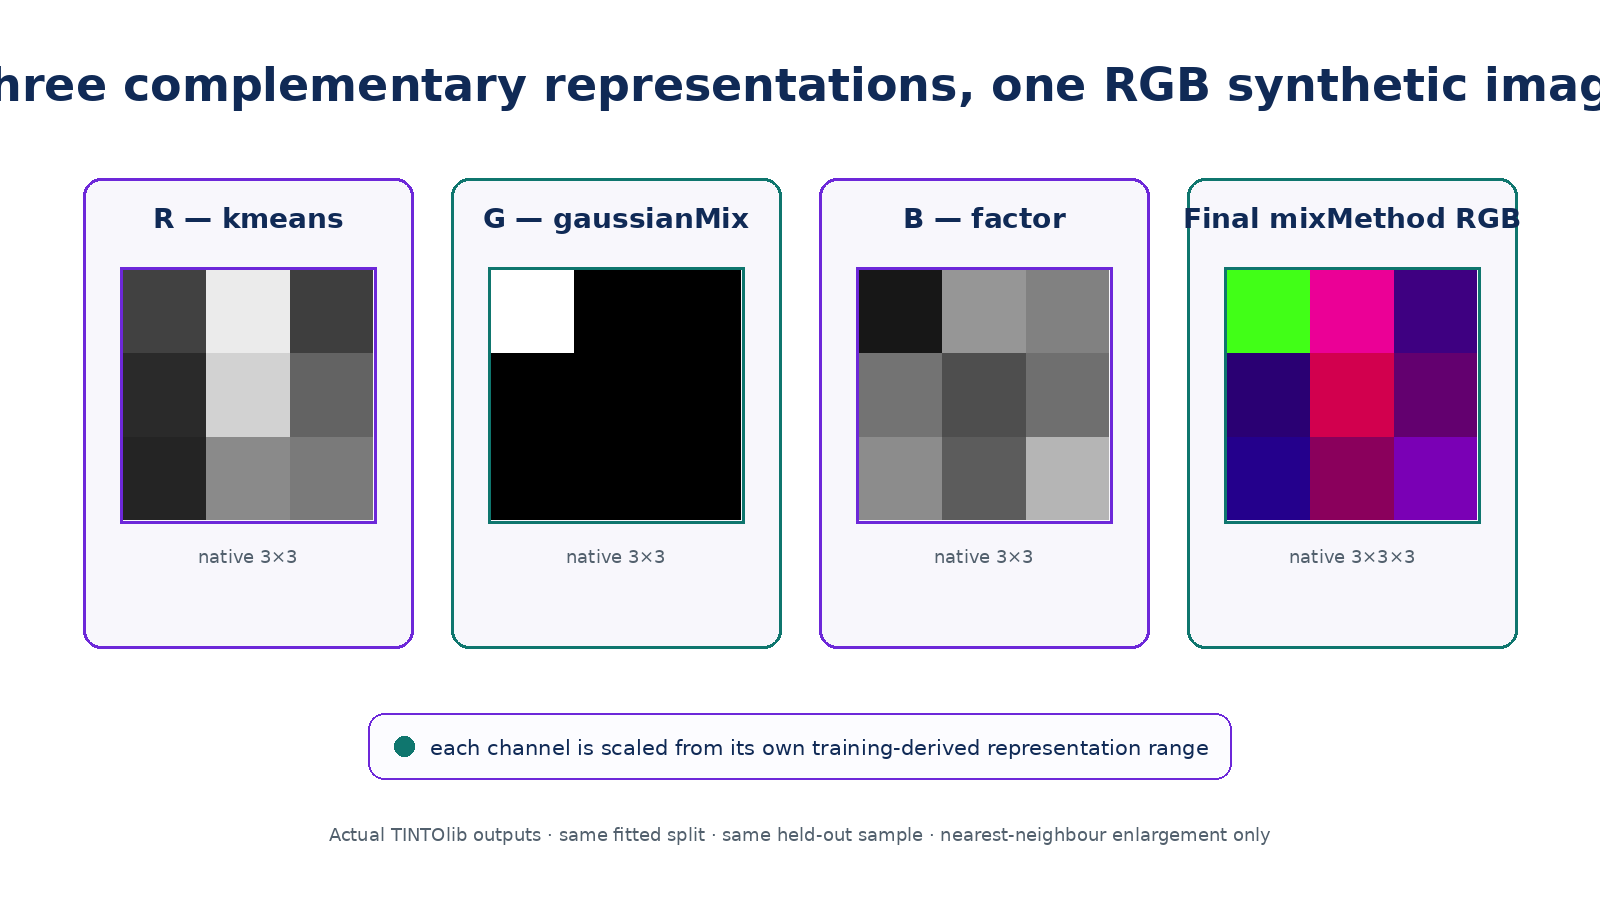
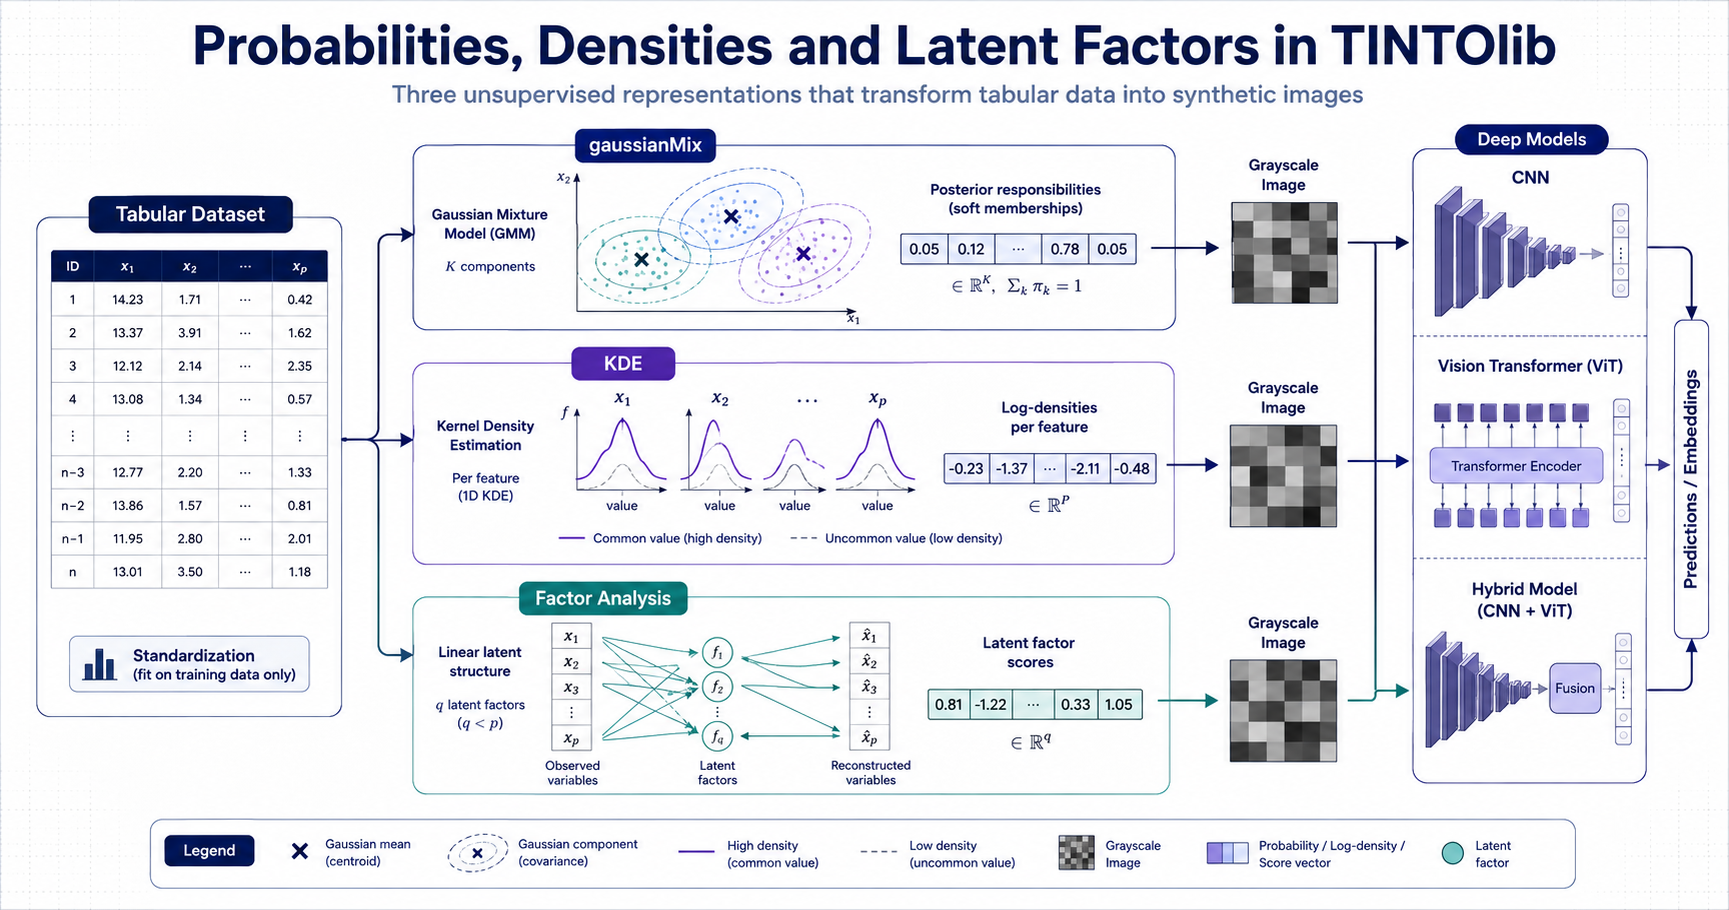
<p>the three channel matrices represent different numerical objects. Their final intensities are comparable as image values only after each method-specific <code class="language-plaintext highlighter-rouge">MinMaxScaler</code> has been fitted on the corresponding <strong>training representation</strong>.</p>

<p><img src="/images/Blog/2026-08-08-09-mixmethod-channels-rgb.png" alt="Individual TINTOlib channels and final RGB fusion" />
<em>(Figure 2. Actual TINTOlib outputs for one tabular sample. The red, green and blue source matrices correspond to the methods specified in <code class="language-plaintext highlighter-rouge">ensamMethod</code>, while the final panel shows their RGB fusion. The component values are scaled independently from training-derived ranges before channel stacking; the final colour therefore reflects multi-view interaction rather than a single physical quantity.)</em></p>

<h2 id="2-interpreting-colour-without-over-interpreting-it">2. Interpreting colour without over-interpreting it</h2>

<p>RGB fusion creates a visually richer image, but the colour itself must be interpreted carefully.</p>

<p>Consider a pixel at location $(u,v)$:</p>

\[\mathbf{p}_{uv}
=
\left[
R_{uv},
G_{uv},
B_{uv}
\right].\]

<p>If the channels correspond to <code class="language-plaintext highlighter-rouge">kmeans</code>, <code class="language-plaintext highlighter-rouge">gaussianMix</code> and <code class="language-plaintext highlighter-rouge">factor</code>, the three values do <strong>not</strong> measure the same quantity:</p>

<ul>
  <li>$R_{uv}$ may represent a centroid distance or RBF similarity;</li>
  <li>$G_{uv}$ may represent a posterior component responsibility;</li>
  <li>$B_{uv}$ may represent a latent-factor score after training-based scaling.</li>
</ul>

<p>Consequently, a purple, cyan or yellow region should not be interpreted as a predefined semantic class. It emerges from the numerical interaction of the selected channel values.</p>

<h3 id="channel-order-is-part-of-the-experimental-configuration">Channel order is part of the experimental configuration</h3>

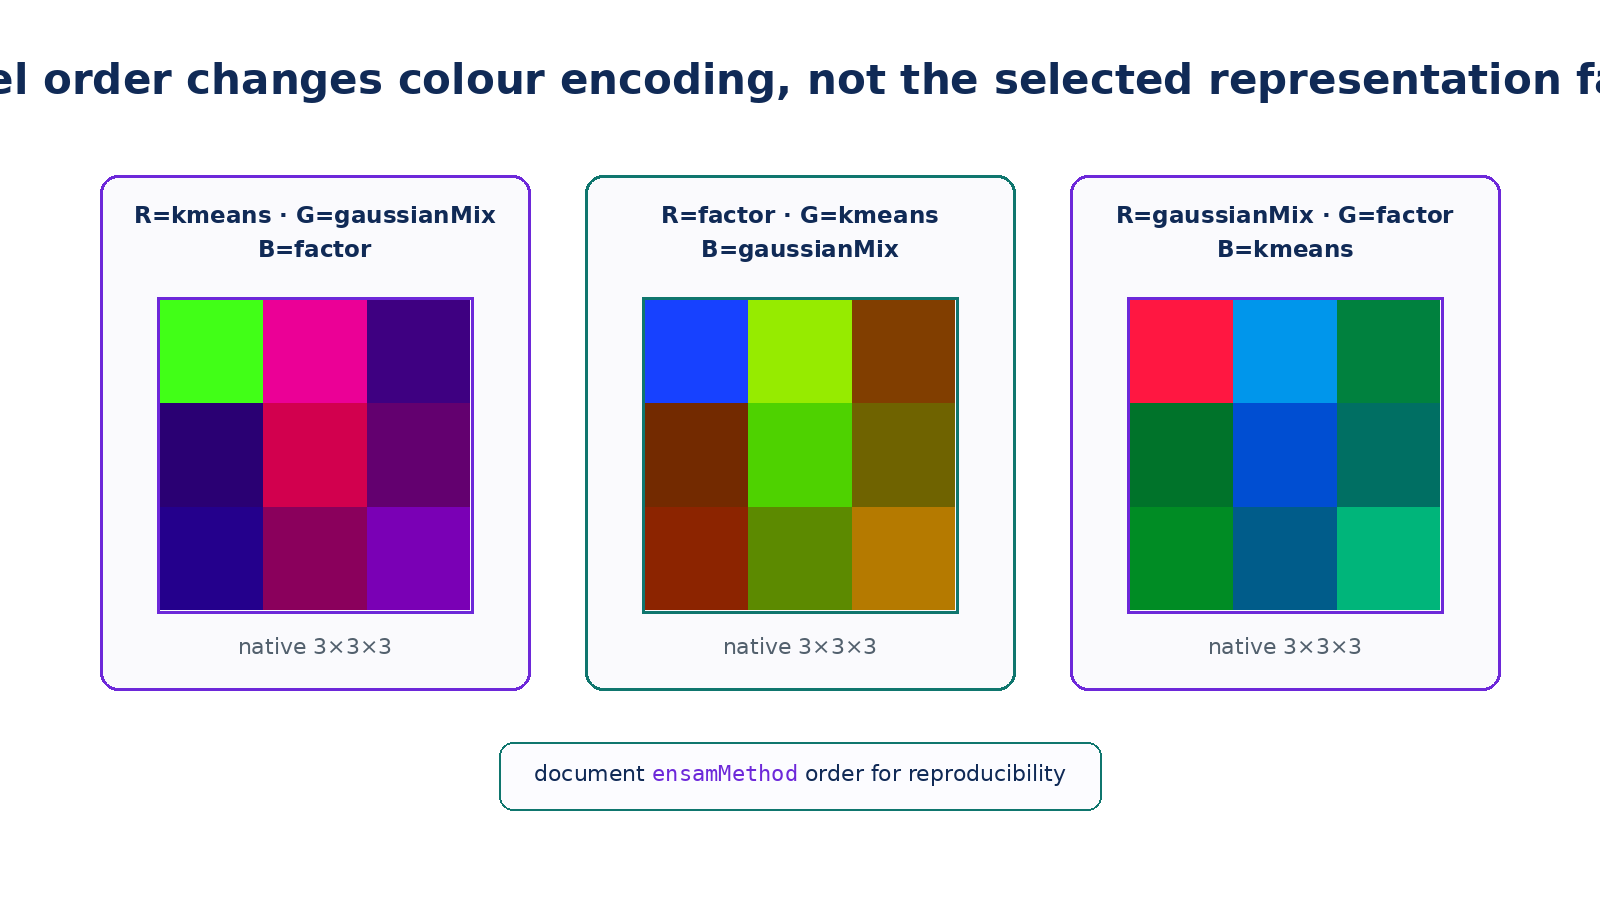
<p>Because <code class="language-plaintext highlighter-rouge">ensamMethod</code> determines the channel assignment, changing the order changes the visible colours even when the same three component representations are used.</p>

<p>For example,</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">[</span><span class="s">"kmeans"</span><span class="p">,</span> <span class="s">"gaussianMix"</span><span class="p">,</span> <span class="s">"factor"</span><span class="p">]</span>
</code></pre></div></div>

<p>and</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">[</span><span class="s">"factor"</span><span class="p">,</span> <span class="s">"kmeans"</span><span class="p">,</span> <span class="s">"gaussianMix"</span><span class="p">]</span>
</code></pre></div></div>

<p>contain the same three representational families but assign them to different colour axes.</p>

<p>This does not automatically mean that the underlying information has changed. It means that the <strong>RGB encoding has changed</strong>. For reproducible experiments, the exact order of <code class="language-plaintext highlighter-rouge">ensamMethod</code> should therefore be reported together with the remaining hyperparameters.</p>

<p><img src="/images/Blog/2026-08-08-09-channel-order-interpretation.png" alt="Channel order and interpretation in mixMethod" />
<em>(Figure 3. Channel interpretation in <code class="language-plaintext highlighter-rouge">mixMethod</code>. The order of <code class="language-plaintext highlighter-rouge">ensamMethod</code> determines which representation occupies R, G and B. Swapping channel assignments changes the visible colour composition even when the same underlying component representations are used. Channel order should therefore be treated as part of the documented experimental configuration.)</em></p>

<h2 id="practical-implementation-a-leakage-free-rgb-pipeline">Practical implementation: a leakage-free RGB pipeline</h2>

<p>The following example uses the Wine dataset and combines three complementary views:</p>

<ul>
  <li>k-means with Gaussian RBF similarity;</li>
  <li>Gaussian-mixture responsibilities;</li>
  <li>Factor Analysis scores.</li>
</ul>

<p>Nine components are used so that every channel forms a native $3\times3$ matrix without padding.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">pathlib</span> <span class="kn">import</span> <span class="n">Path</span>

<span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_wine</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>

<span class="kn">from</span> <span class="nn">TINTOlib.clusters</span> <span class="kn">import</span> <span class="n">Clusters</span>

<span class="c1"># ---------------------------------------------------------
# 1. Load a reproducible tabular dataset
# ---------------------------------------------------------
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_wine</span><span class="p">()</span>

<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span>
    <span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span>
    <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span>
<span class="p">)</span>

<span class="c1"># The target column must be the final column.
</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span>

<span class="c1"># ---------------------------------------------------------
# 2. Split BEFORE fitting the transformation
# ---------------------------------------------------------
</span><span class="n">train_df</span><span class="p">,</span> <span class="n">test_df</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">df</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.20</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="mi">42</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 3. Configure a three-view RGB representation
# ---------------------------------------------------------
</span><span class="n">model</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"mixMethod"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="mi">9</span><span class="p">,</span>
    <span class="n">ensamMethod</span><span class="o">=</span><span class="p">[</span>
        <span class="s">"kmeans"</span><span class="p">,</span>
        <span class="s">"gaussianMix"</span><span class="p">,</span>
        <span class="s">"factor"</span>
    <span class="p">],</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">n_init</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span>
    <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
    <span class="n">algorithmMethod</span><span class="o">=</span><span class="s">"lloyd"</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span><span class="p">,</span>
    <span class="n">covariance_type</span><span class="o">=</span><span class="s">"full"</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 4. Fit ONLY on training data
# ---------------------------------------------------------
</span><span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 5. Reuse the fitted transformation
# ---------------------------------------------------------
</span><span class="n">train_output</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images/mixMethod/train"</span><span class="p">)</span>
<span class="n">test_output</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images/mixMethod/test"</span><span class="p">)</span>

<span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
    <span class="n">train_df</span><span class="p">,</span>
    <span class="nb">str</span><span class="p">(</span><span class="n">train_output</span><span class="p">)</span>
<span class="p">)</span>

<span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
    <span class="n">test_df</span><span class="p">,</span>
    <span class="nb">str</span><span class="p">(</span><span class="n">test_output</span><span class="p">)</span>
<span class="p">)</span>

<span class="k">print</span><span class="p">(</span><span class="s">"RGB synthetic images generated successfully."</span><span class="p">)</span>
</code></pre></div></div>

<p>This workflow is leakage-free because the <code class="language-plaintext highlighter-rouge">StandardScaler</code>, the unsupervised component models and the channel-specific image scalers are learned from the training partition and reused for the test data.</p>

<h2 id="parameter-compatibility-in-mixmethod">Parameter compatibility in <code class="language-plaintext highlighter-rouge">mixMethod</code></h2>

<p>The admissible constructor parameters depend on the methods included in <code class="language-plaintext highlighter-rouge">ensamMethod</code>.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Component included</th>
      <th style="text-align: left">Relevant parameters</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmeans</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">random_seed</code>, <code class="language-plaintext highlighter-rouge">n_init</code>, <code class="language-plaintext highlighter-rouge">max_iter</code>, <code class="language-plaintext highlighter-rouge">algorithmMethod</code>, <code class="language-plaintext highlighter-rouge">RBFKmeans</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">gaussianMix</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">random_seed</code>, <code class="language-plaintext highlighter-rouge">n_init</code>, <code class="language-plaintext highlighter-rouge">max_iter</code>, <code class="language-plaintext highlighter-rouge">covariance_type</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">aggloKNN</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">metric</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmedoids</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">metric</code>, <code class="language-plaintext highlighter-rouge">random_seed</code>, <code class="language-plaintext highlighter-rouge">max_iter</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">factor</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">random_seed</code></td>
    </tr>
  </tbody>
</table>

<p>When <code class="language-plaintext highlighter-rouge">aggloKNN</code> or <code class="language-plaintext highlighter-rouge">kmedoids</code> is used inside <code class="language-plaintext highlighter-rouge">mixMethod</code>, the current shared metric validation for the combined method accepts <code class="language-plaintext highlighter-rouge">euclidean</code> or <code class="language-plaintext highlighter-rouge">manhattan</code>.</p>

<p>This illustrates a general design principle: <code class="language-plaintext highlighter-rouge">mixMethod</code> is not a free concatenation of arbitrary methods. The representations must remain dimensionally compatible and share a coherent image geometry.</p>

<h2 id="3-why-automatically-select-n_clusters">3. Why automatically select <code class="language-plaintext highlighter-rouge">n_clusters</code>?</h2>

<p>For most component-based methods, <code class="language-plaintext highlighter-rouge">n_clusters</code> controls more than the internal clustering model. It also controls the dimensionality of the representation and, indirectly, the image resolution.</p>

<p>For a representation with $k$ components,</p>

\[d = \left\lceil \sqrt{k} \right\rceil.\]

<p>Therefore:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">n_clusters</code></th>
      <th style="text-align: center">Native image side</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: center">9</td>
      <td style="text-align: center">$3\times3$</td>
    </tr>
    <tr>
      <td style="text-align: center">16</td>
      <td style="text-align: center">$4\times4$</td>
    </tr>
    <tr>
      <td style="text-align: center">25</td>
      <td style="text-align: center">$5\times5$</td>
    </tr>
    <tr>
      <td style="text-align: center">36</td>
      <td style="text-align: center">$6\times6$</td>
    </tr>
    <tr>
      <td style="text-align: center">49</td>
      <td style="text-align: center">$7\times7$</td>
    </tr>
    <tr>
      <td style="text-align: center">64</td>
      <td style="text-align: center">$8\times8$</td>
    </tr>
    <tr>
      <td style="text-align: center">81</td>
      <td style="text-align: center">$9\times9$</td>
    </tr>
  </tbody>
</table>

<p>Choosing $k$ therefore changes both the learned representation and the visual structure presented to the downstream neural network.</p>

<p>TINTOlib provides an automatic selection mechanism based on <strong>structural stability</strong> rather than only on an internal clustering objective.</p>

<h2 id="4-ssim-as-a-structural-stability-criterion">4. SSIM as a structural-stability criterion</h2>

<p>The Structural Similarity Index Measure (SSIM) compares two images by considering their luminance, contrast and structural organization.</p>

<p>Its interpretation in this context is straightforward:</p>

<ul>
  <li><strong>SSIM close to 1:</strong> the generated images remain structurally similar;</li>
  <li><strong>SSIM close to 0:</strong> the image structures differ substantially;</li>
  <li><strong>negative values:</strong> very strong structural disagreement may occur.</li>
</ul>

<p>TINTOlib uses SSIM to ask a specific question:</p>

<blockquote>
  <p><em>If the unsupervised model is initialized differently, does a given representation size still produce structurally similar synthetic images?</em></p>
</blockquote>

<p>This is different from asking whether a particular $k$ minimizes inertia, maximizes likelihood or achieves the best downstream predictive metric.</p>

<h3 id="current-automatic-selection-procedure">Current automatic-selection procedure</h3>

<p>For a compatible algorithm, <code class="language-plaintext highlighter-rouge">n_clusters</code> can be:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span>
</code></pre></div></div>

<p>a predefined list:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">n_clusters</span><span class="o">=</span><span class="p">[</span><span class="mi">9</span><span class="p">,</span> <span class="mi">16</span><span class="p">,</span> <span class="mi">25</span><span class="p">,</span> <span class="mi">36</span><span class="p">,</span> <span class="mi">49</span><span class="p">]</span>
</code></pre></div></div>

<p>or:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">n_clusters</span><span class="o">=</span><span class="s">"auto"</span>
</code></pre></div></div>

<p>When <code class="language-plaintext highlighter-rouge">"auto"</code> is used, the current candidate set is:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">[</span><span class="mi">9</span><span class="p">,</span> <span class="mi">16</span><span class="p">,</span> <span class="mi">25</span><span class="p">,</span> <span class="mi">36</span><span class="p">,</span> <span class="mi">49</span><span class="p">,</span> <span class="mi">64</span><span class="p">,</span> <span class="mi">81</span><span class="p">]</span>
</code></pre></div></div>

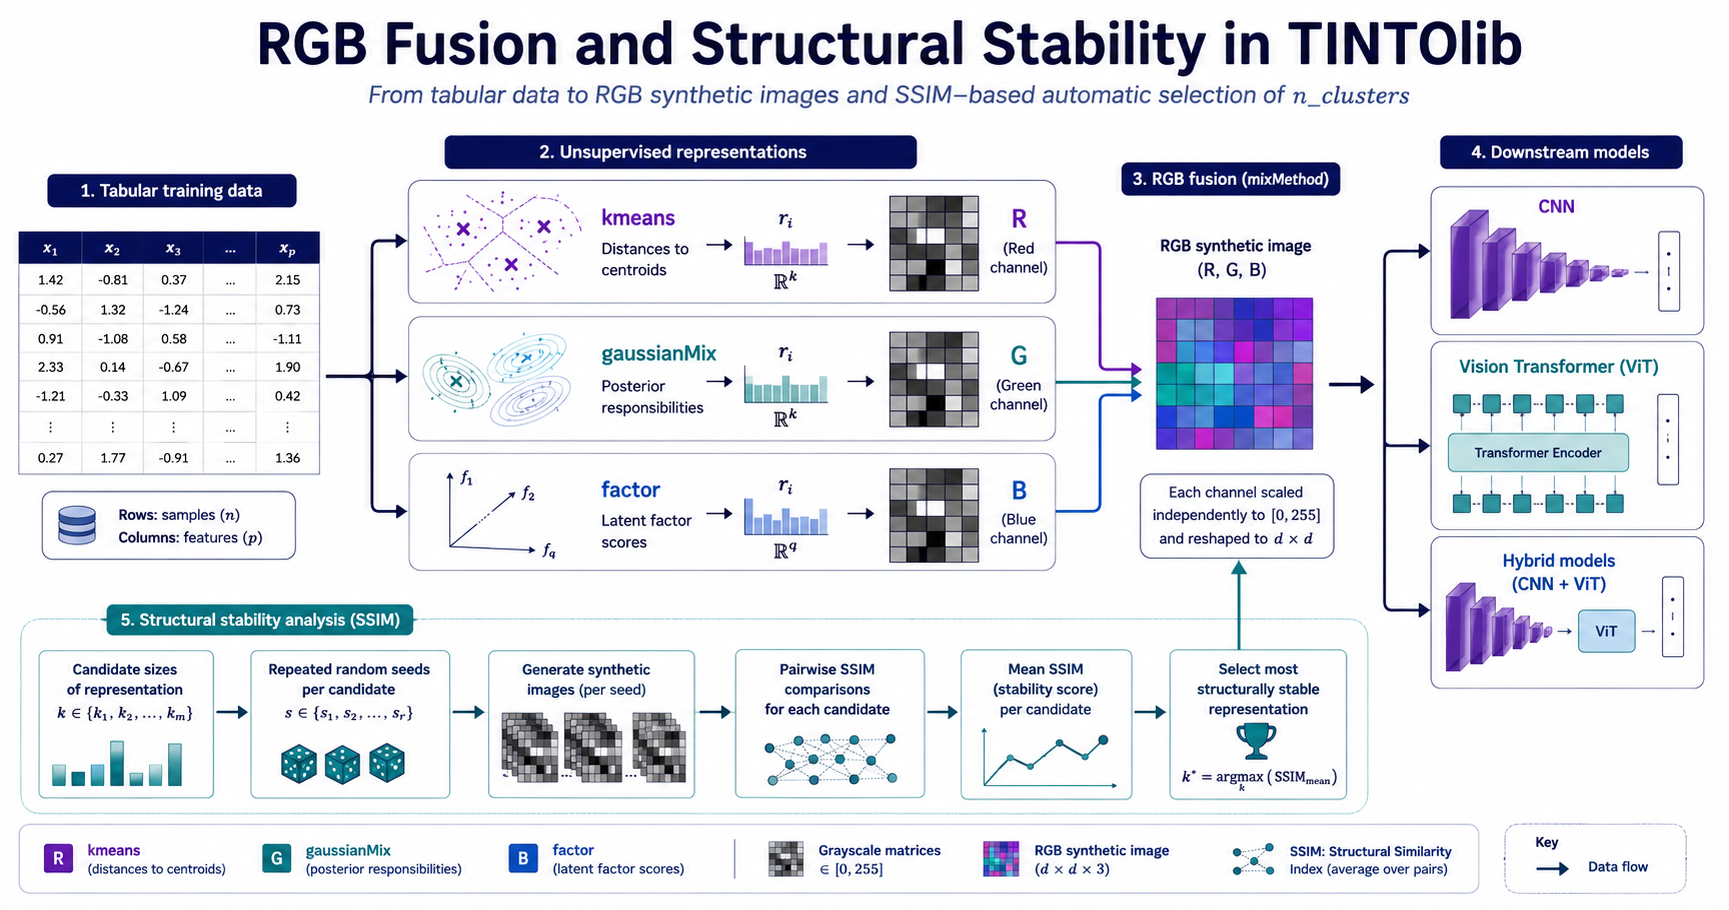
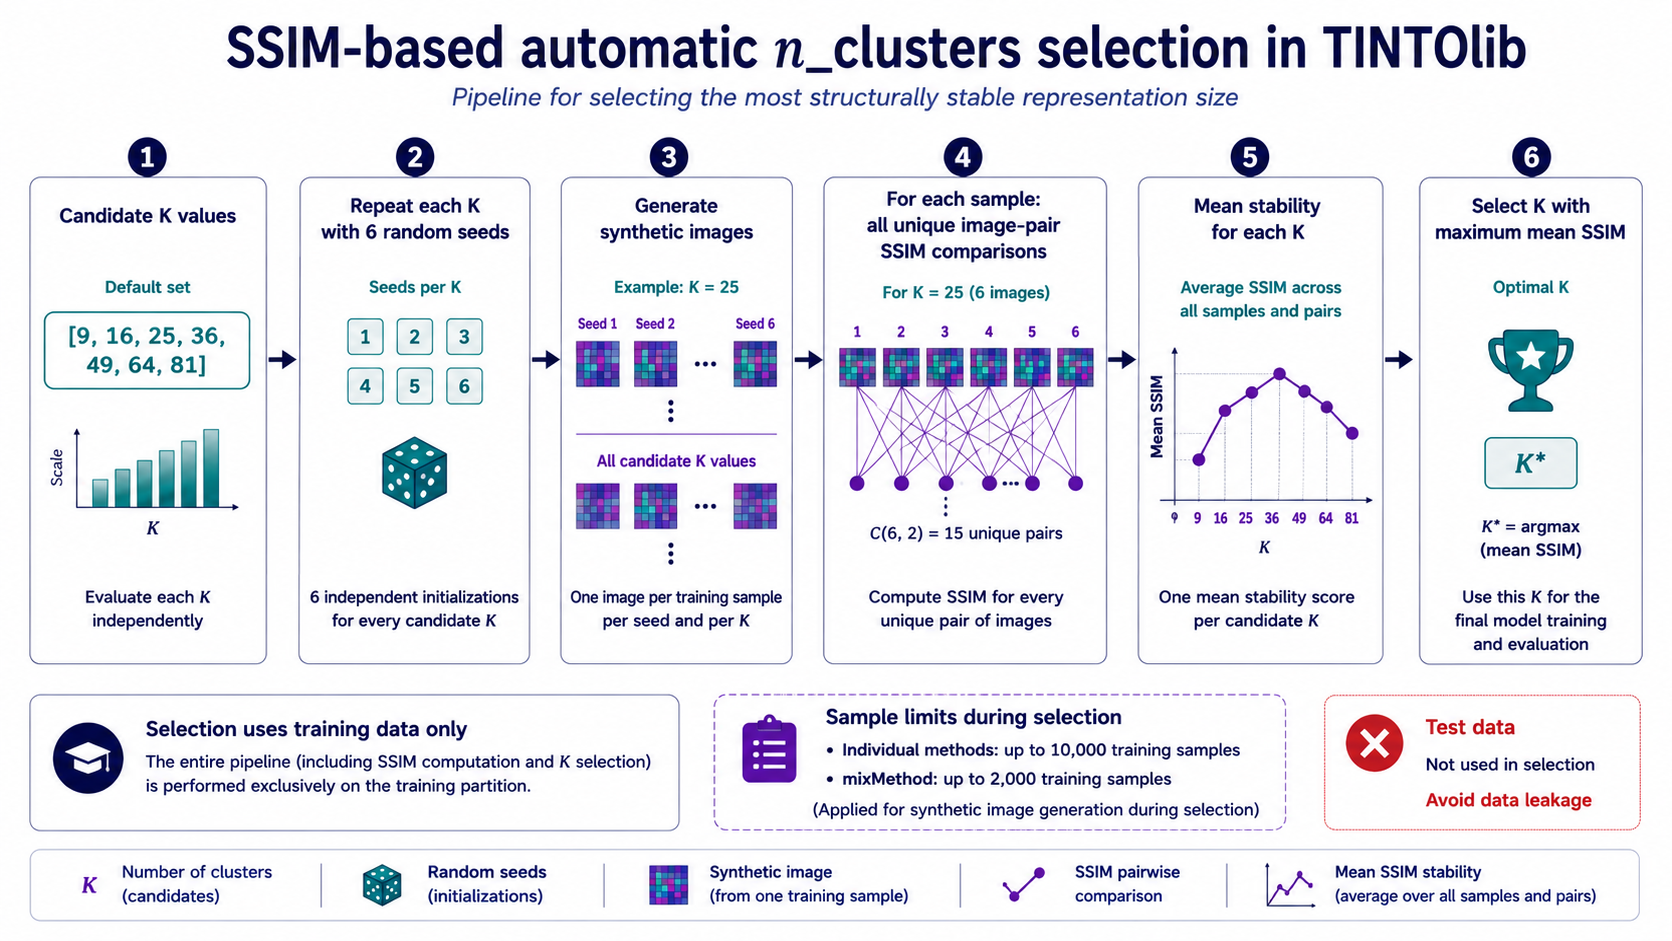
<p>The procedure implemented in TINTOlib can be summarized as follows:</p>

<ol>
  <li>Define the candidate values of $k$.</li>
  <li>For every candidate, fit the transformation under several random seeds.</li>
  <li>Convert every run into synthetic images.</li>
  <li>For every sample, compare all unique pairs of images obtained across seeds using SSIM.</li>
  <li>Average the pairwise similarities to obtain a per-sample stability score.</li>
  <li>Average across the evaluated samples.</li>
  <li>Select the $k$ with the highest mean structural stability.</li>
</ol>

<p>The current implementation calls this procedure with <strong>six random seeds</strong> during automatic fitting.</p>

<p>For computational reasons, the stability analysis uses at most the first:</p>

<ul>
  <li><strong>10,000 training instances</strong> for individual compatible methods;</li>
  <li><strong>2,000 training instances</strong> for <code class="language-plaintext highlighter-rouge">mixMethod</code>.</li>
</ul>

<p>When <code class="language-plaintext highlighter-rouge">factor</code> participates, candidate values are restricted by the maximum admissible latent dimensionality.</p>

<p><img src="/images/Blog/2026-08-08-09-ssim-selection-workflow.png" alt="SSIM-based automatic selection of n_clusters" />
<em>(Figure 4. SSIM-based selection of the representation dimension. For every candidate value of <code class="language-plaintext highlighter-rouge">n_clusters</code>, TINTOlib generates images under several random initializations, computes pairwise structural similarities for each sample, averages the stability scores and selects the candidate with the highest mean SSIM.)</em></p>

<h2 id="methods-for-which-automatic-selection-is-available">Methods for which automatic selection is available</h2>

<p>The current implementation enables SSIM-based automatic selection for:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">kmeans</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">kmedoids</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">gaussianMix</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">factor</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">mixMethod</code>.</li>
</ul>

<p>There are two important exceptions.</p>

<h3 id="kde">KDE</h3>

<p><code class="language-plaintext highlighter-rouge">kde</code> does not use <code class="language-plaintext highlighter-rouge">n_clusters</code>. Its representation dimension is determined directly by the number of original features. Therefore, there is no equivalent cluster-number hyperparameter to optimize through this procedure.</p>

<h3 id="aggloknn"><code class="language-plaintext highlighter-rouge">aggloKNN</code></h3>

<p>When used individually, <code class="language-plaintext highlighter-rouge">aggloKNN</code> does not support automatic <code class="language-plaintext highlighter-rouge">n_clusters</code> selection in the current implementation. Its hierarchical/KNN procedure is not driven by the same random initialization mechanism required by this stability experiment.</p>

<p>However, <code class="language-plaintext highlighter-rouge">aggloKNN</code> can participate inside <code class="language-plaintext highlighter-rouge">mixMethod</code>. In that case, the shared representation dimension is determined by the combined configuration, allowing channel compatibility to be maintained.</p>

<h2 id="practical-automatic-selection">Practical automatic selection</h2>

<p>For a single k-means representation:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">model</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="p">[</span><span class="mi">9</span><span class="p">,</span> <span class="mi">16</span><span class="p">,</span> <span class="mi">25</span><span class="p">,</span> <span class="mi">36</span><span class="p">,</span> <span class="mi">49</span><span class="p">],</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">n_init</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span>
    <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
<span class="p">)</span>

<span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

<span class="k">print</span><span class="p">(</span>
    <span class="s">"Selected n_clusters:"</span><span class="p">,</span>
    <span class="n">model</span><span class="p">.</span><span class="n">n_clusters</span>
<span class="p">)</span>
</code></pre></div></div>

<p>The same interface can be used with <code class="language-plaintext highlighter-rouge">"auto"</code>:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">model</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="s">"auto"</span><span class="p">,</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">n_init</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span>
    <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
<span class="p">)</span>

<span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>
</code></pre></div></div>

<h3 id="automatic-selection-for-an-rgb-representation">Automatic selection for an RGB representation</h3>

<p>With Wine, including <code class="language-plaintext highlighter-rouge">factor</code> strongly constrains the admissible values because the number of latent factors is bounded by the number of input variables. To illustrate a wider SSIM candidate grid, the following example combines methods whose representation dimensionality can share the same candidate values:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">model_rgb_auto</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"mixMethod"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="p">[</span><span class="mi">9</span><span class="p">,</span> <span class="mi">16</span><span class="p">,</span> <span class="mi">25</span><span class="p">,</span> <span class="mi">36</span><span class="p">,</span> <span class="mi">49</span><span class="p">],</span>
    <span class="n">ensamMethod</span><span class="o">=</span><span class="p">[</span>
        <span class="s">"kmeans"</span><span class="p">,</span>
        <span class="s">"gaussianMix"</span><span class="p">,</span>
        <span class="s">"kmedoids"</span>
    <span class="p">],</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">n_init</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span>
    <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
    <span class="n">algorithmMethod</span><span class="o">=</span><span class="s">"lloyd"</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span><span class="p">,</span>
    <span class="n">covariance_type</span><span class="o">=</span><span class="s">"full"</span><span class="p">,</span>
    <span class="n">metric</span><span class="o">=</span><span class="s">"euclidean"</span>
<span class="p">)</span>

<span class="n">model_rgb_auto</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

<span class="k">print</span><span class="p">(</span>
    <span class="s">"Selected RGB representation size:"</span><span class="p">,</span>
    <span class="n">model_rgb_auto</span><span class="p">.</span><span class="n">n_clusters</span>
<span class="p">)</span>
</code></pre></div></div>

<p>The selected value is the candidate that maximizes image stability under the SSIM procedure. It should <strong>not</strong> be interpreted automatically as the value that maximizes classification or regression performance.</p>

<h2 id="structural-stability-is-not-predictive-performance">Structural stability is not predictive performance</h2>

<p>This distinction is central.</p>

<p>A high SSIM score indicates that an image representation is reproducible under variations in random initialization. It does not demonstrate that:</p>

<ul>
  <li>a CNN will achieve higher accuracy;</li>
  <li>a Vision Transformer will generalize better;</li>
  <li>a hybrid network will obtain a lower error;</li>
  <li>or the representation preserves all information relevant to the target variable.</li>
</ul>

<p>SSIM is therefore best interpreted as a <strong>representation-stability criterion</strong>.</p>

<p>A complete experimental design should distinguish:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Question</th>
      <th style="text-align: left">Appropriate evaluation</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">Is the representation stable across random initializations?</td>
      <td style="text-align: left">SSIM</td>
    </tr>
    <tr>
      <td style="text-align: left">Does the representation preserve useful predictive information?</td>
      <td style="text-align: left">Downstream validation/test metrics</td>
    </tr>
    <tr>
      <td style="text-align: left">Is the method computationally feasible?</td>
      <td style="text-align: left">Fit/transform time and memory</td>
    </tr>
    <tr>
      <td style="text-align: left">Does the conclusion generalize?</td>
      <td style="text-align: left">Multiple datasets, seeds and architectures</td>
    </tr>
    <tr>
      <td style="text-align: left">Is every channel useful?</td>
      <td style="text-align: left">Channel ablation</td>
    </tr>
    <tr>
      <td style="text-align: left">Does RGB fusion add information beyond a single view?</td>
      <td style="text-align: left">Controlled single-channel versus multi-channel comparison</td>
    </tr>
  </tbody>
</table>

<h2 id="actual-stability-profiles-should-be-inspected">Actual stability profiles should be inspected</h2>

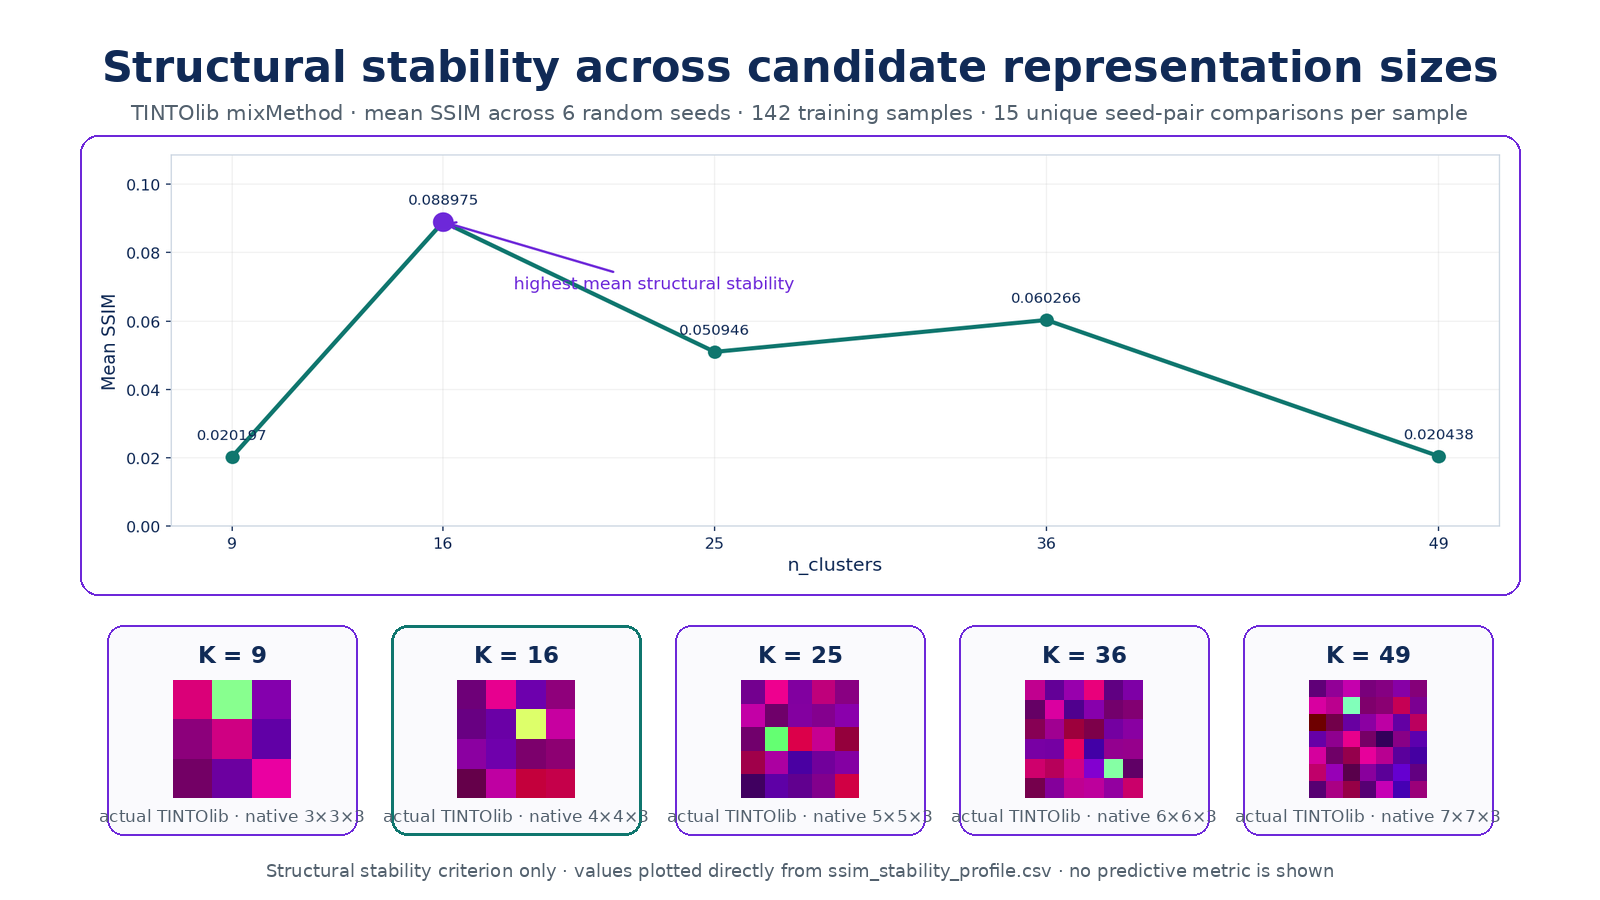
<p>The final decision should not be reduced to the selected integer alone. It is useful to inspect the full stability profile across candidate values.</p>

<p><img src="/images/Blog/2026-08-08-09-ssim-stability-comparison.png" alt="SSIM stability across candidate representation sizes" />
<em>(Figure 5. Example of a structural-stability analysis across candidate values of <code class="language-plaintext highlighter-rouge">n_clusters</code>. The plot should be generated from actual TINTOlib outputs using the same training partition and repeated random initializations. The selected value corresponds to the highest mean SSIM; the figure reports representation stability only and does not constitute a predictive-performance ranking.)</em></p>

<h2 id="methodological-cautions">Methodological cautions</h2>

<h3 id="1-automatic-selection-belongs-inside-the-training-pipeline">1. Automatic selection belongs inside the training pipeline</h3>

<p>The SSIM procedure must operate exclusively on the training partition. Candidate selection performed before the train/test split would expose the transformation-design stage to future evaluation samples.</p>

<p>The correct sequence remains:</p>

<ol>
  <li>split the original tabular dataset;</li>
  <li>fit <code class="language-plaintext highlighter-rouge">Clusters</code> on training data;</li>
  <li>allow <code class="language-plaintext highlighter-rouge">fit()</code> to select <code class="language-plaintext highlighter-rouge">n_clusters</code> from training data when requested;</li>
  <li>freeze the fitted transformation;</li>
  <li>transform validation and test partitions without refitting;</li>
  <li>evaluate the downstream architecture on untouched data.</li>
</ol>

<h3 id="2-channel-composition-is-itself-a-design-choice">2. Channel composition is itself a design choice</h3>

<p>A three-channel image does not automatically contain more useful information than a grayscale image. The selected component methods may be complementary, partially redundant or poorly matched to the downstream architecture.</p>

<p>Channel composition should therefore be studied through controlled ablations such as:</p>

<ul>
  <li>R only;</li>
  <li>R + G;</li>
  <li>R + B;</li>
  <li>G + B;</li>
  <li>R + G + B.</li>
</ul>

<h3 id="3-channel-ordering-must-be-documented">3. Channel ordering must be documented</h3>

<p>The same methods in a different <code class="language-plaintext highlighter-rouge">ensamMethod</code> order produce a different RGB colour assignment. Reproducible experiments should report both the selected methods and their exact order.</p>

<h3 id="4-independent-scaling-changes-the-meaning-of-intensity">4. Independent scaling changes the meaning of intensity</h3>

<p>Every component method has its own training-derived scaling operation. Therefore, identical intensity values in two channels do not imply identical pre-scaling numerical meaning.</p>

<h3 id="5-ssim-measures-visual-consistency-not-semantic-equivalence">5. SSIM measures visual consistency, not semantic equivalence</h3>

<p>Different unsupervised fits may produce representations that are mathematically related while differing in channel or component organization. SSIM quantifies the final image similarity and should therefore be interpreted specifically as a measure of <strong>output-image stability</strong>.</p>

<h2 id="how-should-mixmethod-be-evaluated">How should <code class="language-plaintext highlighter-rouge">mixMethod</code> be evaluated?</h2>

<p>The most informative experiment is not to compare one RGB configuration against one grayscale method and declare a winner.</p>

<p>A stronger protocol would include:</p>

<ol>
  <li>each selected component method independently;</li>
  <li>two-channel combinations;</li>
  <li>the complete three-channel representation;</li>
  <li>fixed versus SSIM-selected <code class="language-plaintext highlighter-rouge">n_clusters</code>;</li>
  <li>repeated random seeds;</li>
  <li>several downstream architectures;</li>
  <li>classical tabular baselines and an MLP;</li>
  <li>computational cost and storage requirements.</li>
</ol>

<p>The experimental work that motivated the new <code class="language-plaintext highlighter-rouge">Clusters</code> family used regression, binary-classification and multiclass-classification datasets with a specific Vision Transformer evaluation pipeline. Those results provide evidence for that particular experimental setting, but they do not establish a universal ordering among transformations.</p>

<p>The same representation may behave differently with:</p>

<ul>
  <li>CNNs;</li>
  <li>hybrid tabular–image architectures;</li>
  <li>alternative Vision Transformer configurations;</li>
  <li>different image resolutions;</li>
  <li>different optimizers or regularization strategies;</li>
  <li>datasets with different dimensionality and statistical structure.</li>
</ul>

<p>For that reason, this series focuses on <strong>what each representation encodes, how it is generated and how it should be evaluated</strong>, rather than identifying a universally superior method.</p>

<h2 id="closing-the-four-part-series">Closing the four-part series</h2>

<p>The four tutorials can now be read as a progression from single representations toward multi-view and stability-aware image generation.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Part</th>
      <th style="text-align: left">Central question</th>
      <th style="text-align: left">Main concepts</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>I — From Clusters to Pixels</strong></td>
      <td style="text-align: left">How can an unsupervised representation become an image?</td>
      <td style="text-align: left">Unified <code class="language-plaintext highlighter-rouge">Clusters</code> framework, seven algorithms, grayscale/RGB generation, leakage prevention</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>II — Distance-Based Encodings</strong></td>
      <td style="text-align: left">How can proximity and local structure become pixels?</td>
      <td style="text-align: left">k-means, k-medoids, aggloKNN, metrics, ordering, RBF</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>III — Probabilities, Densities and Latent Factors</strong></td>
      <td style="text-align: left">Which statistical quantities can replace raw distances?</td>
      <td style="text-align: left">Gaussian responsibilities, KDE densities, latent factor scores</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>IV — RGB Fusion and Structural Stability</strong></td>
      <td style="text-align: left">How can several views be fused and their representation size selected?</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">mixMethod</code>, channel semantics, RGB fusion, SSIM stability, automatic <code class="language-plaintext highlighter-rouge">n_clusters</code></td>
    </tr>
  </tbody>
</table>

<p>Taken together, the <code class="language-plaintext highlighter-rouge">Clusters</code> family provides a common framework for transforming heterogeneous unsupervised descriptions into image-like representations suitable for experimentation with computer-vision and hybrid neural architectures.</p>

<h2 id="limitations-and-future-directions">Limitations and future directions</h2>

<p>Several research directions remain open.</p>

<h3 id="automatic-channel-selection">Automatic channel selection</h3>

<p><code class="language-plaintext highlighter-rouge">mixMethod</code> currently receives an explicit <code class="language-plaintext highlighter-rouge">ensamMethod</code> list. Future work could investigate whether the most informative combination of representations can itself be selected automatically.</p>

<h3 id="beyond-fixed-rgb-fusion">Beyond fixed RGB fusion</h3>

<p>RGB channels provide a convenient three-view interface, but they impose a fixed maximum of three simultaneous representations. Learned fusion layers, multi-branch networks or token-level fusion could combine a larger number of views without forcing them into conventional colour channels.</p>

<h3 id="stability-and-predictive-utility">Stability and predictive utility</h3>

<p>SSIM evaluates structural consistency across random initializations. A future selection criterion could combine representation stability with downstream predictive evidence while maintaining a strictly leakage-free validation protocol.</p>

<h3 id="component-alignment">Component alignment</h3>

<p>Probabilistic and latent models may contain ordering or orientation ambiguities across independent fits. Alignment strategies could be investigated before structural-comparison procedures in order to separate genuine instability from equivalent but differently indexed representations.</p>

<h3 id="broader-neural-evaluation">Broader neural evaluation</h3>

<p>The experimental study behind these additions used a particular Vision Transformer architecture. Further work should systematically evaluate the methods with CNNs, hybrid tabular–image architectures, alternative ViTs and other visual backbones before drawing broad conclusions about their relative behaviour.</p>

<h3 id="explainable-multi-view-representations">Explainable multi-view representations</h3>

<p>Because each RGB channel has a known origin, attribution maps from the downstream visual model could potentially be decomposed by channel and connected back to centroid proximity, component responsibilities, medoid distances or latent factors. This creates a promising direction for explainable multi-view tabular learning.</p>

<h2 id="conclusion">Conclusion</h2>

<p><code class="language-plaintext highlighter-rouge">mixMethod</code> and SSIM-based automatic selection complete the conceptual framework introduced throughout this series.</p>

<p><code class="language-plaintext highlighter-rouge">mixMethod</code> combines up to three compatible unsupervised descriptions of the same sample in a single RGB image. The resulting colours are not arbitrary decorations: each channel originates from a different learned representation and must be interpreted according to its own statistical meaning.</p>

<p>The SSIM procedure addresses another design question: how large should the learned representation be? Instead of selecting <code class="language-plaintext highlighter-rouge">n_clusters</code> only from an internal clustering objective, TINTOlib can evaluate how structurally stable the final synthetic images remain across different random initializations.</p>

<p>Neither mechanism guarantees better predictive performance. They provide additional tools for designing, controlling and analysing synthetic representations of tabular data. Their value must ultimately be established through leakage-free experiments across datasets, seeds and downstream architectures.</p>

<p>The broader message of the series is therefore simple: <strong>representation design is part of the learning problem</strong>. Once tabular data are transformed into images, the transformation itself should be studied with the same rigor as the neural architecture that consumes those images.</p>

<hr />

<h2 id="references-and-resources">References and resources</h2>

<ol>
  <li>
    <p>Salvador Martínez Moreno. <strong>Generación de imágenes sintéticas mediante métodos no supervisados para la librería TINTOlib</strong>. Master’s Thesis, Universidad Nacional de Educación a Distancia (UNED), 2026.</p>
  </li>
  <li>
    <p>TINTOlib documentation. <strong>Clusters</strong>. <a href="https://tintolib.readthedocs.io/en/latest/clusters.html">Read the current parameter and API documentation</a>.</p>
  </li>
</ol>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-20-06-clusters-family-map.png" alt="Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-20T00:00:00+02:00">20 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Clusters" /><category term="Synthetic Images" /><category term="Tabular Data" /><category term="Unsupervised Learning" /><category term="RGB Fusion" /><category term="mixMethod" /><category term="Multi-View Learning" /><category term="Structural Similarity" /><category term="SSIM" /><category term="Automatic Model Selection" /><category term="Computer Vision" /><category term="Deep Learning" /><summary type="html"><![CDATA[Final tutorial in the TINTOlib Clusters series, covering RGB multi-view fusion with mixMethod, channel interpretation and automatic representation-size selection through SSIM-based structural stability.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</title><link href="https://www.manuelcastillo.eu/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/" rel="alternate" type="text/html" title="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" /><published>2026-08-06T00:00:00+02:00</published><updated>2026-08-06T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/08/08-probabilities-densities-latent-factors-gaussianmix-kde-factor</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/"><![CDATA[<div style="background: linear-gradient(135deg, #0f172a 0%, #312e81 42%, #6d28d9 67%, #0f766e 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #ddd6fe; font-weight: 600;">TINTOlib · Clusters · Probabilistic and Latent Encodings</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">Probabilities, Densities and Latent Factors</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #ede9fe; line-height: 1.55;">How Gaussian-mixture responsibilities, per-feature density estimates and latent-factor scores become grayscale synthetic images.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">gaussianMix</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">KDE</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">Factor Analysis</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f5f3ff;">Clusters</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 270px; width: 100%;">
    <img src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Probabilistic, density-based and latent-factor synthetic image representations in TINTOlib" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<h2 id="tutorial-metadata">Tutorial metadata</h2>

<ul>
  <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
  <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
  <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
  <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
</ul>

<hr />

<blockquote>
  <p><strong>Series note — Part III of IV.</strong> This article is the third entry in a four-part technical series on the unsupervised representations available through the TINTOlib <code class="language-plaintext highlighter-rouge">Clusters</code> class.</p>

  <ul>
    <li><strong><a href="https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Part I — From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib</a></strong></li>
    <li><strong><a href="https://www.manuelcastillo.eu/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part II — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a></strong></li>
    <li><strong>Part III — Probabilities, Densities and Latent Factors in TINTOlib:</strong> <code class="language-plaintext highlighter-rouge">gaussianMix</code>, <code class="language-plaintext highlighter-rouge">kde</code> and <code class="language-plaintext highlighter-rouge">factor</code> — this article.</li>
  </ul>

  <p>The fourth and final article will examine RGB fusion through <code class="language-plaintext highlighter-rouge">mixMethod</code>, channel interpretation and SSIM-based structural stability.</p>
</blockquote>

<h2 id="video-overview">Video overview</h2>

<p>The following short video summarizes the main concepts introduced in this article.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-08-06-08-probabilities-densities-latent-factors.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<h2 id="beyond-distances-three-alternative-views-of-tabular-structure">Beyond distances: three alternative views of tabular structure</h2>

<p>The distance-oriented methods discussed in Part II describe a sample through its proximity to centroids, medoids or locally constrained groups. The methods examined here answer different questions:</p>

<ul>
  <li><strong><code class="language-plaintext highlighter-rouge">gaussianMix</code>:</strong> how strongly does the sample belong to each probabilistic component?</li>
  <li><strong><code class="language-plaintext highlighter-rouge">kde</code>:</strong> how common or unusual is each observed feature value under its training distribution?</li>
  <li><strong><code class="language-plaintext highlighter-rouge">factor</code>:</strong> where is the sample located in a lower-dimensional latent space that explains shared variation among the original variables?</li>
</ul>

<p>These representations should not be interpreted as interchangeable. Their intermediate vectors have different dimensions, scales and semantics:</p>

\[\mathbf{x}_i \in \mathbb{R}^{p}
\quad \longrightarrow \quad
\mathbf{r}_i
\quad \longrightarrow \quad
\mathbf{I}_i \in \mathbb{R}^{d \times d}.\]

<p>For <code class="language-plaintext highlighter-rouge">gaussianMix</code>, the representation dimension is the number of Gaussian components, $q=k$. For <code class="language-plaintext highlighter-rouge">factor</code>, it is the number of latent factors, $q$. For <code class="language-plaintext highlighter-rouge">kde</code>, one estimator is fitted per original feature, so the representation remains $p$-dimensional.</p>

<p>The square side is calculated as</p>

\[d = \left\lceil \sqrt{\dim(\mathbf{r}_i)} \right\rceil,\]

<p>and zero-padding is added when the representation does not fill the complete $d \times d$ matrix.</p>

<p>A crucial interpretability distinction must be made. TINTOlib scales the intermediate values to $[0,255]$ using a <code class="language-plaintext highlighter-rouge">MinMaxScaler</code> fitted on the training representation. Therefore, the final pixel intensities preserve a relative encoding of the learned representation, but they are not raw calibrated probabilities, densities or signed factor scores.</p>

<p><img src="/images/Blog/2026-08-06-08-probabilities-densities-latent-factors.png" alt="Three families of non-distance representations" />
<em>(Figure 1. Three complementary mechanisms for constructing synthetic images from tabular data. <code class="language-plaintext highlighter-rouge">gaussianMix</code> represents a sample through posterior component responsibilities, <code class="language-plaintext highlighter-rouge">kde</code> replaces each feature value with its estimated density under the training distribution, and <code class="language-plaintext highlighter-rouge">factor</code> projects the sample onto a lower-dimensional latent space before pixel scaling and reshaping.)</em></p>
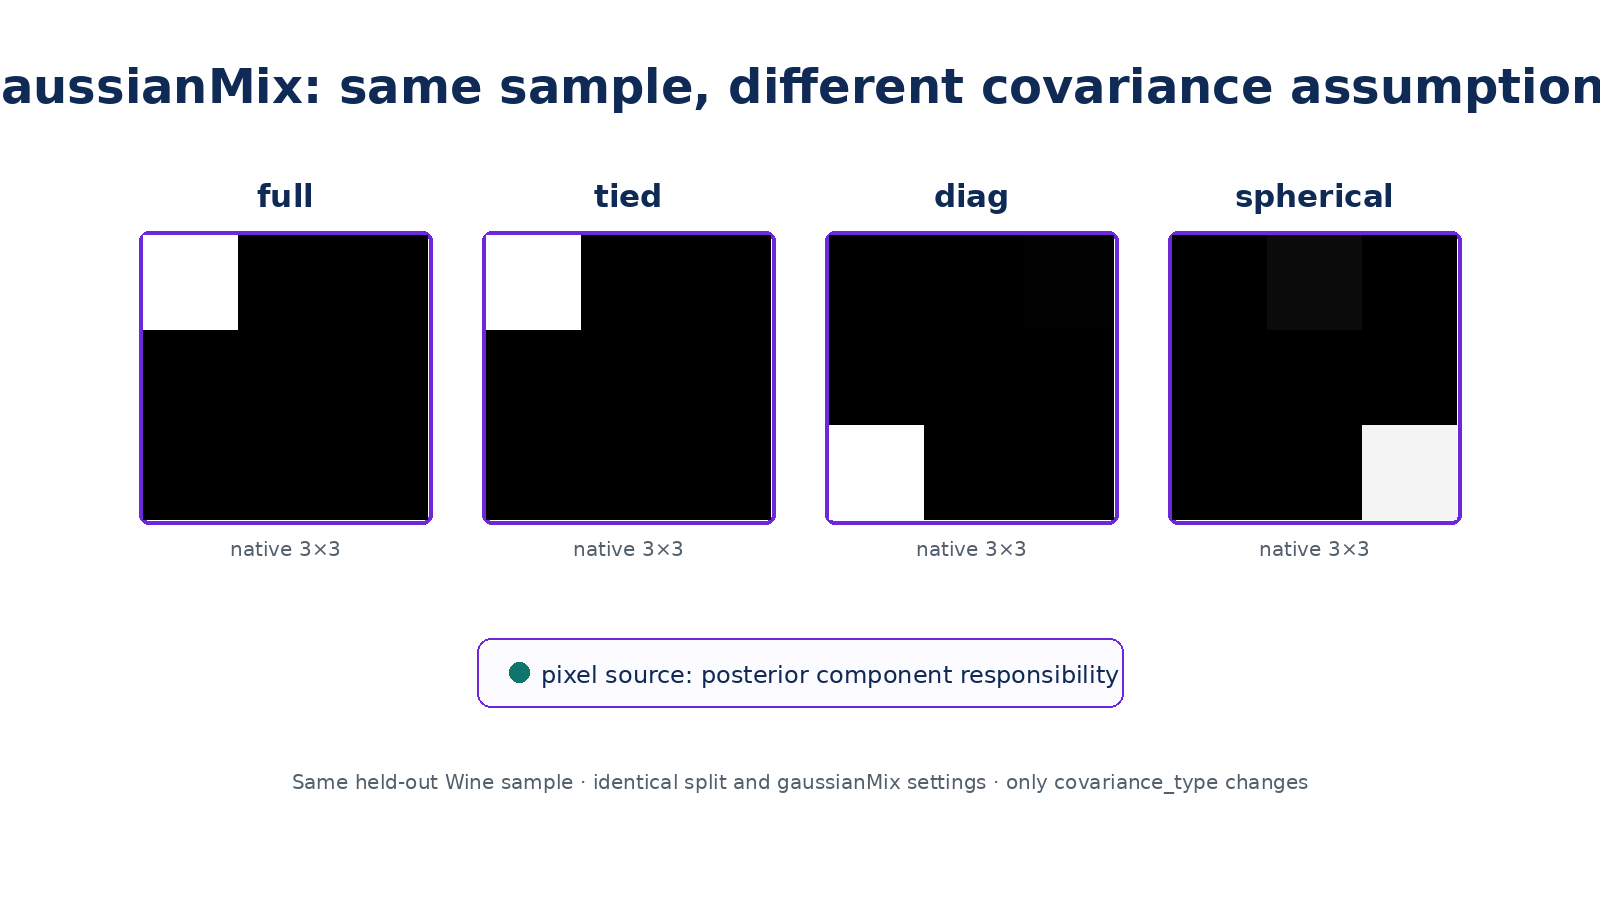
<h2 id="1-gaussianmix-posterior-responsibilities-as-pixels">1. <code class="language-plaintext highlighter-rouge">gaussianMix</code>: posterior responsibilities as pixels</h2>

<p>A Gaussian Mixture Model assumes that the observed data distribution can be approximated by a weighted combination of $k$ multivariate Gaussian components:</p>

\[p(\mathbf{x}) =
\sum_{j=1}^{k}
\pi_j
\mathcal{N}
\left(
\mathbf{x}\mid\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j
\right),\]

<p>where:</p>

<ul>
  <li>$\pi_j$ is the mixing weight of component $j$;</li>
  <li>$\boldsymbol{\mu}_j$ is its mean vector;</li>
  <li>$\boldsymbol{\Sigma}_j$ is its covariance structure;</li>
  <li>$\sum_{j=1}^{k}\pi_j=1$.</li>
</ul>

<p>Instead of assigning each sample to only one component, <code class="language-plaintext highlighter-rouge">gaussianMix</code> uses the complete posterior responsibility vector:</p>

\[\mathbf{r}^{(\mathrm{gmm})}_i =
\left(
\gamma_{i1},
\gamma_{i2},
\ldots,
\gamma_{ik}
\right),\]

<p>with</p>

\[\gamma_{ij}
=
P(z=j\mid\mathbf{x}_i)
=
\frac{
\pi_j
\mathcal{N}
\left(
\mathbf{x}_i\mid\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j
\right)
}{
\sum_{\ell=1}^{k}
\pi_\ell
\mathcal{N}
\left(
\mathbf{x}_i\mid\boldsymbol{\mu}_\ell,\boldsymbol{\Sigma}_\ell
\right)
}.\]

<p>Before pixel scaling,</p>

\[\sum_{j=1}^{k}\gamma_{ij}=1.\]

<p>The vector therefore describes both component affinity and assignment uncertainty. A sample near the centre of one Gaussian may have one dominant responsibility, whereas a sample near a boundary may distribute its probability mass across several components.</p>

<h3 id="main-parameters">Main parameters</h3>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Parameter</th>
      <th style="text-align: left">Role</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code></td>
      <td style="text-align: left">Number of Gaussian components and intermediate-vector dimensions</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">random_seed</code></td>
      <td style="text-align: left">Reproducibility of the fitted mixture</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_init</code></td>
      <td style="text-align: left">Number of EM initializations</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">max_iter</code></td>
      <td style="text-align: left">Maximum EM iterations for each initialization</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">covariance_type</code></td>
      <td style="text-align: left">Structure imposed on the component covariance matrices</td>
    </tr>
  </tbody>
</table>

<blockquote>
  <p><strong>Implementation note.</strong> In the current implementation, <code class="language-plaintext highlighter-rouge">n_init="auto"</code> is converted internally to one Gaussian-mixture initialization. Use an explicit integer such as <code class="language-plaintext highlighter-rouge">n_init=5</code> when several EM restarts are required.</p>
</blockquote>

<h3 id="covariance-structures">Covariance structures</h3>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Value</th>
      <th style="text-align: left">Covariance assumption</th>
      <th style="text-align: left">Representational implication</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">full</code></td>
      <td style="text-align: left">Every component has its own complete covariance matrix</td>
      <td style="text-align: left">Can model component-specific correlations and orientations</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">tied</code></td>
      <td style="text-align: left">All components share one complete covariance matrix</td>
      <td style="text-align: left">Different means, but a common covariance geometry</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">diag</code></td>
      <td style="text-align: left">Every component has its own diagonal covariance</td>
      <td style="text-align: left">Feature covariances are excluded within each component</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">spherical</code></td>
      <td style="text-align: left">Every component has one scalar variance</td>
      <td style="text-align: left">Most constrained and isotropic geometry</td>
    </tr>
  </tbody>
</table>

<p>The selected structure changes the learned component geometry and therefore the responsibility vector assigned to each sample.</p>

<p><img src="/images/Blog/2026-08-06-08-gaussian-covariance-types.png" alt="Gaussian-mixture covariance structures" />
<em>(Figure 2. Synthetic images generated from the same tabular sample using <code class="language-plaintext highlighter-rouge">gaussianMix</code> with <code class="language-plaintext highlighter-rouge">full</code>, <code class="language-plaintext highlighter-rouge">tied</code>, <code class="language-plaintext highlighter-rouge">diag</code> and <code class="language-plaintext highlighter-rouge">spherical</code> covariance structures. Every panel encodes posterior component responsibilities under a different geometric assumption; no configuration should be interpreted as universally preferable.)</em></p>
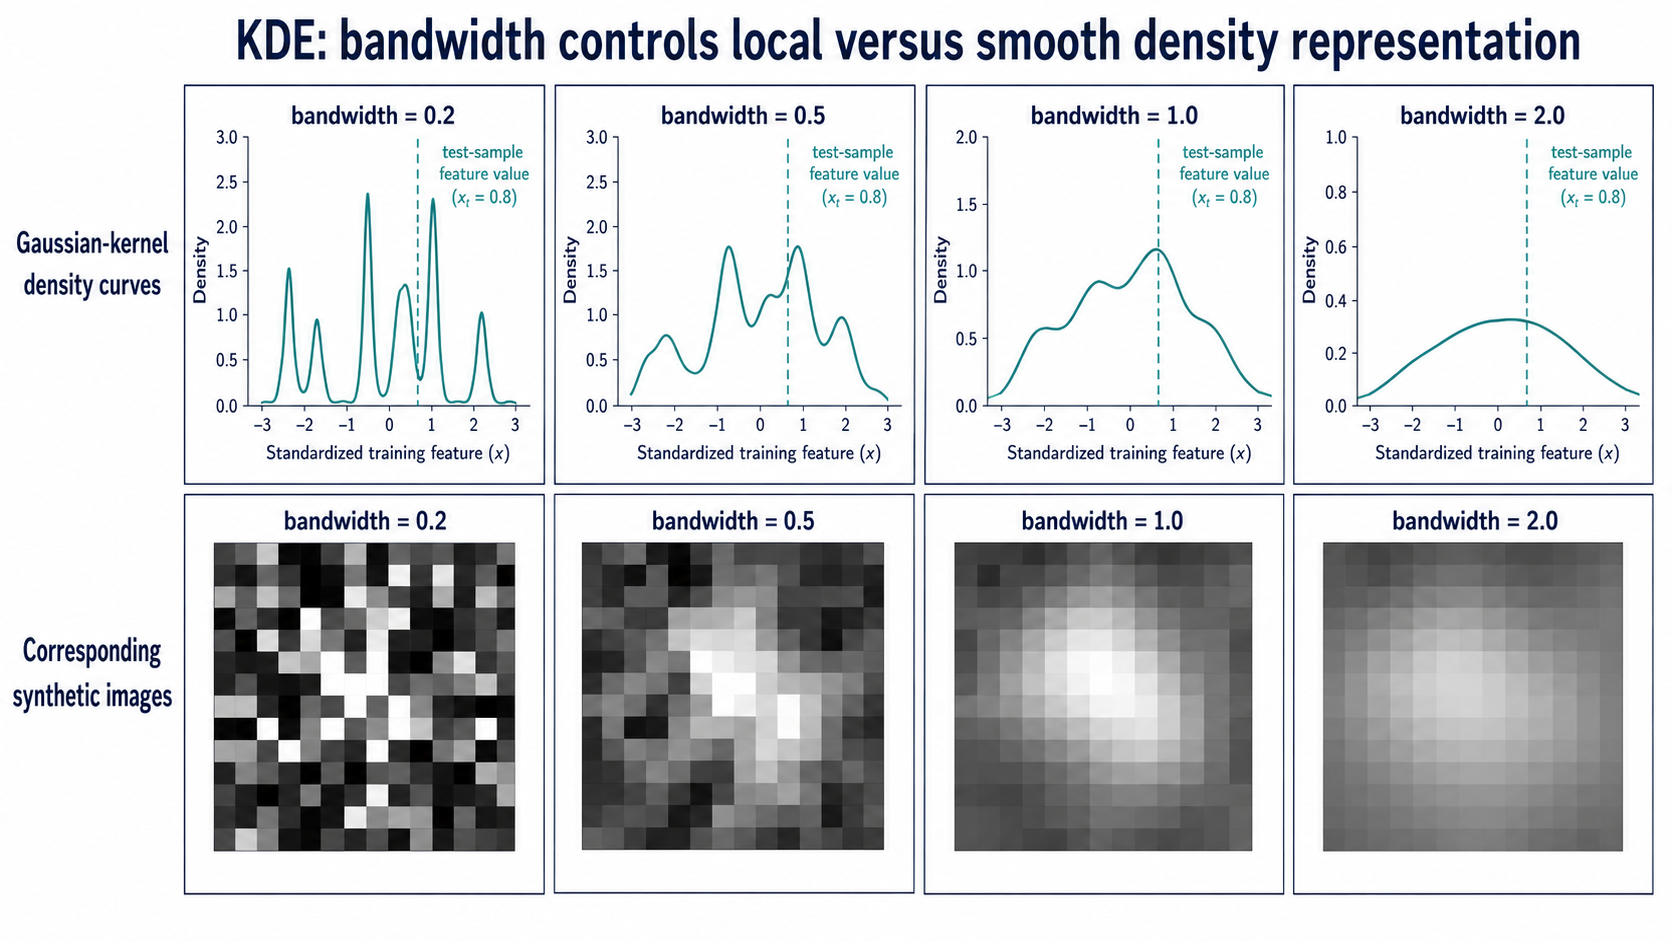
<h2 id="why-can-gaussian-mixture-images-look-highly-discrete">Why can Gaussian-mixture images look highly discrete?</h2>

<p>It is common for a fitted mixture to assign almost all posterior mass to one component:</p>

\[\mathbf{r}^{(\mathrm{gmm})}_i
\approx
(0,\ldots,0,1,0,\ldots,0).\]

<p>After training-based MinMax scaling, this may produce images dominated by very dark pixels and one or a few bright regions. This is not necessarily an implementation error. It may indicate:</p>

<ul>
  <li>well-separated Gaussian components;</li>
  <li>a sample located far from component boundaries;</li>
  <li>a covariance constraint that creates confident assignments;</li>
  <li>or an excessive number of components relative to the available data.</li>
</ul>

<p>Conversely, a more graded image can indicate overlapping components or greater assignment ambiguity. Neither visual pattern guarantees better downstream prediction. The representation must be evaluated together with the dataset and neural architecture.</p>

<p>Another methodological issue is component ordering. Gaussian component indices have no intrinsic semantic order and may be permuted across independently fitted models. Train, validation and test images remain consistent when they are transformed with the <strong>same fitted model</strong>, but comparisons across independent runs require care.</p>

<h2 id="2-kde-one-density-estimator-per-feature">2. <code class="language-plaintext highlighter-rouge">kde</code>: one density estimator per feature</h2>

<p>Kernel Density Estimation provides a non-parametric alternative. In the current TINTOlib implementation, a separate one-dimensional KDE model is fitted for every standardized input feature.</p>

<p>For feature $j$, containing training observations</p>

\[x_{1j},x_{2j},\ldots,x_{nj},\]

<p>the estimated density can be written as</p>

\[\widehat{f}_j(x)
=
\frac{1}{nh}
\sum_{m=1}^{n}
K\left(
\frac{x-x_{mj}}{h}
\right),\]

<p>where:</p>

<ul>
  <li>$K$ is the selected kernel;</li>
  <li>$h&gt;0$ is the bandwidth;</li>
  <li>$n$ is the number of training samples.</li>
</ul>

<p>For sample $\mathbf{x}_i$, the intermediate representation is</p>

\[\mathbf{r}^{(\mathrm{kde})}_i
=
\left(
\widehat{f}_1(x_{i1}),
\widehat{f}_2(x_{i2}),
\ldots,
\widehat{f}_p(x_{ip})
\right).\]

<p>Each component answers a feature-specific question: <strong>how dense is the training distribution around this observed value?</strong></p>

<p>This is not a joint multivariate probability for the complete sample. It is a collection of independent univariate density evaluations.</p>

<h3 id="main-parameters-1">Main parameters</h3>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Parameter</th>
      <th style="text-align: left">Role</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kernel</code></td>
      <td style="text-align: left">Shape of the local contribution centred on every training observation</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">bandwidth</code></td>
      <td style="text-align: left">Degree of smoothing applied to the estimated density</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">metric</code></td>
      <td style="text-align: left">Distance metric used by the KDE estimator</td>
    </tr>
  </tbody>
</table>

<p>Supported kernels are:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">gaussian</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">tophat</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">epanechnikov</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">exponential</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">linear</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">cosine</code>.</li>
</ul>

<p>Supported metrics are:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">euclidean</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">manhattan</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">chebyshev</code>.</li>
</ul>

<p>The implementation obtains log-density scores through <code class="language-plaintext highlighter-rouge">score_samples</code>, applies the exponential function and fits a <code class="language-plaintext highlighter-rouge">MinMaxScaler</code> on the resulting training densities.</p>

<h3 id="bandwidth-controls-the-representation-scale">Bandwidth controls the representation scale</h3>

<p>The bandwidth is usually the most influential KDE parameter.</p>

<ul>
  <li><strong>Small bandwidth:</strong> narrow local peaks, greater sensitivity to individual observations and potentially fragmented representations.</li>
  <li><strong>Large bandwidth:</strong> smoother densities, less local detail and more similar values across broad regions.</li>
</ul>

<p>A very small bandwidth may classify many test values as lying in low-density regions. A very large bandwidth may suppress potentially meaningful local structure.</p>

<p><img src="/images/Blog/2026-08-06-08-kde-bandwidth-kernels.png" alt="KDE kernels and bandwidth" />
<em>(Figure 3. Effect of kernel shape and bandwidth on the density representation used by <code class="language-plaintext highlighter-rouge">kde</code>. The curves must be estimated from the same standardized training feature. The associated synthetic-image panels show how local versus smooth density estimates alter the pixel intensities assigned to the same tabular sample.)</em></p>
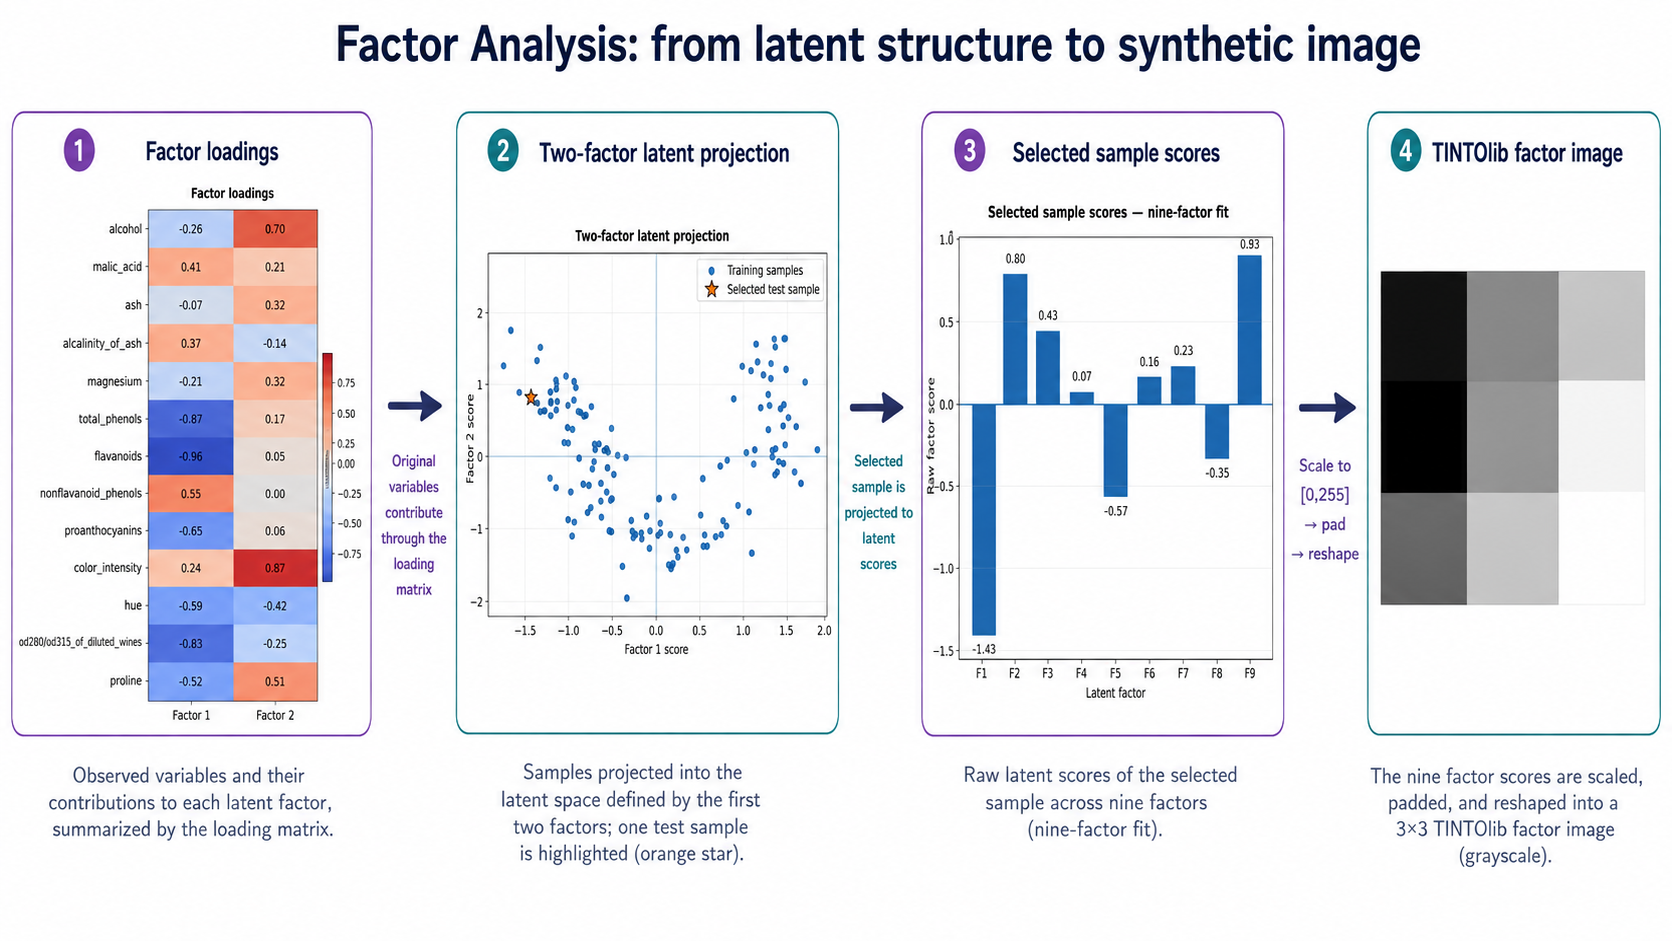
<h3 id="why-kde-has-a-different-image-size">Why KDE has a different image size</h3>

<p>Unlike the component-based methods, <code class="language-plaintext highlighter-rouge">kde</code> does not use <code class="language-plaintext highlighter-rouge">n_clusters</code>. Its intermediate vector contains one density value per original feature:</p>

\[\dim\left(
\mathbf{r}^{(\mathrm{kde})}_i
\right)=p.\]

<p>For the Wine dataset, which contains 13 input features,</p>

\[d=\left\lceil\sqrt{13}\right\rceil=4,\]

<p>so the resulting image has size $4\times4$, with three padded positions.</p>

<p>This property also explains why <code class="language-plaintext highlighter-rouge">kde</code> is not currently available as a channel inside <code class="language-plaintext highlighter-rouge">mixMethod</code>: its output dimensionality is determined by the dataset rather than by a shared number of components.</p>

<h3 id="interpreting-kde-pixels">Interpreting KDE pixels</h3>

<p>Before scaling:</p>

<ul>
  <li>a high density indicates that the feature value lies in a common region of its training distribution;</li>
  <li>a low density indicates a locally uncommon or potentially atypical value.</li>
</ul>

<p>After MinMax scaling, brightness expresses relative density according to the training-derived scaling range. It should not be interpreted as a probability that the complete sample is normal or anomalous.</p>

<h2 id="3-factor-latent-scores-as-a-compact-image-representation">3. <code class="language-plaintext highlighter-rouge">factor</code>: latent scores as a compact image representation</h2>

<p>Factor Analysis does not create groups or estimate feature-wise densities. It models the covariance structure of the observed variables through a smaller set of latent factors.</p>

<p>A standard formulation is</p>

\[\mathbf{x}_i
=
\boldsymbol{\mu}
+
\mathbf{\Lambda}\mathbf{z}_i
+
\boldsymbol{\varepsilon}_i,\]

<p>where:</p>

<ul>
  <li>$\mathbf{x}_i\in\mathbb{R}^{p}$ is the observed sample;</li>
  <li>$\boldsymbol{\mu}$ is the feature mean vector;</li>
  <li>$\mathbf{z}_i\in\mathbb{R}^{q}$ is the latent-factor score vector;</li>
  <li>$\mathbf{\Lambda}\in\mathbb{R}^{p\times q}$ is the loading matrix;</li>
  <li>$\boldsymbol{\varepsilon}_i$ represents feature-specific variation not explained by the common factors.</li>
</ul>

<p>TINTOlib uses the transformed factor scores as the intermediate representation:</p>

\[\mathbf{r}^{(\mathrm{factor})}_i
=
\mathbf{z}_i
=
\left(
z_{i1},
z_{i2},
\ldots,
z_{iq}
\right).\]

<p>The API retains the parameter name <code class="language-plaintext highlighter-rouge">n_clusters</code>, but for <code class="language-plaintext highlighter-rouge">factor</code> it means the <strong>number of latent factors</strong>, not the number of clusters.</p>

<h3 id="main-parameters-2">Main parameters</h3>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Parameter</th>
      <th style="text-align: left">Role</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code></td>
      <td style="text-align: left">Number of latent factors and output dimensions</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">random_seed</code></td>
      <td style="text-align: left">Reproducibility of the Factor Analysis fit</td>
    </tr>
  </tbody>
</table>

<p>The current implementation requires</p>

\[q \leq p-1.\]

<p>For example, a dataset with 13 original features can use at most 12 factors in the current <code class="language-plaintext highlighter-rouge">Clusters</code> implementation.</p>

<p><img src="/images/Blog/2026-08-06-08-factor-analysis-latent-space.png" alt="Factor Analysis latent representation" />
<em>(Figure 4. Factor Analysis representation used by TINTOlib. The fitted loading matrix relates original variables to latent factors, every sample is projected into the factor-score space, and the resulting score vector is scaled and reshaped into a grayscale synthetic image.)</em></p>

<h3 id="scores-loadings-and-pixel-meaning">Scores, loadings and pixel meaning</h3>

<p>Two quantities must be distinguished:</p>

<ul>
  <li><strong>factor loadings:</strong> describe how the original variables contribute to the latent factors;</li>
  <li><strong>factor scores:</strong> describe where each sample lies in the learned latent space.</li>
</ul>

<p>The image is generated from the <strong>factor scores</strong>, not directly from the loading matrix. The loadings can nevertheless support interpretation by relating each pixel/factor back to influential original variables.</p>

<p>Raw factor scores may be positive or negative. After MinMax scaling, a pixel value of 0 or 255 represents an extreme relative to the training score range; it does not directly mean negative or positive contribution. The original sign and zero reference are not visually preserved by the final unsigned 8-bit image.</p>

<p>Factor models also have orientation ambiguities: independently fitted solutions can differ in factor sign or ordering while describing an equivalent latent structure. Consequently, comparisons should reuse the same fitted model for train, validation and test data.</p>

<h2 id="comparative-view">Comparative view</h2>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Property</th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">gaussianMix</code></th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">kde</code></th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">factor</code></th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>Representation family</strong></td>
      <td style="text-align: left">Probabilistic mixture</td>
      <td style="text-align: left">Non-parametric density</td>
      <td style="text-align: left">Latent structure</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Intermediate values</strong></td>
      <td style="text-align: left">Posterior component responsibilities</td>
      <td style="text-align: left">Per-feature density estimates</td>
      <td style="text-align: left">Factor scores</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Dimensionality</strong></td>
      <td style="text-align: left">Number of Gaussian components</td>
      <td style="text-align: left">Number of original features</td>
      <td style="text-align: left">Number of latent factors</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Primary question</strong></td>
      <td style="text-align: left">Which mixture regions explain the sample?</td>
      <td style="text-align: left">How common is each feature value?</td>
      <td style="text-align: left">Which latent dimensions describe the sample?</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Main parameters</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">covariance_type</code>, <code class="language-plaintext highlighter-rouge">n_init</code>, <code class="language-plaintext highlighter-rouge">max_iter</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kernel</code>, <code class="language-plaintext highlighter-rouge">bandwidth</code>, <code class="language-plaintext highlighter-rouge">metric</code></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">random_seed</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Typical visual behaviour</strong></td>
      <td style="text-align: left">Can become sparse or nearly one-hot</td>
      <td style="text-align: left">Reflects common versus locally unusual values</td>
      <td style="text-align: left">Compact contrasts across latent dimensions</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Automatic <code class="language-plaintext highlighter-rouge">n_clusters</code> selection</strong></td>
      <td style="text-align: left">Supported</td>
      <td style="text-align: left">Not applicable</td>
      <td style="text-align: left">Supported</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Available in <code class="language-plaintext highlighter-rouge">mixMethod</code></strong></td>
      <td style="text-align: left">Yes</td>
      <td style="text-align: left">No</td>
      <td style="text-align: left">Yes</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Key interpretability caution</strong></td>
      <td style="text-align: left">Component indices are arbitrary</td>
      <td style="text-align: left">Densities are feature-wise, not a joint sample probability</td>
      <td style="text-align: left">Pixel intensities hide the original score sign</td>
    </tr>
  </tbody>
</table>

<p>This table describes representational differences, not a performance ranking.</p>

<h2 id="practical-implementation-with-a-leakage-free-split">Practical implementation with a leakage-free split</h2>

<p>The following example generates the three representations from the same Wine dataset split.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">pathlib</span> <span class="kn">import</span> <span class="n">Path</span>

<span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_wine</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>

<span class="kn">from</span> <span class="nn">TINTOlib.clusters</span> <span class="kn">import</span> <span class="n">Clusters</span>

<span class="c1"># ---------------------------------------------------------
# 1. Load a reproducible tabular dataset
# ---------------------------------------------------------
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_wine</span><span class="p">()</span>

<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span>
    <span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span>
    <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span>
<span class="p">)</span>

<span class="c1"># The target column must be the final column.
</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span>

<span class="c1"># ---------------------------------------------------------
# 2. Split before fitting any unsupervised transformation
# ---------------------------------------------------------
</span><span class="n">train_df</span><span class="p">,</span> <span class="n">test_df</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">df</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.20</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="mi">42</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 3. Configure the three representations
# ---------------------------------------------------------
</span><span class="n">models</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"gaussianMix_full"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"gaussianMix"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">9</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
        <span class="n">n_init</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span>
        <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
        <span class="n">covariance_type</span><span class="o">=</span><span class="s">"full"</span>
    <span class="p">),</span>

    <span class="s">"kde_gaussian"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kde"</span><span class="p">,</span>
        <span class="n">kernel</span><span class="o">=</span><span class="s">"gaussian"</span><span class="p">,</span>
        <span class="n">bandwidth</span><span class="o">=</span><span class="mf">0.5</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"euclidean"</span>
    <span class="p">),</span>

    <span class="s">"factor_9"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"factor"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">9</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span>
    <span class="p">)</span>
<span class="p">}</span>

<span class="c1"># ---------------------------------------------------------
# 4. Fit only on training data and reuse each fitted model
# ---------------------------------------------------------
</span><span class="k">for</span> <span class="n">name</span><span class="p">,</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">models</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
    <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Generating images with </span><span class="si">{</span><span class="n">name</span><span class="si">}</span><span class="s">..."</span><span class="p">)</span>

    <span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

    <span class="n">train_folder</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images"</span><span class="p">)</span> <span class="o">/</span> <span class="n">name</span> <span class="o">/</span> <span class="s">"train"</span>
    <span class="n">test_folder</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images"</span><span class="p">)</span> <span class="o">/</span> <span class="n">name</span> <span class="o">/</span> <span class="s">"test"</span>

    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">train_df</span><span class="p">,</span> <span class="nb">str</span><span class="p">(</span><span class="n">train_folder</span><span class="p">))</span>
    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">test_df</span><span class="p">,</span> <span class="nb">str</span><span class="p">(</span><span class="n">test_folder</span><span class="p">))</span>

<span class="k">print</span><span class="p">(</span><span class="s">"Probabilistic, density and latent images generated successfully."</span><span class="p">)</span>
</code></pre></div></div>

<p>With these configurations:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">gaussianMix</code> generates nine responsibilities and therefore a $3\times3$ image;</li>
  <li><code class="language-plaintext highlighter-rouge">factor</code> generates nine latent scores and therefore a $3\times3$ image;</li>
  <li><code class="language-plaintext highlighter-rouge">kde</code> generates 13 density values for Wine and therefore a padded $4\times4$ image.</li>
</ul>

<p>The image sizes are not automatically equivalent. A visual or predictive comparison must acknowledge this difference rather than resize or crop the representations without documenting the operation.</p>

<h2 id="exploring-gaussian-covariance-structures">Exploring Gaussian covariance structures</h2>

<p>Use the same split, sample and number of components when comparing covariance assumptions:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">covariance_models</span> <span class="o">=</span> <span class="p">{</span>
    <span class="n">covariance_type</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"gaussianMix"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">9</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
        <span class="n">n_init</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span>
        <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
        <span class="n">covariance_type</span><span class="o">=</span><span class="n">covariance_type</span>
    <span class="p">)</span>
    <span class="k">for</span> <span class="n">covariance_type</span> <span class="ow">in</span> <span class="p">[</span>
        <span class="s">"full"</span><span class="p">,</span>
        <span class="s">"tied"</span><span class="p">,</span>
        <span class="s">"diag"</span><span class="p">,</span>
        <span class="s">"spherical"</span>
    <span class="p">]</span>
<span class="p">}</span>

<span class="k">for</span> <span class="n">covariance_type</span><span class="p">,</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">covariance_models</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
    <span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
        <span class="n">test_df</span><span class="p">,</span>
        <span class="sa">f</span><span class="s">"synthetic_images/gaussianMix_</span><span class="si">{</span><span class="n">covariance_type</span><span class="si">}</span><span class="s">/test"</span>
    <span class="p">)</span>
</code></pre></div></div>

<p>Do not compare images generated from independently changed splits or sample indices. Otherwise, visual differences cannot be attributed specifically to <code class="language-plaintext highlighter-rouge">covariance_type</code>.</p>

<h2 id="exploring-kde-kernels-and-bandwidth">Exploring KDE kernels and bandwidth</h2>

<p>A controlled KDE experiment should vary one parameter at a time:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">bandwidth_models</span> <span class="o">=</span> <span class="p">{</span>
    <span class="sa">f</span><span class="s">"gaussian_bw_</span><span class="si">{</span><span class="n">bandwidth</span><span class="si">}</span><span class="s">"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kde"</span><span class="p">,</span>
        <span class="n">kernel</span><span class="o">=</span><span class="s">"gaussian"</span><span class="p">,</span>
        <span class="n">bandwidth</span><span class="o">=</span><span class="n">bandwidth</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"euclidean"</span>
    <span class="p">)</span>
    <span class="k">for</span> <span class="n">bandwidth</span> <span class="ow">in</span> <span class="p">[</span><span class="mf">0.2</span><span class="p">,</span> <span class="mf">0.5</span><span class="p">,</span> <span class="mf">1.0</span><span class="p">,</span> <span class="mf">2.0</span><span class="p">]</span>
<span class="p">}</span>

<span class="k">for</span> <span class="n">name</span><span class="p">,</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">bandwidth_models</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
    <span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>
    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
        <span class="n">test_df</span><span class="p">,</span>
        <span class="sa">f</span><span class="s">"synthetic_images/</span><span class="si">{</span><span class="n">name</span><span class="si">}</span><span class="s">/test"</span>
    <span class="p">)</span>
</code></pre></div></div>

<p>A separate kernel comparison can keep <code class="language-plaintext highlighter-rouge">bandwidth=0.5</code> fixed and vary:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">kernels</span> <span class="o">=</span> <span class="p">[</span>
    <span class="s">"gaussian"</span><span class="p">,</span>
    <span class="s">"tophat"</span><span class="p">,</span>
    <span class="s">"epanechnikov"</span><span class="p">,</span>
    <span class="s">"exponential"</span><span class="p">,</span>
    <span class="s">"linear"</span><span class="p">,</span>
    <span class="s">"cosine"</span>
<span class="p">]</span>
</code></pre></div></div>

<p>Because KDE is applied separately to standardized one-dimensional features, bandwidth effects should be examined alongside the feature distributions rather than inferred only from the final image.</p>

<h2 id="exploring-the-number-of-latent-factors">Exploring the number of latent factors</h2>

<p>The factor count controls compression and image size:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">factor_models</span> <span class="o">=</span> <span class="p">{</span>
    <span class="sa">f</span><span class="s">"factor_</span><span class="si">{</span><span class="n">n_factors</span><span class="si">}</span><span class="s">"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"factor"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="n">n_factors</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span>
    <span class="p">)</span>
    <span class="k">for</span> <span class="n">n_factors</span> <span class="ow">in</span> <span class="p">[</span><span class="mi">4</span><span class="p">,</span> <span class="mi">9</span><span class="p">,</span> <span class="mi">12</span><span class="p">]</span>
<span class="p">}</span>

<span class="k">for</span> <span class="n">name</span><span class="p">,</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">factor_models</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
    <span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>
    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
        <span class="n">test_df</span><span class="p">,</span>
        <span class="sa">f</span><span class="s">"synthetic_images/</span><span class="si">{</span><span class="n">name</span><span class="si">}</span><span class="s">/test"</span>
    <span class="p">)</span>
</code></pre></div></div>

<p>For Wine, 12 is the maximum allowed value in the current implementation because the dataset contains 13 input features.</p>

<h2 id="same-sample-different-pixel-semantics">Same sample, different pixel semantics</h2>

<p><img src="/images/Blog/2026-08-06-08-probability-density-factor-comparison.png" alt="Same sample represented with gaussianMix, KDE and Factor Analysis" />
<em>(Figure 5. Actual TINTOlib outputs generated from the same tabular sample using <code class="language-plaintext highlighter-rouge">gaussianMix</code>, <code class="language-plaintext highlighter-rouge">kde</code> and <code class="language-plaintext highlighter-rouge">factor</code>. The panels must preserve their native image dimensions and pixel values. Their visual patterns are not directly equivalent because they encode component responsibilities, feature-wise density estimates and latent-factor scores, respectively.)</em></p>
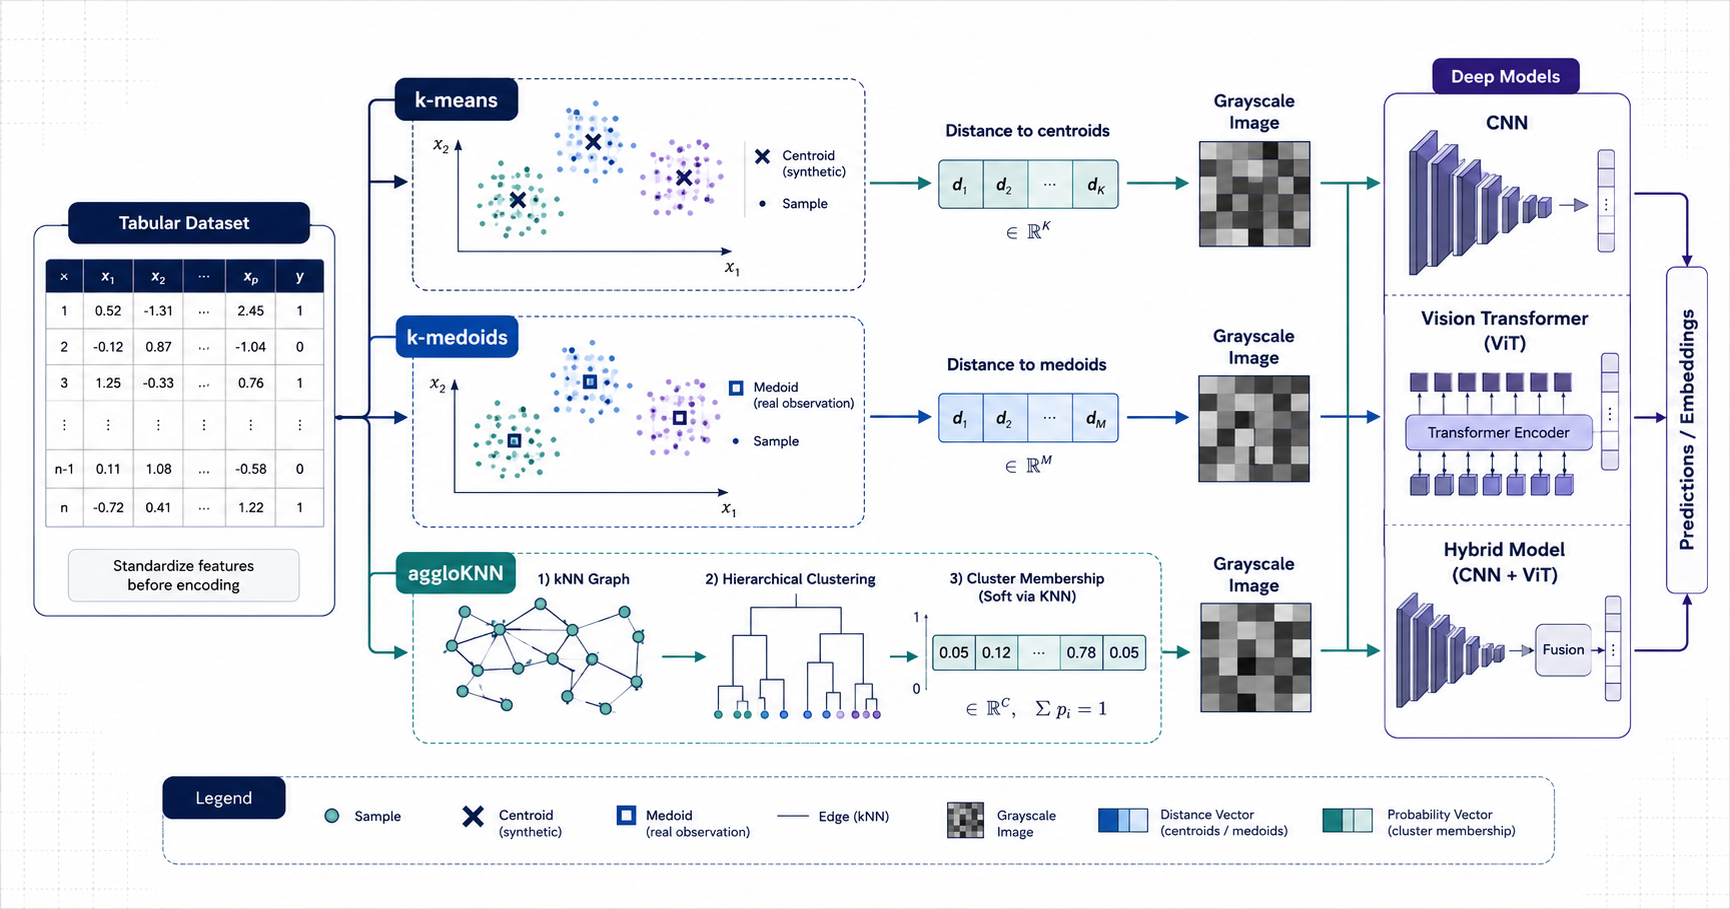
<p>A bright pixel has a method-dependent meaning:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Method</th>
      <th style="text-align: left">Meaning before MinMax scaling</th>
      <th style="text-align: left">Meaning after image scaling</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">gaussianMix</code></td>
      <td style="text-align: left">Large posterior responsibility for one component</td>
      <td style="text-align: left">High responsibility relative to the training range for that component</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kde</code></td>
      <td style="text-align: left">High estimated density for one feature value</td>
      <td style="text-align: left">High feature-wise density relative to the training scaling range</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">factor</code></td>
      <td style="text-align: left">High signed score on one latent factor</td>
      <td style="text-align: left">High factor score relative to the training range, without retaining an explicit zero reference</td>
    </tr>
  </tbody>
</table>

<p>The same grayscale value therefore cannot be interpreted identically across methods.</p>

<h2 id="sparse-discrete-and-low-contrast-images">Sparse, discrete and low-contrast images</h2>

<p>Synthetic images generated by these methods can appear visually unusual.</p>

<h3 id="gaussianmix"><code class="language-plaintext highlighter-rouge">gaussianMix</code></h3>

<p>A nearly one-hot responsibility vector produces a highly discrete image. This may be a faithful representation of confident component assignment rather than a defective image.</p>

<h3 id="kde"><code class="language-plaintext highlighter-rouge">kde</code></h3>

<p>If several values lie in similarly dense regions, the image may have low contrast. Conversely, rare feature values can create sharp dark or bright differences after scaling, depending on the training density range.</p>

<h3 id="factor"><code class="language-plaintext highlighter-rouge">factor</code></h3>

<p>A small number of factors produces very compact images and potentially substantial padding. Increasing the number of factors changes both representational capacity and spatial dimensions.</p>

<p>Visual texture alone is not a sufficient quality criterion. Evaluation should include the intermediate numerical representation, image stability, predictive performance and computational cost.</p>

<h2 id="methodological-checklist">Methodological checklist</h2>

<p>Before comparing the three methods, verify that:</p>

<ul>
  <li>the train/test split is created before fitting <code class="language-plaintext highlighter-rouge">Clusters</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">StandardScaler</code>, Gaussian components, KDE estimators, factor projections and MinMax scalers are learned only from training data;</li>
  <li>validation and test data are transformed without refitting;</li>
  <li>the same split and test sample are used in all visual comparisons;</li>
  <li>native image dimensions are reported;</li>
  <li>GMM covariance type, KDE kernel/bandwidth and factor count are documented;</li>
  <li>results are repeated across seeds when the method is stochastic;</li>
  <li>classical tabular baselines and an MLP remain part of the evaluation;</li>
  <li>CNN, ViT and hybrid models are compared under controlled settings;</li>
  <li>conclusions are conditional on the dataset and downstream architecture.</li>
</ul>

<h2 id="how-should-these-representations-be-evaluated">How should these representations be evaluated?</h2>

<p>The experimental study that motivated these additions used regression, binary-classification and multiclass-classification datasets together with a particular Vision Transformer evaluation pipeline. Those results provide evidence for that experimental setting, but they do not establish a universal ordering among <code class="language-plaintext highlighter-rouge">gaussianMix</code>, <code class="language-plaintext highlighter-rouge">kde</code>, <code class="language-plaintext highlighter-rouge">factor</code> or the other transformations.</p>

<p>A representation may behave differently with:</p>

<ul>
  <li>a convolutional neural network;</li>
  <li>a hybrid tabular–image architecture;</li>
  <li>another Vision Transformer configuration;</li>
  <li>a different image-resolution policy;</li>
  <li>another optimizer or regularization strategy;</li>
  <li>or a dataset with different dimensionality and distributional structure.</li>
</ul>

<p>A rigorous comparison should therefore report:</p>

<ol>
  <li>predictive metrics under identical data partitions;</li>
  <li>repeated runs and uncertainty estimates;</li>
  <li>transformation fit and generation time;</li>
  <li>memory and storage requirements;</li>
  <li>sensitivity to the main parameters;</li>
  <li>strong classical tabular and MLP baselines;</li>
  <li>results from more than one downstream visual architecture.</li>
</ol>

<p>The objective of this tutorial is to explain what each method encodes, not to declare a universally superior transformation.</p>

<h2 id="when-should-each-representation-be-considered">When should each representation be considered?</h2>

<p>These are practical starting points rather than performance guarantees:</p>

<ul>
  <li><strong><code class="language-plaintext highlighter-rouge">gaussianMix</code></strong> when soft membership, overlapping regions and component uncertainty are central to the analysis;</li>
  <li><strong><code class="language-plaintext highlighter-rouge">kde</code></strong> when feature-wise commonness, rarity or local distributional structure is relevant;</li>
  <li><strong><code class="language-plaintext highlighter-rouge">factor</code></strong> when a compact representation of shared covariance and latent structure is desired.</li>
</ul>

<p>The choice should be validated empirically under the intended model and dataset.</p>

<h2 id="conclusion">Conclusion</h2>

<p><code class="language-plaintext highlighter-rouge">gaussianMix</code>, <code class="language-plaintext highlighter-rouge">kde</code> and <code class="language-plaintext highlighter-rouge">factor</code> transform the same tabular sample into three fundamentally different descriptions.</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">gaussianMix</code> produces posterior responsibilities over probabilistic components.</li>
  <li><code class="language-plaintext highlighter-rouge">kde</code> evaluates every feature value under its training distribution.</li>
  <li><code class="language-plaintext highlighter-rouge">factor</code> projects the sample onto latent dimensions that summarize shared variation.</li>
</ul>

<p>TINTOlib converts all three representations into a common visual interface through training-based scaling, padding and square reshaping. That common output format should not obscure the fact that their pixels have different statistical meanings.</p>

<p>The final article in this series will examine <strong>RGB fusion through <code class="language-plaintext highlighter-rouge">mixMethod</code></strong>, channel composition, interpretability and automatic structural-stability analysis using <strong>SSIM</strong>.</p>

<hr />

<h2 id="references-and-resources">References and resources</h2>

<ol>
  <li>
    <p>Salvador Martínez Moreno. <strong>Generación de imágenes sintéticas mediante métodos no supervisados para la librería TINTOlib</strong>. Master’s Thesis, Universidad Nacional de Educación a Distancia (UNED), 2026.</p>
  </li>
  <li>
    <p>TINTOlib documentation. <strong>Clusters</strong>. <a href="https://tintolib.readthedocs.io/en/latest/clusters.html">Read the current parameter and API documentation</a>.</p>
  </li>
</ol>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-20-06-clusters-family-map.png" alt="Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-20T00:00:00+02:00">20 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Clusters" /><category term="Synthetic Images" /><category term="Tabular Data" /><category term="Unsupervised Learning" /><category term="Probabilistic Representations" /><category term="Gaussian Mixture Models" /><category term="gaussianMix" /><category term="Kernel Density Estimation" /><category term="KDE" /><category term="Factor Analysis" /><category term="Latent Factors" /><category term="Computer Vision" /><category term="Deep Learning" /><summary type="html"><![CDATA[Technical tutorial on the probabilistic, density-based and latent representations available in TINTOlib's Clusters class: Gaussian-mixture responsibilities, per-feature kernel densities and Factor Analysis scores.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-08-06-08-three-representation-families.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-08-06-08-three-representation-families.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</title><link href="https://www.manuelcastillo.eu/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/" rel="alternate" type="text/html" title="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" /><published>2026-07-24T00:00:00+02:00</published><updated>2026-07-24T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/07/07-distance-based-encodings-kmeans-kmedoids-aggloknn</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/"><![CDATA[<div style="background: linear-gradient(135deg, #0f172a 0%, #1e3a8a 42%, #0f766e 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #bfdbfe; font-weight: 600;">TINTOlib · Clusters · Distance-Based Encodings</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">k-Means, k-Medoids and aggloKNN</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #dbeafe; line-height: 1.55;">How centroids, representative observations and local connectivity define different intermediate representations before tabular data become synthetic images.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ecfeff;">k-means</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ecfeff;">k-medoids</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ecfeff;">aggloKNN</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ecfeff;">RBF</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 270px; width: 100%;">
    <img src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Distance-based synthetic image representations in TINTOlib using k-means, k-medoids and aggloKNN" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<h2 id="tutorial-metadata">Tutorial metadata</h2>

<ul>
  <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
  <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
  <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
  <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
</ul>

<hr />

<blockquote>
  <p><strong>Series note.</strong> This is the second article in a four-part series on the unsupervised representations available through the <code class="language-plaintext highlighter-rouge">Clusters</code> class in TINTOlib. <a href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Part I introduces the complete family of methods</a>. This post focuses on <code class="language-plaintext highlighter-rouge">kmeans</code>, <code class="language-plaintext highlighter-rouge">kmedoids</code> and <code class="language-plaintext highlighter-rouge">aggloKNN</code>, while Parts III and IV will examine probabilistic and latent representations, RGB fusion and SSIM-based stability.</p>
</blockquote>

<h2 id="video-overview">Video overview</h2>

<p>The following short video summarizes the main concepts introduced in this article.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-07-24-07-distance-based-encodings.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<h2 id="from-cluster-assignments-to-image-ready-representations">From cluster assignments to image-ready representations</h2>

<p>Clustering algorithms are usually introduced as methods that assign observations to groups. For synthetic image generation, however, a single discrete label contains too little information. If one sample is assigned to cluster 2 and another to cluster 3, the labels alone do not reveal whether the samples are almost identical or located in distant regions of the feature space.</p>

<p>The <code class="language-plaintext highlighter-rouge">Clusters</code> class therefore uses richer intermediate representations:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">kmeans</code> represents each sample through its distances to all learned centroids;</li>
  <li><code class="language-plaintext highlighter-rouge">kmedoids</code> uses distances to representative observations selected from the training data;</li>
  <li><code class="language-plaintext highlighter-rouge">aggloKNN</code> first constructs locally constrained hierarchical groups and then converts their pseudo-labels into KNN membership probabilities.</li>
</ul>

<p>The first two are direct distance encodings. The third is a bridge between distance-based grouping and probabilistic representation: distances define the local graph and the KNN model, while the image pixels contain probabilities rather than raw distances.</p>

<p>This common principle can be expressed as</p>

\[\mathbf{x}_i \in \mathbb{R}^{p}
\quad \longrightarrow \quad
\mathbf{r}_i \in \mathbb{R}^{k}
\quad \longrightarrow \quad
\mathbf{I}_i \in \mathbb{R}^{d \times d},\]

<p>where $p$ is the number of original variables, $k$ is the number of learned references or groups, and</p>

\[d = \left\lceil \sqrt{k} \right\rceil.\]

<p>The vector $\mathbf{r}_i$ is scaled to $[0,255]$, padded when necessary and reshaped into the grayscale image $\mathbf{I}_i$.</p>

<p><img src="/images/Blog/2026-07-24-07-distance-based-encodings.png" alt="Centroids, medoids and local hierarchical groups" />
<em>(Figure 1. Three mechanisms for constructing an intermediate representation from tabular samples. k-means uses synthetic centroids, k-medoids selects representative observations from the training data, and aggloKNN combines a local connectivity graph, hierarchical grouping and KNN membership probabilities.)</em></p>

<h2 id="1-k-means-distances-to-synthetic-centroids">1. k-Means: distances to synthetic centroids</h2>

<p>Let the standardized training set be</p>

\[X = \{\mathbf{x}_1,\ldots,\mathbf{x}_n\}
\subset \mathbb{R}^{p}.\]

<p>After fitting k-means with $k$ clusters, the method learns centroids</p>

\[\mathbf{c}_1,\ldots,\mathbf{c}_k \in \mathbb{R}^{p}.\]

<p>For a cluster $C_j$, its centroid is the arithmetic mean of the samples assigned to that group:</p>

\[\mathbf{c}_j =
\frac{1}{|C_j|}
\sum_{\mathbf{x}\in C_j}\mathbf{x}.\]

<p>TINTOlib does not use only the final cluster label. Instead, every sample is transformed into the complete distance profile</p>

\[\mathbf{r}^{(\mathrm{km})}_i =
\left(
d(\mathbf{x}_i,\mathbf{c}_1),
d(\mathbf{x}_i,\mathbf{c}_2),
\ldots,
d(\mathbf{x}_i,\mathbf{c}_k)
\right).\]

<p>This vector describes how the sample relates simultaneously to all regions represented by the centroids. Two samples assigned to different clusters can still have similar distance profiles, while two samples in the same cluster may relate differently to the remaining centroids.</p>

<h3 id="main-parameters">Main parameters</h3>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Parameter</th>
      <th style="text-align: left">Role</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code></td>
      <td style="text-align: left">Number of centroids and therefore initial representation dimensionality</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">random_seed</code></td>
      <td style="text-align: left">Reproducibility of initialization</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_init</code></td>
      <td style="text-align: left">Number of initial k-means solutions considered</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">max_iter</code></td>
      <td style="text-align: left">Maximum number of optimization iterations</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">algorithmMethod</code></td>
      <td style="text-align: left">Scikit-Learn optimization variant: <code class="language-plaintext highlighter-rouge">lloyd</code> or <code class="language-plaintext highlighter-rouge">elkan</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">RBFKmeans</code></td>
      <td style="text-align: left">Converts distances into Gaussian similarities before pixel scaling</td>
    </tr>
  </tbody>
</table>

<p>In the current implementation, k-means follows its standard Euclidean geometry. Unlike <code class="language-plaintext highlighter-rouge">kmedoids</code> and <code class="language-plaintext highlighter-rouge">aggloKNN</code>, it does not expose the general <code class="language-plaintext highlighter-rouge">metric</code> parameter.</p>

<h2 id="2-k-medoids-distances-to-real-observations">2. k-Medoids: distances to real observations</h2>

<p>k-medoids follows the same representational idea but changes the nature of the references. Instead of using arithmetic means, it selects actual observations from the training set:</p>

\[\mathbf{m}_1,\ldots,\mathbf{m}_k \in X.\]

<p>Within a cluster $C_j$, the medoid is the observation minimizing the total distance to the other elements in that group:</p>

\[\mathbf{m}_j =
\underset{\mathbf{x}\in C_j}{\operatorname{arg\,min}}
\sum_{\mathbf{x}'\in C_j}
d(\mathbf{x},\mathbf{x}').\]

<p>Every sample is then represented by</p>

\[\mathbf{r}^{(\mathrm{kmed})}_i =
\left(
d(\mathbf{x}_i,\mathbf{m}_1),
d(\mathbf{x}_i,\mathbf{m}_2),
\ldots,
d(\mathbf{x}_i,\mathbf{m}_k)
\right).\]

<p>Because each medoid is a real training observation, the references can be inspected directly. This can improve the semantic traceability of the representation and may reduce the influence of extreme values compared with mean-based centroids. The trade-off is that the PAM-like iterative search is generally more computationally demanding than k-means.</p>

<p>TINTOlib implements its own PAM-style procedure:</p>

<ol>
  <li>Select initial medoids from the training observations.</li>
  <li>Assign every sample to the nearest medoid.</li>
  <li>Within each group, identify the observation minimizing the total intra-cluster distance.</li>
  <li>Replace the medoid when a better representative is found.</li>
  <li>Repeat until the medoids remain unchanged or <code class="language-plaintext highlighter-rouge">max_iter</code> is reached.</li>
</ol>

<h3 id="supported-metrics">Supported metrics</h3>

<p>The current implementation accepts:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">euclidean</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">manhattan</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">chebyshev</code>.</li>
</ul>

<p>The metric affects both cluster construction and the distance profile later converted into the synthetic image.</p>

<p><img src="/images/Blog/2026-07-24-07-reference-ordering.png" alt="From learned references to ordered image pixels" />
<em>(Figure 2. Distance-vector construction and grayscale image generation for k-means and k-medoids. After learning the references, each sample is represented by its distances to all centroids or medoids. In single-channel mode, TINTOlib reorders these dimensions according to reference proximity before scaling, padding and reshaping the vector into an image.)</em></p>

<h2 id="reference-ordering-and-spatial-coherence">Reference ordering and spatial coherence</h2>

<p>A list of centroid or medoid distances has no natural two-dimensional order. If its components were reshaped directly, adjacent pixels could correspond to unrelated references.</p>

<p>In grayscale mode, TINTOlib therefore constructs a proximity-based ordering of the learned centroids or medoids before image generation. The procedure starts from a close pair of references and progressively builds a sequence that keeps nearby references close in the one-dimensional vector. The reordered vector is then reshaped into the square image.</p>

<p>This operation does not create a perfect two-dimensional embedding, but it reduces purely arbitrary adjacency and introduces a degree of spatial coherence into the image.</p>

<blockquote>
  <p><strong>Implementation note.</strong> This reference ordering is applied when <code class="language-plaintext highlighter-rouge">kmeans</code> or <code class="language-plaintext highlighter-rouge">kmedoids</code> is used as an individual grayscale method. It is not applied to those methods inside <code class="language-plaintext highlighter-rouge">mixMethod</code>, because independently reordering the channels could interfere with their alignment.</p>
</blockquote>

<h2 id="rbf-smoothing-distances-become-similarities">RBF smoothing: distances become similarities</h2>

<p>Raw distances and local similarities express opposite concepts:</p>

<ul>
  <li>a small distance indicates proximity;</li>
  <li>a large similarity indicates proximity.</li>
</ul>

<p>When <code class="language-plaintext highlighter-rouge">RBFKmeans=True</code>, TINTOlib transforms the k-means distances using a Gaussian radial basis function:</p>

\[s_{ij}
=
\exp\left(
-\frac{d(\mathbf{x}_i,\mathbf{c}_j)^2}{2\sigma^2}
\right).\]

<p>The implementation estimates $\sigma$ as the global mean of the distance matrix obtained during transformation. Nearby centroids therefore produce values close to one, while distant centroids are progressively attenuated.</p>

<p>The RBF operation changes the representation in three relevant ways:</p>

<ol>
  <li><strong>Direction of meaning:</strong> brighter or larger values can now indicate stronger local affinity rather than greater distance.</li>
  <li><strong>Non-linearity:</strong> differences among nearby references are emphasized differently from large-distance differences.</li>
  <li><strong>Visual continuity:</strong> the resulting image may show smoother transitions after scaling to pixel intensities.</li>
</ol>

<p>RBF should not be treated as universally beneficial. It introduces a different inductive assumption and must be assessed as an experimental choice.</p>

<p><img src="/images/Blog/2026-07-24-07-kmeans-distance-vs-rbf.png" alt="k-means distances compared with RBF similarities" />
<em>(Figure 3. The same tabular sample represented with k-means before and after Gaussian RBF transformation. The distance image encodes proximity inversely, whereas the RBF image converts distances into bounded similarities that emphasize nearby centroids and attenuate distant references.)</em></p>

<h2 id="3-aggloknn-local-connectivity-followed-by-soft-membership">3. aggloKNN: local connectivity followed by soft membership</h2>

<p><code class="language-plaintext highlighter-rouge">aggloKNN</code> requires a more precise interpretation. It does not generate pixels directly from the hierarchical-clustering labels. Instead, it combines two stages.</p>

<h3 id="stage-1-locally-constrained-agglomerative-clustering">Stage 1: locally constrained agglomerative clustering</h3>

<p>The standardized data are first normalized with the L2 norm. A nearest-neighbour connectivity graph is then constructed. In the current implementation, the number of graph neighbours is</p>

\[n_{\mathrm{conn}}
=
\max\left(
1,
\min(10,n-1)
\right).\]

<p>The graph restricts which observations or groups may be merged during agglomerative clustering. This changes the focus from unrestricted global comparisons to locally admissible connections.</p>

<p>TINTOlib uses complete linkage, where the distance between two groups is determined by the most distant pair of observations across them. The resulting partition provides one pseudo-label for every training sample.</p>

<h3 id="stage-2-knn-probabilities">Stage 2: KNN probabilities</h3>

<p>The hierarchical model itself does not naturally provide a <code class="language-plaintext highlighter-rouge">predict_proba</code> operation for new observations. TINTOlib therefore trains a KNN classifier using the agglomerative labels as pseudo-labels.</p>

<p>The number of neighbours used by this classifier is</p>

\[n_{\mathrm{KNN}}
=
\max\left(
1,
\min(3k,n-1)
\right).\]

<p>The KNN classifier uses:</p>

<ul>
  <li>uniform neighbour weights;</li>
  <li>the same selected distance metric;</li>
  <li>brute-force neighbour search.</li>
</ul>

<p>For each sample, it produces a probability vector</p>

\[\mathbf{r}^{(\mathrm{agg})}_i =
\left(
P(z=1\mid \mathbf{x}_i),
\ldots,
P(z=k\mid \mathbf{x}_i)
\right).\]

<p>Consequently, the final pixels encode soft membership estimates derived from a locally constrained hierarchical partition. This can represent ambiguity near group boundaries more effectively than a single hard cluster label.</p>

<p><img src="/images/Blog/2026-07-24-07-aggloknn-pipeline.png" alt="Two-stage aggloKNN representation pipeline" />
<em>(Figure 4. aggloKNN pipeline. Standardized samples are L2-normalized, connected through a nearest-neighbour graph and grouped with complete-linkage agglomerative clustering. The resulting pseudo-labels train a KNN classifier, whose membership probabilities form the intermediate vector converted into a grayscale synthetic image.)</em></p>

<h3 id="supported-metrics-and-current-restriction">Supported metrics and current restriction</h3>

<p><code class="language-plaintext highlighter-rouge">aggloKNN</code> accepts:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">euclidean</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">manhattan</code>;</li>
  <li><code class="language-plaintext highlighter-rouge">cosine</code>.</li>
</ul>

<p>The selected metric is used in the connectivity graph, the agglomerative model and the subsequent KNN classifier.</p>

<p>Unlike <code class="language-plaintext highlighter-rouge">kmeans</code> and <code class="language-plaintext highlighter-rouge">kmedoids</code>, the current implementation requires an explicit integer for <code class="language-plaintext highlighter-rouge">n_clusters</code>. Automatic selection through <code class="language-plaintext highlighter-rouge">"auto"</code> or a list of candidates is not currently enabled for <code class="language-plaintext highlighter-rouge">aggloKNN</code>.</p>

<h2 id="comparative-view">Comparative view</h2>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Property</th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">kmeans</code></th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">kmedoids</code></th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">aggloKNN</code></th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>Learned references</strong></td>
      <td style="text-align: left">Synthetic centroids</td>
      <td style="text-align: left">Real training observations</td>
      <td style="text-align: left">Locally constrained hierarchical groups</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Intermediate vector</strong></td>
      <td style="text-align: left">Distances to centroids</td>
      <td style="text-align: left">Distances to medoids</td>
      <td style="text-align: left">KNN membership probabilities</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Output interpretation</strong></td>
      <td style="text-align: left">Proximity to mean-based regions</td>
      <td style="text-align: left">Proximity to representative samples</td>
      <td style="text-align: left">Soft affinity to pseudo-labelled groups</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Metric control</strong></td>
      <td style="text-align: left">Standard k-means geometry</td>
      <td style="text-align: left">Euclidean, Manhattan or Chebyshev</td>
      <td style="text-align: left">Euclidean, Manhattan or cosine</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Optional non-linearity</strong></td>
      <td style="text-align: left">Gaussian RBF</td>
      <td style="text-align: left">Not currently available</td>
      <td style="text-align: left">Not currently available</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Reference ordering in grayscale</strong></td>
      <td style="text-align: left">Yes</td>
      <td style="text-align: left">Yes</td>
      <td style="text-align: left">No</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Automatic <code class="language-plaintext highlighter-rouge">n_clusters</code> selection</strong></td>
      <td style="text-align: left">Supported</td>
      <td style="text-align: left">Supported</td>
      <td style="text-align: left">Not currently supported</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Main computational concern</strong></td>
      <td style="text-align: left">Repeated centroid optimization</td>
      <td style="text-align: left">PAM-style medoid search and pairwise distances</td>
      <td style="text-align: left">Connectivity graph, hierarchy and KNN probability model</td>
    </tr>
  </tbody>
</table>

<p>The table should not be interpreted as a ranking. Each method exposes a different relationship between the original sample and the learned structure of the training set.</p>

<h2 id="practical-implementation-with-a-leakage-free-split">Practical implementation with a leakage-free split</h2>

<p>The following example generates four representations from the Wine dataset:</p>

<ul>
  <li>k-means distances;</li>
  <li>k-means RBF similarities;</li>
  <li>k-medoids with Euclidean distance;</li>
  <li>aggloKNN with cosine distance.</li>
</ul>

<p>The original dataset is split before fitting any transformation.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">pathlib</span> <span class="kn">import</span> <span class="n">Path</span>

<span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_wine</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>

<span class="kn">from</span> <span class="nn">TINTOlib.clusters</span> <span class="kn">import</span> <span class="n">Clusters</span>

<span class="c1"># ---------------------------------------------------------
# 1. Load a reproducible tabular dataset
# ---------------------------------------------------------
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_wine</span><span class="p">()</span>

<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span>
    <span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span>
    <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span>
<span class="p">)</span>

<span class="c1"># The target column must be the final column.
</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span>

<span class="c1"># ---------------------------------------------------------
# 2. Split before fitting the image transformation
# ---------------------------------------------------------
</span><span class="n">train_df</span><span class="p">,</span> <span class="n">test_df</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">df</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.20</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="mi">42</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 3. Define comparable configurations
#    25 references/components -&gt; 5 x 5 images
# ---------------------------------------------------------
</span><span class="n">models</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"kmeans_distances"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
        <span class="n">n_init</span><span class="o">=</span><span class="s">"auto"</span><span class="p">,</span>
        <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
        <span class="n">algorithmMethod</span><span class="o">=</span><span class="s">"lloyd"</span><span class="p">,</span>
        <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">False</span>
    <span class="p">),</span>

    <span class="s">"kmeans_rbf"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
        <span class="n">n_init</span><span class="o">=</span><span class="s">"auto"</span><span class="p">,</span>
        <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
        <span class="n">algorithmMethod</span><span class="o">=</span><span class="s">"lloyd"</span><span class="p">,</span>
        <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
    <span class="p">),</span>

    <span class="s">"kmedoids_euclidean"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmedoids"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
        <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"euclidean"</span>
    <span class="p">),</span>

    <span class="s">"aggloknn_cosine"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"aggloKNN"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"cosine"</span>
    <span class="p">)</span>
<span class="p">}</span>

<span class="c1"># ---------------------------------------------------------
# 4. Fit only on training data and reuse every fitted model
# ---------------------------------------------------------
</span><span class="k">for</span> <span class="n">name</span><span class="p">,</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">models</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
    <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Generating images with </span><span class="si">{</span><span class="n">name</span><span class="si">}</span><span class="s">..."</span><span class="p">)</span>

    <span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

    <span class="n">train_folder</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images"</span><span class="p">)</span> <span class="o">/</span> <span class="n">name</span> <span class="o">/</span> <span class="s">"train"</span>
    <span class="n">test_folder</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images"</span><span class="p">)</span> <span class="o">/</span> <span class="n">name</span> <span class="o">/</span> <span class="s">"test"</span>

    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">train_df</span><span class="p">,</span> <span class="nb">str</span><span class="p">(</span><span class="n">train_folder</span><span class="p">))</span>
    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">test_df</span><span class="p">,</span> <span class="nb">str</span><span class="p">(</span><span class="n">test_folder</span><span class="p">))</span>

<span class="k">print</span><span class="p">(</span><span class="s">"Distance-based synthetic images generated successfully."</span><span class="p">)</span>
</code></pre></div></div>

<p>With <code class="language-plaintext highlighter-rouge">n_clusters=25</code>, each intermediate representation contains 25 values and can therefore be reshaped directly into a $5\times5$ image without zero-padding.</p>

<h2 id="comparing-distance-metrics">Comparing distance metrics</h2>

<p>The <code class="language-plaintext highlighter-rouge">metric</code> parameter should be treated as part of the representation design, not merely as an implementation detail.</p>

<h3 id="k-medoids">k-medoids</h3>

<ul>
  <li><strong>Euclidean:</strong> emphasizes straight-line geometric distance.</li>
  <li><strong>Manhattan:</strong> accumulates absolute coordinate differences and may be appropriate in high-dimensional spaces where axis-wise changes are meaningful.</li>
  <li><strong>Chebyshev:</strong> uses the maximum coordinate difference and is therefore controlled by the most discrepant feature.</li>
</ul>

<h3 id="aggloknn">aggloKNN</h3>

<ul>
  <li><strong>Euclidean:</strong> geometric neighbourhoods under L2 distance.</li>
  <li><strong>Manhattan:</strong> neighbourhoods based on cumulative absolute differences.</li>
  <li><strong>Cosine:</strong> neighbourhoods based primarily on vector orientation after L2 normalization.</li>
</ul>

<p>Changing the metric may alter:</p>

<ol>
  <li>the selected medoids;</li>
  <li>the local connectivity graph;</li>
  <li>the agglomerative pseudo-labels;</li>
  <li>the KNN neighbourhoods;</li>
  <li>the final pixel intensities.</li>
</ol>

<p>A valid metric comparison must therefore refit the transformation independently for every metric while preserving the same train/test partitions.</p>

<h2 id="what-should-the-experiment-compare">What should the experiment compare?</h2>

<p>The purpose of this post is to explain the representations rather than identify a universally superior method. A rigorous experiment should separate at least four dimensions.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Evaluation dimension</th>
      <th style="text-align: left">Questions</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>Representation</strong></td>
      <td style="text-align: left">How sparse, contrasted or stable are the generated images? How does RBF alter local structure?</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Prediction</strong></td>
      <td style="text-align: left">How do the images behave with the same CNN, ViT or hybrid architecture and identical data splits?</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Robustness</strong></td>
      <td style="text-align: left">Are conclusions stable across seeds, image resolutions and values of <code class="language-plaintext highlighter-rouge">n_clusters</code>?</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Efficiency</strong></td>
      <td style="text-align: left">What are the fit time, transform time, memory consumption and generated storage cost?</td>
    </tr>
  </tbody>
</table>

<p>The Master’s Thesis used a specific Vision Transformer evaluation architecture. Its results provide evidence for that experimental setting, but they should not be extrapolated directly to CNNs, hybrid tabular–image models or alternative ViT configurations. For that reason, this series does not establish a general ranking among methods.</p>

<p><img src="/images/Blog/2026-07-24-07-distance-method-comparison.png" alt="Same sample represented by the three distance-oriented strategies" />
<em>(Figure 5. Synthetic images generated from the same tabular sample using k-means distances, k-means with RBF similarities, k-medoids and aggloKNN. The panels use a common image size, but their pixel semantics differ: centroid distance, centroid similarity, medoid distance and soft membership probability.)</em></p>

<h2 id="methodological-checklist">Methodological checklist</h2>

<p>Before comparing these transformations, verify that:</p>

<ul>
  <li>the original split is created before fitting <code class="language-plaintext highlighter-rouge">Clusters</code>;</li>
  <li>standardization and all representation models are learned only from training data;</li>
  <li>the same split is reused across methods and metrics;</li>
  <li>image dimensions are controlled through a comparable <code class="language-plaintext highlighter-rouge">n_clusters</code> value;</li>
  <li>architecture and optimization settings are held constant within each downstream comparison;</li>
  <li>results are repeated across several seeds;</li>
  <li>classical tabular baselines and an MLP remain part of the evaluation;</li>
  <li>conclusions are reported conditionally on the dataset and downstream architecture.</li>
</ul>

<h2 id="when-should-each-representation-be-considered">When should each representation be considered?</h2>

<p>A reasonable initial interpretation is:</p>

<ul>
  <li><strong>k-means distances</strong> when a computationally efficient reference map based on synthetic centroids is required;</li>
  <li><strong>k-means with RBF</strong> when the experiment aims to emphasize local centroid similarity rather than raw distance;</li>
  <li><strong>k-medoids</strong> when references tied to real training observations and alternative metrics are relevant;</li>
  <li><strong>aggloKNN</strong> when local connectivity, hierarchical grouping and soft membership probabilities are central to the representation.</li>
</ul>

<p>These are methodological starting points, not performance guarantees.</p>

<h2 id="conclusion">Conclusion</h2>

<p>k-means, k-medoids and aggloKNN begin with a related idea: a tabular sample can be described through its relationship with structures learned from the training set. The nature of that relationship is nevertheless different.</p>

<p>k-means uses distances to synthetic centroids. k-medoids uses distances to representative observations. aggloKNN uses local geometry to construct hierarchical pseudo-labels and then converts those labels into soft KNN probabilities.</p>

<p>These distinctions determine what every pixel means, how the representation responds to distance metrics, whether RBF smoothing is available and how the final image should be interpreted. The correct choice therefore depends on the dataset, the downstream architecture and the experimental objective.</p>

<p>The next post in this series will move from distance-oriented representations to <strong>Gaussian Mixtures, Kernel Density Estimation and Factor Analysis</strong>, examining probabilities, densities and latent factors as alternative sources of image pixels.</p>

<hr />

<h2 id="references-and-resources">References and resources</h2>

<ol>
  <li>
    <p>Salvador Martínez Moreno. <strong>Generación de imágenes sintéticas mediante métodos no supervisados para la librería TINTOlib</strong>. Master’s Thesis, Universidad Nacional de Educación a Distancia (UNED), 2026.</p>
  </li>
  <li>
    <p>TINTOlib documentation. <strong>Clusters</strong>. <a href="https://tintolib.readthedocs.io/en/latest/clusters.html">Read the current parameter and API documentation</a>.</p>
  </li>
</ol>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-20-06-clusters-family-map.png" alt="Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-20T00:00:00+02:00">20 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Clusters" /><category term="Synthetic Images" /><category term="Tabular Data" /><category term="Unsupervised Learning" /><category term="Distance-Based Encodings" /><category term="K-Means" /><category term="K-Medoids" /><category term="aggloKNN" /><category term="RBF" /><category term="Computer Vision" /><category term="Deep Learning" /><summary type="html"><![CDATA[Technical comparison of the distance-based representations available in TINTOlib's Clusters class: k-means centroid distances, k-medoids prototype distances, and aggloKNN local-connectivity probabilities.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib</title><link href="https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/" rel="alternate" type="text/html" title="Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib" /><published>2026-07-20T00:00:00+02:00</published><updated>2026-07-20T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/07/06-clusters-to-pixels-unsupervised-synthetic-images</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/"><![CDATA[<link rel="canonical" href="https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/" />

<meta name="robots" content="index,follow,max-image-preview:large" />

<meta name="description" content="Technical introduction to the new Clusters method in TINTOlib, which transforms tabular data into grayscale or RGB synthetic images using distance-based, probabilistic, density-based and latent unsupervised representations." />

<meta property="og:type" content="article" />

<meta property="og:title" content="Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib" />

<meta property="og:description" content="Technical introduction to the new Clusters method in TINTOlib, which transforms tabular data into grayscale or RGB synthetic images using distance-based, probabilistic, density-based and latent unsupervised representations." />

<meta property="og:url" content="https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/" />

<meta property="og:image" content="https://www.manuelcastillo.eu/images/Blog/2026-07-20-06-clusters-family-map.png" />

<meta property="article:published_time" content="2026-07-20T00:00:00+02:00" />

<meta property="article:modified_time" content="2026-07-20T00:00:00+02:00" />

<meta property="article:author" content="Manuel Castillo-Cara" />

<meta property="article:section" content="TINTOlib" />

<meta property="article:tag" content="TINTOlib" />

<meta property="article:tag" content="Clusters" />

<meta property="article:tag" content="Synthetic Images" />

<meta property="article:tag" content="Tabular Data" />

<meta property="article:tag" content="Unsupervised Learning" />

<meta property="article:tag" content="Clustering" />

<meta property="article:tag" content="K-Means" />

<meta property="article:tag" content="K-Medoids" />

<meta property="article:tag" content="Gaussian Mixture Models" />

<meta property="article:tag" content="Kernel Density Estimation" />

<meta property="article:tag" content="Factor Analysis" />

<meta property="article:tag" content="Deep Learning" />

<meta name="twitter:card" content="summary_large_image" />

<meta name="twitter:title" content="Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib" />

<meta name="twitter:description" content="Technical introduction to the new Clusters method in TINTOlib, which transforms tabular data into grayscale or RGB synthetic images using distance-based, probabilistic, density-based and latent unsupervised representations." />

<meta name="twitter:image" content="https://www.manuelcastillo.eu/images/Blog/2026-07-20-06-clusters-family-map.png" />

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "Part 1 - From Clusters to Pixels: Unsupervised Synthetic Image Generation in TINTOlib",
  "description": "Technical introduction to the new Clusters method in TINTOlib, which transforms tabular data into grayscale or RGB synthetic images using distance-based, probabilistic, density-based and latent unsupervised representations.",
  "image": "https://www.manuelcastillo.eu/images/Blog/2026-07-20-06-clusters-family-map.png",
  "author": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "publisher": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "datePublished": "2026-07-20T00:00:00+02:00",
  "dateModified": "2026-07-20T00:00:00+02:00",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://www.manuelcastillo.eu/blog/2026/07/20-clusters-to-pixels-unsupervised-synthetic-images/"
  },
  "articleSection": "TINTOlib",
  "keywords": "TINTOlib, Clusters, Synthetic Images, Tabular Data, Unsupervised Learning, Clustering, K-Means, K-Medoids, Gaussian Mixture Models, Kernel Density Estimation, Factor Analysis, Deep Learning"
}
</script>

<div style="background: linear-gradient(135deg, #0f172a 0%, #312e81 48%, #0f766e 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #c4b5fd; font-weight: 600;">TINTOlib · Unsupervised Learning · Synthetic Images</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">From Clusters to Pixels</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #e0e7ff; line-height: 1.55;">How distances, membership probabilities, density estimates and latent factors can be converted into synthetic images for vision-based deep learning.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f0fdfa;">Clusters</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f0fdfa;">K-Means</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f0fdfa;">K-Medoids</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #f0fdfa;">RGB Fusion</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 270px; width: 100%;">
    <img src="/images/Blog/2026-07-20-06-clusters-family-map.png" alt="Unsupervised tabular representations transformed into synthetic images with TINTOlib" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<h2 id="tutorial-metadata">Tutorial metadata</h2>

<ul>
  <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
  <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
  <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
  <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
</ul>

<hr />

<blockquote>
  <p><strong>Series note.</strong> This is the first article in a four-part series on the new unsupervised representation methods available through the <code class="language-plaintext highlighter-rouge">Clusters</code> class in TINTOlib. The series covers distance-based encodings, probabilistic and latent representations, RGB fusion through <code class="language-plaintext highlighter-rouge">mixMethod</code>, and automatic cluster-number selection using SSIM.</p>
</blockquote>

<h2 id="video-overview">Video overview</h2>

<p>The following short video summarizes the main concepts introduced in this article.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-07-20-06-clusters-to-pixels.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<h2 id="a-new-representation-family-in-tintolib">A new representation family in TINTOlib</h2>

<p>Most tabular-to-image methods begin by asking where the original variables should be placed in a two-dimensional canvas. Methods such as TINTO, REFINED and IGTD construct a spatial organization of features and then project the value of each sample onto that layout.</p>

<p>The new <strong><code class="language-plaintext highlighter-rouge">Clusters</code></strong> method introduces a complementary perspective. Instead of directly assigning the original variables to image coordinates, it first learns an <strong>intermediate unsupervised representation</strong> of every sample. This representation may contain:</p>

<ul>
  <li>distances to learned centroids;</li>
  <li>distances to representative medoids;</li>
  <li>probabilities of belonging to latent groups;</li>
  <li>estimated probability densities;</li>
  <li>latent factor scores;</li>
  <li>or several of these representations combined across RGB channels.</li>
</ul>

<p>The resulting numerical vector is subsequently scaled, padded when necessary and reshaped into a square image. Therefore, the image does not directly encode the original columns. It encodes how a sample relates to a set of learned references, distributions or latent structures.</p>

<p>This distinction is important. The method is called <code class="language-plaintext highlighter-rouge">Clusters</code>, but not all its internal algorithms are conventional clustering procedures. The class also includes density estimation and latent-factor transformations because all of them can produce structured intermediate representations suitable for image generation.</p>

<!-- FIGURE 1: conceptual pipeline -->
<p><img src="/images/Blog/2026-07-20-06-clusters-pipeline.png" alt="From tabular samples to unsupervised synthetic images" />
<em>(Figure 1. General workflow of the TINTOlib <code class="language-plaintext highlighter-rouge">Clusters</code> method. The original tabular data are standardized, transformed into an unsupervised intermediate representation based on distances, probabilities, densities or latent factors, scaled to pixel intensities and reshaped into grayscale or multi-channel synthetic images.)</em></p>
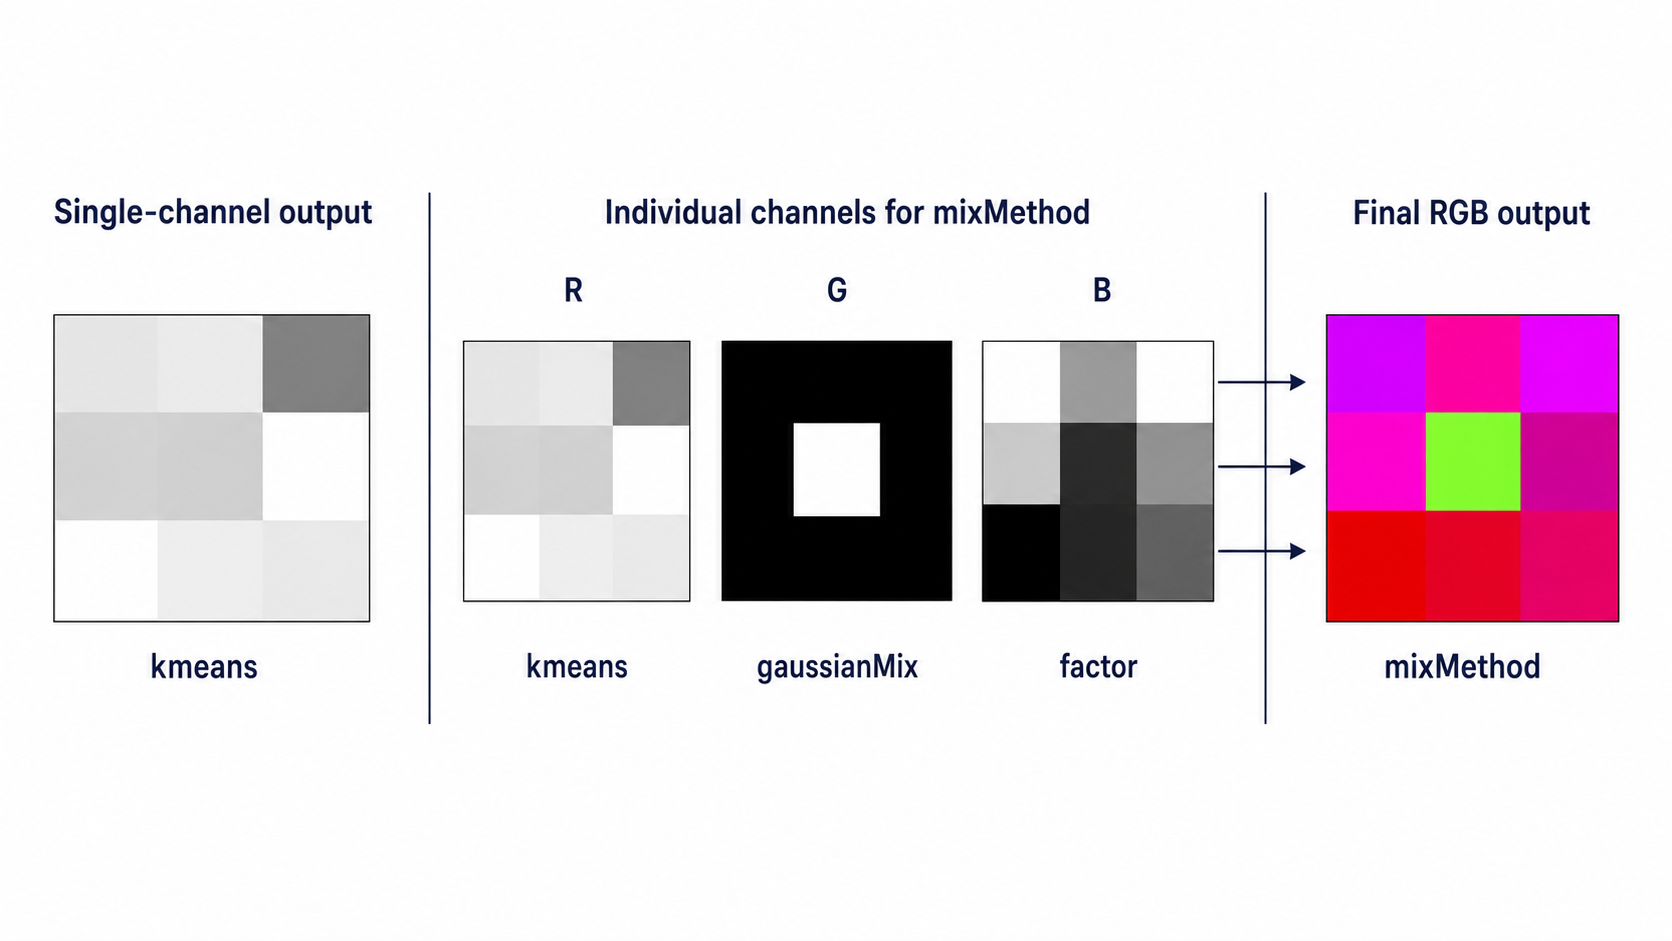
<h2 id="the-central-idea-learn-a-representation-before-building-the-image">The central idea: learn a representation before building the image</h2>

<p>Let an original tabular sample be represented by</p>

\[\mathbf{x}_i \in \mathbb{R}^{p},\]

<p>where $p$ is the number of original variables. The selected unsupervised model learns a transformation</p>

\[\phi: \mathbb{R}^{p} \rightarrow \mathbb{R}^{q},\]

<p>and produces an intermediate vector</p>

\[\mathbf{r}_i = \phi(\mathbf{x}_i).\]

<p>The meaning of $q$ depends on the selected algorithm. For example, it may be the number of centroids, medoids, Gaussian components or latent factors. In KDE, the dimensionality is tied to the original features because one density estimator is fitted per variable.</p>

<p>The representation $\mathbf{r}_i$ is then transformed into an image through the following operations:</p>

<ol>
  <li>
    <p>Scale the representation to the range $[0,255]$.</p>
  </li>
  <li>
    <p>Compute the smallest square side capable of containing all values:</p>

\[d = \left\lceil \sqrt{q} \right\rceil.\]
  </li>
  <li>
    <p>Add zero-padding when $d^2 &gt; q$.</p>
  </li>
  <li>
    <p>Reshape the vector into a $d \times d$ matrix.</p>
  </li>
  <li>
    <p>Convert the matrix to an unsigned 8-bit image.</p>
  </li>
  <li>
    <p>In <code class="language-plaintext highlighter-rouge">mixMethod</code>, repeat the process independently for each selected method and stack the results into the RGB channels.</p>
  </li>
</ol>

<p>This design creates a common visual interface for heterogeneous unsupervised models.</p>

<h2 id="seven-algorithms-four-representation-families">Seven algorithms, four representation families</h2>

<p>The current implementation supports seven strategies. They can be organized into four conceptual families.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Family</th>
      <th style="text-align: left">TINTOlib algorithm</th>
      <th style="text-align: left">Intermediate representation</th>
      <th style="text-align: left">Image type</th>
      <th style="text-align: left">Main parameters</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>Distance-based</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmeans</code></td>
      <td style="text-align: left">Distance from each sample to every centroid</td>
      <td style="text-align: left">Grayscale</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">n_init</code>, <code class="language-plaintext highlighter-rouge">max_iter</code>, <code class="language-plaintext highlighter-rouge">algorithmMethod</code>, <code class="language-plaintext highlighter-rouge">RBFKmeans</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Distance-based</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmedoids</code></td>
      <td style="text-align: left">Distance from each sample to every medoid</td>
      <td style="text-align: left">Grayscale</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">metric</code>, <code class="language-plaintext highlighter-rouge">max_iter</code>, <code class="language-plaintext highlighter-rouge">random_seed</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Local probabilistic clustering</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">aggloKNN</code></td>
      <td style="text-align: left">KNN probabilities derived from agglomerative-clustering pseudo-labels</td>
      <td style="text-align: left">Grayscale</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">metric</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Probabilistic mixture</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">gaussianMix</code></td>
      <td style="text-align: left">Posterior probability of every Gaussian component</td>
      <td style="text-align: left">Grayscale</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">covariance_type</code>, <code class="language-plaintext highlighter-rouge">n_init</code>, <code class="language-plaintext highlighter-rouge">max_iter</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Density-based</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kde</code></td>
      <td style="text-align: left">Estimated density of every feature value</td>
      <td style="text-align: left">Grayscale</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kernel</code>, <code class="language-plaintext highlighter-rouge">bandwidth</code>, <code class="language-plaintext highlighter-rouge">metric</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Latent structure</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">factor</code></td>
      <td style="text-align: left">Factor-analysis scores</td>
      <td style="text-align: left">Grayscale</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code>, <code class="language-plaintext highlighter-rouge">random_seed</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Hybrid multi-view</strong></td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">mixMethod</code></td>
      <td style="text-align: left">Up to three representations assigned to R, G and B</td>
      <td style="text-align: left">RGB</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">ensamMethod</code> and the parameters required by its component methods</td>
    </tr>
  </tbody>
</table>

<!-- FIGURE 2: method family map -->
<p><img src="/images/Blog/2026-07-20-06-clusters-family-map.png" alt="Families of unsupervised representations in the TINTOlib Clusters method" />
<em>(Figure 2. Conceptual organization of the seven strategies supported by the <code class="language-plaintext highlighter-rouge">Clusters</code> class. Distance-based, probabilistic, density-based and latent representations provide different views of the internal structure of tabular data, while <code class="language-plaintext highlighter-rouge">mixMethod</code> integrates complementary views into a single RGB image.)</em></p>

<h3 id="distance-based-representations">Distance-based representations</h3>

<p>The <code class="language-plaintext highlighter-rouge">kmeans</code> and <code class="language-plaintext highlighter-rouge">kmedoids</code> variants describe a sample through its distance to a set of learned references. In <code class="language-plaintext highlighter-rouge">kmeans</code>, those references are synthetic centroids. In <code class="language-plaintext highlighter-rouge">kmedoids</code>, they are real observations selected from the training data.</p>

<p>A distance vector carries more information than a hard cluster label. Two samples assigned to different groups can still have similar distance profiles, and two samples assigned to the same group may relate differently to the remaining clusters.</p>

<p>In grayscale mode, TINTOlib reorders the centroid- or medoid-based dimensions according to reference proximity before reshaping them. The goal is to place related reference regions close to each other in the generated image.</p>

<h3 id="probabilistic-representations">Probabilistic representations</h3>

<p>The <code class="language-plaintext highlighter-rouge">gaussianMix</code> method replaces distances with posterior membership probabilities. Each pixel indicates the degree to which a sample belongs to one Gaussian component.</p>

<p>The <code class="language-plaintext highlighter-rouge">aggloKNN</code> method follows a two-stage procedure. It first applies agglomerative clustering constrained by a nearest-neighbour connectivity graph. The resulting cluster assignments are then treated as pseudo-labels for a KNN classifier, whose probability output becomes the intermediate representation.</p>

<p>Probabilities provide a softer description than hard labels and can capture uncertainty near cluster boundaries.</p>

<h3 id="density-and-latent-representations">Density and latent representations</h3>

<p>The <code class="language-plaintext highlighter-rouge">kde</code> method fits a one-dimensional kernel-density estimator to every feature. Each original value is replaced by its estimated density under the training distribution. The resulting image therefore encodes how common or unusual the values of a sample are, rather than their raw magnitudes.</p>

<p>The <code class="language-plaintext highlighter-rouge">factor</code> method projects the original data into a lower-dimensional latent space using Factor Analysis. Its pixels correspond to factor scores that summarize shared variation among the original variables.</p>

<h3 id="multi-channel-representations">Multi-channel representations</h3>

<p>The <code class="language-plaintext highlighter-rouge">mixMethod</code> strategy combines between one and three non-repeated methods in an RGB image. Each method fills one colour channel. If fewer than three representations are selected, the remaining channels are filled with zeros.</p>

<p>For example:</p>

<ul>
  <li>red channel: distances to k-means centroids;</li>
  <li>green channel: Gaussian-mixture membership probabilities;</li>
  <li>blue channel: latent factor scores.</li>
</ul>

<p>This produces a multi-view image in which colour reflects the interaction among different unsupervised descriptions of the same sample.</p>

<!-- FIGURE 3: actual output, preferable to AI generation -->
<p><img src="/images/Blog/2026-07-20-06-clusters-grayscale-vs-rgb.png" alt="Grayscale and RGB synthetic images generated with the Clusters method" />
<em>(Figure 3. Comparison between single-channel and multi-channel image generation. Individual methods produce grayscale images, whereas <code class="language-plaintext highlighter-rouge">mixMethod</code> assigns complementary unsupervised representations to the red, green and blue channels of one synthetic image.)</em></p>
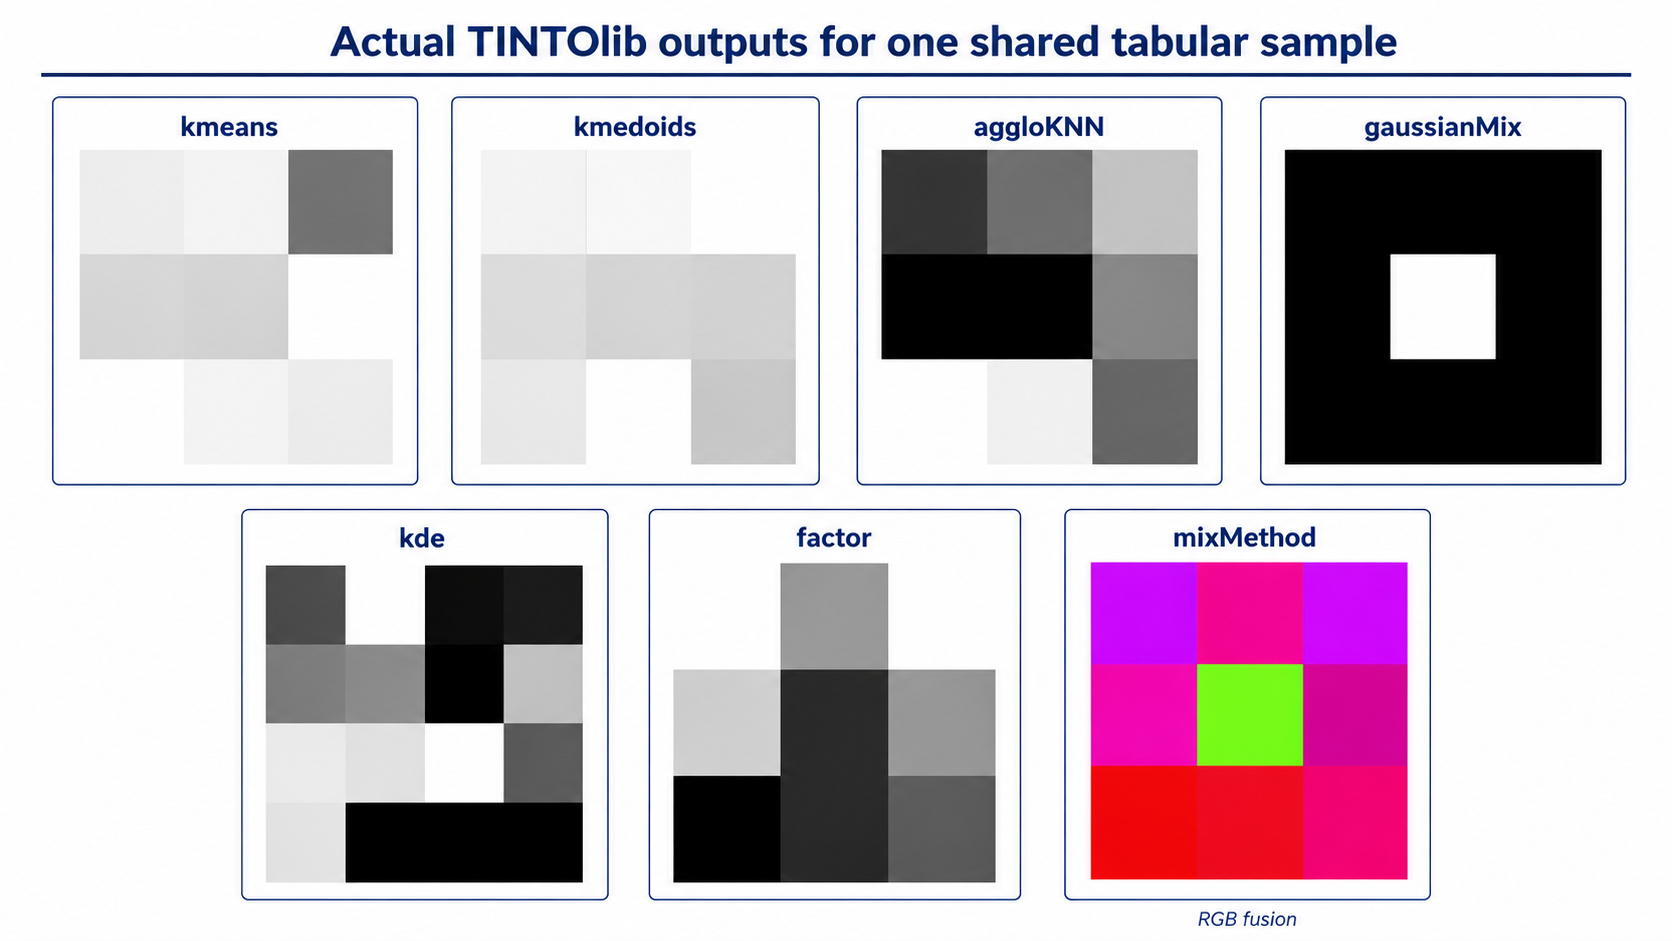
<h2 id="why-this-is-different-from-direct-feature-to-pixel-mapping">Why this is different from direct feature-to-pixel mapping</h2>

<p>The distinction between spatial feature mapping and cluster-based representation can be summarized as follows.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Question</th>
      <th style="text-align: left">Feature-layout methods</th>
      <th style="text-align: left"><code class="language-plaintext highlighter-rouge">Clusters</code> methods</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>What is positioned in the image?</strong></td>
      <td style="text-align: left">Original variables</td>
      <td style="text-align: left">Learned distances, probabilities, densities or factors</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>What is learned from the training data?</strong></td>
      <td style="text-align: left">A feature layout or coordinate map</td>
      <td style="text-align: left">An unsupervised representation model</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>What does a pixel mean?</strong></td>
      <td style="text-align: left">Value of an original feature at a selected location</td>
      <td style="text-align: left">Relationship between a sample and a learned reference or latent property</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Typical image dimensionality</strong></td>
      <td style="text-align: left">Determined by the number of original features or a chosen canvas</td>
      <td style="text-align: left">Determined by clusters/components, except KDE</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Multi-channel option</strong></td>
      <td style="text-align: left">Method-dependent</td>
      <td style="text-align: left">Native support through <code class="language-plaintext highlighter-rouge">mixMethod</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Main scientific question</strong></td>
      <td style="text-align: left">How should related variables be placed?</td>
      <td style="text-align: left">Which unsupervised description best characterizes each sample?</td>
    </tr>
  </tbody>
</table>

<p>Neither paradigm is universally preferable. They encode different inductive assumptions and should be compared under the same leakage-free experimental protocol.</p>

<h2 id="first-practical-example-k-means-with-rbf-smoothing">First practical example: k-means with RBF smoothing</h2>

<p>The following example uses the Wine dataset from Scikit-Learn. We first divide the data into training and test partitions. The <code class="language-plaintext highlighter-rouge">Clusters</code> transformation is then fitted <strong>only on the training partition</strong>, and the learned model is reused to transform both sets.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">pathlib</span> <span class="kn">import</span> <span class="n">Path</span>

<span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_wine</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>

<span class="kn">from</span> <span class="nn">TINTOlib.clusters</span> <span class="kn">import</span> <span class="n">Clusters</span>

<span class="c1"># ---------------------------------------------------------
# 1. Load the tabular dataset
# ---------------------------------------------------------
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_wine</span><span class="p">()</span>

<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span>
    <span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span>
    <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span>
<span class="p">)</span>

<span class="c1"># The target column must be the final column.
</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span>

<span class="c1"># ---------------------------------------------------------
# 2. Split before fitting the transformation
# ---------------------------------------------------------
</span><span class="n">train_df</span><span class="p">,</span> <span class="n">test_df</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">df</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.20</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="mi">42</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 3. Configure the cluster-based image transformation
# ---------------------------------------------------------
</span><span class="n">model</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">n_init</span><span class="o">=</span><span class="s">"auto"</span><span class="p">,</span>
    <span class="n">max_iter</span><span class="o">=</span><span class="mi">300</span><span class="p">,</span>
    <span class="n">algorithmMethod</span><span class="o">=</span><span class="s">"lloyd"</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 4. Learn the representation from training data only
# ---------------------------------------------------------
</span><span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 5. Generate training and test images consistently
# ---------------------------------------------------------
</span><span class="n">train_output</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images/clusters_kmeans/train"</span><span class="p">)</span>
<span class="n">test_output</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"synthetic_images/clusters_kmeans/test"</span><span class="p">)</span>

<span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">train_df</span><span class="p">,</span> <span class="nb">str</span><span class="p">(</span><span class="n">train_output</span><span class="p">))</span>
<span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">test_df</span><span class="p">,</span> <span class="nb">str</span><span class="p">(</span><span class="n">test_output</span><span class="p">))</span>

<span class="k">print</span><span class="p">(</span><span class="s">"Cluster-based synthetic images generated successfully."</span><span class="p">)</span>
</code></pre></div></div>

<p>With <code class="language-plaintext highlighter-rouge">n_clusters=25</code>, every sample is initially represented by 25 distances to the learned centroids. These values fit naturally into a (5 \times 5) image. When <code class="language-plaintext highlighter-rouge">RBFKmeans=True</code>, the distance representation is converted into Gaussian radial similarities before pixel scaling, emphasizing nearby centroids and attenuating distant ones.</p>

<p>A useful comparison is to generate the same sample both with and without RBF:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">plain_kmeans</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">False</span>
<span class="p">)</span>

<span class="n">rbf_kmeans</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
<span class="p">)</span>
</code></pre></div></div>

<p>The first image encodes distances directly; the second emphasizes local similarities.</p>

<!-- FIGURE 4: generate with the library, not with generative AI -->
<p><img src="/images/Blog/2026-07-20-06-same-sample-cluster-methods.png" alt="The same sample represented by the seven Clusters algorithms" />
<em>(Figure 4. Representative synthetic images generated from the same tabular sample using <code class="language-plaintext highlighter-rouge">kmeans</code>, <code class="language-plaintext highlighter-rouge">kmedoids</code>, <code class="language-plaintext highlighter-rouge">aggloKNN</code>, <code class="language-plaintext highlighter-rouge">gaussianMix</code>, <code class="language-plaintext highlighter-rouge">kde</code>, <code class="language-plaintext highlighter-rouge">factor</code> and <code class="language-plaintext highlighter-rouge">mixMethod</code>. The visual differences arise because each algorithm encodes a different intermediate property of the sample: proximity, membership probability, statistical density, latent structure or multi-view fusion.)</em></p>
<h2 id="switching-between-algorithms">Switching between algorithms</h2>

<p>TINTOlib uses one class and a common <code class="language-plaintext highlighter-rouge">fit</code>/<code class="language-plaintext highlighter-rouge">transform</code> workflow. The main change is the algorithm-specific configuration.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">models</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"kmeans"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
    <span class="p">),</span>

    <span class="s">"kmedoids"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmedoids"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"euclidean"</span>
    <span class="p">),</span>

    <span class="s">"gaussianMix"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"gaussianMix"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">covariance_type</span><span class="o">=</span><span class="s">"full"</span>
    <span class="p">),</span>

    <span class="s">"aggloKNN"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"aggloKNN"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"cosine"</span>
    <span class="p">),</span>

    <span class="s">"kde"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"kde"</span><span class="p">,</span>
        <span class="n">kernel</span><span class="o">=</span><span class="s">"gaussian"</span><span class="p">,</span>
        <span class="n">bandwidth</span><span class="o">=</span><span class="mf">1.0</span><span class="p">,</span>
        <span class="n">metric</span><span class="o">=</span><span class="s">"euclidean"</span>
    <span class="p">),</span>

    <span class="s">"factor"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"factor"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">9</span><span class="p">,</span>
        <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span>
    <span class="p">),</span>

    <span class="s">"mixMethod"</span><span class="p">:</span> <span class="n">Clusters</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"mixMethod"</span><span class="p">,</span>
        <span class="n">n_clusters</span><span class="o">=</span><span class="mi">25</span><span class="p">,</span>
        <span class="n">ensamMethod</span><span class="o">=</span><span class="p">[</span><span class="s">"kmeans"</span><span class="p">,</span> <span class="s">"gaussianMix"</span><span class="p">,</span> <span class="s">"factor"</span><span class="p">],</span>
        <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span><span class="p">,</span>
        <span class="n">covariance_type</span><span class="o">=</span><span class="s">"full"</span>
    <span class="p">)</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Not every parameter applies to every algorithm. The constructor validates incompatible combinations so that configuration errors are detected early.</p>

<h2 id="parameter-compatibility-at-a-glance">Parameter compatibility at a glance</h2>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Parameter</th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">kmeans</code></th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">kmedoids</code></th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">aggloKNN</code></th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">gaussianMix</code></th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">kde</code></th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">factor</code></th>
      <th style="text-align: center"><code class="language-plaintext highlighter-rouge">mixMethod</code></th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_clusters="auto"</code> or list</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">random_seed</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">Depends on components</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">n_init</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">Depends on components</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">max_iter</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">Depends on components</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">algorithmMethod</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">When using <code class="language-plaintext highlighter-rouge">kmeans</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">RBFKmeans</code></td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">When using <code class="language-plaintext highlighter-rouge">kmeans</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">covariance_type</code></td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">When using <code class="language-plaintext highlighter-rouge">gaussianMix</code></td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">metric</code></td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">When using applicable components</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kernel</code> / <code class="language-plaintext highlighter-rouge">bandwidth</code></td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
    </tr>
    <tr>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">ensamMethod</code></td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">✓</td>
    </tr>
  </tbody>
</table>

<blockquote>
  <p><strong>Current implementation note.</strong> Automatic cluster-number selection is not available for <code class="language-plaintext highlighter-rouge">kde</code> or <code class="language-plaintext highlighter-rouge">aggloKNN</code>. KDE does not use <code class="language-plaintext highlighter-rouge">n_clusters</code>, and <code class="language-plaintext highlighter-rouge">aggloKNN</code> currently requires an explicit integer value.</p>
</blockquote>

<h2 id="automatic-cluster-number-selection-with-ssim">Automatic cluster-number selection with SSIM</h2>

<p>For compatible algorithms, <code class="language-plaintext highlighter-rouge">n_clusters</code> may be:</p>

<ul>
  <li>a fixed integer;</li>
  <li>the string <code class="language-plaintext highlighter-rouge">"auto"</code>;</li>
  <li>or a list of candidate integers.</li>
</ul>

<p>When automatic selection is requested, TINTOlib generates representations under several random initializations and evaluates their structural stability using the <strong>Structural Similarity Index Measure (SSIM)</strong>. The selected number of clusters is the one that produces the most stable synthetic images across runs.</p>

<p>For example:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">model</span> <span class="o">=</span> <span class="n">Clusters</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"classification"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"kmeans"</span><span class="p">,</span>
    <span class="n">n_clusters</span><span class="o">=</span><span class="p">[</span><span class="mi">9</span><span class="p">,</span> <span class="mi">16</span><span class="p">,</span> <span class="mi">25</span><span class="p">,</span> <span class="mi">36</span><span class="p">,</span> <span class="mi">49</span><span class="p">],</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span>
    <span class="n">RBFKmeans</span><span class="o">=</span><span class="bp">True</span>
<span class="p">)</span>
</code></pre></div></div>

<p>This is not simply a search for the clustering solution with the lowest internal objective. It evaluates the model from the perspective of the final artifact: the structural consistency of the generated images.</p>

<p>The complete SSIM procedure will be examined in the fourth post of this series.</p>

<h2 id="methodological-note-prevent-data-leakage">Methodological note: prevent data leakage</h2>

<p>The cluster model, scaling objects, density estimators and latent projections must be learned exclusively from the training partition.</p>

<p>The correct sequence is:</p>

<ol>
  <li>Split the original tabular data.</li>
  <li>Fit <code class="language-plaintext highlighter-rouge">Clusters</code> on the training set.</li>
  <li>Generate training images using the fitted transformation.</li>
  <li>Transform validation and test samples with exactly the same learned objects.</li>
  <li>Train the visual model only on the training images.</li>
  <li>Report performance on untouched validation or test images.</li>
</ol>

<p>Using <code class="language-plaintext highlighter-rouge">fit_transform</code> on the complete dataset before splitting would expose the transformation to the evaluation samples. That can leak information through centroids, medoids, density estimates, Gaussian components, latent factors or scaling ranges.</p>

<!-- FIGURE 5: leakage-free workflow -->
<p><img src="/images/Blog/2026-07-20-06-clusters-leakage-free-workflow.png" alt="Leakage-free workflow for cluster-based synthetic image generation" />
<em>(Figure 5. Leakage-free experimental workflow. The unsupervised representation and its associated scaling operations are fitted only on the training partition and then reused without refitting to generate validation and test images.)</em></p>

<h2 id="which-representation-should-i-try-first">Which representation should I try first?</h2>

<p>The following table provides an initial decision guide. It should be treated as a practical starting point, not as a universal ranking.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Experimental priority</th>
      <th style="text-align: left">Suggested starting method</th>
      <th style="text-align: left">Rationale</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">Fast and interpretable distance representation</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmeans</code></td>
      <td style="text-align: left">Efficient centroid-based encoding with optional RBF smoothing</td>
    </tr>
    <tr>
      <td style="text-align: left">Robust prototypes tied to real observations</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kmedoids</code></td>
      <td style="text-align: left">Uses actual training samples as cluster representatives</td>
    </tr>
    <tr>
      <td style="text-align: left">Local hierarchical structure and soft assignments</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">aggloKNN</code></td>
      <td style="text-align: left">Combines constrained agglomerative grouping with KNN probabilities</td>
    </tr>
    <tr>
      <td style="text-align: left">Probabilistic cluster membership</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">gaussianMix</code></td>
      <td style="text-align: left">Encodes posterior responsibilities and assignment uncertainty</td>
    </tr>
    <tr>
      <td style="text-align: left">Detect common versus unusual feature values</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">kde</code></td>
      <td style="text-align: left">Converts values into distribution-based density scores</td>
    </tr>
    <tr>
      <td style="text-align: left">Compact latent representation</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">factor</code></td>
      <td style="text-align: left">Encodes shared variability through latent factors</td>
    </tr>
    <tr>
      <td style="text-align: left">Combine complementary descriptions</td>
      <td style="text-align: left"><code class="language-plaintext highlighter-rouge">mixMethod</code></td>
      <td style="text-align: left">Places up to three representations in RGB channels</td>
    </tr>
  </tbody>
</table>

<p>The transformation should always be assessed together with:</p>

<ul>
  <li>strong tabular baselines such as XGBoost, LightGBM, CatBoost and Random Forest;</li>
  <li>an MLP trained on the original features;</li>
  <li>several image-based architectures;</li>
  <li>repeated runs and uncertainty estimates;</li>
  <li>computational cost;</li>
  <li>and ablation studies over the main transformation parameters.</li>
</ul>

<h2 id="how-should-these-methods-be-evaluated">How should these methods be evaluated?</h2>

<p>The experimental study that motivated these additions evaluated the proposed transformations on regression, binary-classification and multiclass-classification datasets using a specific Vision Transformer architecture. These experiments provide an initial validation of the feasibility of converting unsupervised representations into synthetic images, but they should not be interpreted as a definitive ranking among transformation methods.</p>

<p>A transformation that behaves well with a particular Vision Transformer configuration may exhibit a different behaviour when combined with:</p>

<ul>
  <li>convolutional neural networks;</li>
  <li>hybrid tabular–image architectures;</li>
  <li>alternative Vision Transformer designs;</li>
  <li>different image resolutions;</li>
  <li>other optimization strategies;</li>
  <li>or datasets with different dimensionality, sample size and feature distributions.</li>
</ul>

<p>For this reason, the purpose of this series is to present the assumptions, representations, parameters and practical implementation of each method rather than to identify a universally superior alternative.</p>

<p>A rigorous comparison should evaluate every transformation under comparable conditions, include several downstream architectures, report repeated runs and uncertainty estimates, and retain strong classical tabular baselines. The relevant question is therefore not <em>which method is always best</em>, but <em>which representation is most appropriate for a specific dataset, neural architecture and experimental objective</em>.</p>

<h2 id="roadmap-for-this-four-part-series">Roadmap for this four-part series</h2>

<h3 id="part-i--from-clusters-to-pixels">Part I — From Clusters to Pixels</h3>

<ul>
  <li>Unified conceptual framework.</li>
  <li>Seven supported algorithms.</li>
  <li>Grayscale and RGB image generation.</li>
  <li>First implementation with k-means.</li>
  <li>Leakage-free experimental design.</li>
</ul>

<h3 id="part-ii--distance-based-encodings">Part II — Distance-Based Encodings</h3>

<ul>
  <li><code class="language-plaintext highlighter-rouge">kmeans</code>, <code class="language-plaintext highlighter-rouge">kmedoids</code> and <code class="language-plaintext highlighter-rouge">aggloKNN</code>.</li>
  <li>Centroids versus medoids.</li>
  <li>Distance metrics and local connectivity.</li>
  <li>RBF smoothing.</li>
  <li>Side-by-side image and performance comparisons.</li>
</ul>

<h3 id="part-iii--probabilities-densities-and-latent-factors">Part III — Probabilities, Densities and Latent Factors</h3>

<ul>
  <li><code class="language-plaintext highlighter-rouge">gaussianMix</code>, <code class="language-plaintext highlighter-rouge">kde</code> and <code class="language-plaintext highlighter-rouge">factor</code>.</li>
  <li>Membership probabilities and covariance structures.</li>
  <li>KDE kernels and bandwidth.</li>
  <li>Factor scores and latent representations.</li>
  <li>When probabilistic encodings become sparse or highly discrete.</li>
</ul>

<h3 id="part-iv--rgb-fusion-and-structural-stability">Part IV — RGB Fusion and Structural Stability</h3>

<ul>
  <li><code class="language-plaintext highlighter-rouge">mixMethod</code> and multi-channel images.</li>
  <li>Channel selection and interpretability.</li>
  <li>Automatic <code class="language-plaintext highlighter-rouge">n_clusters</code> selection.</li>
  <li>SSIM stability.</li>
  <li>Experimental conclusions, limitations and future directions.</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p>The new <code class="language-plaintext highlighter-rouge">Clusters</code> method expands TINTOlib beyond direct feature-layout strategies. Its main contribution is a unified mechanism for turning heterogeneous unsupervised representations into synthetic images.</p>

<p>Distances, membership probabilities, density estimates and latent factors emphasize different aspects of the same tabular sample. Once converted into pixels, these representations can be processed by CNNs, Vision Transformers or hybrid neural networks. However, the transformation itself becomes part of the learning pipeline and must therefore be selected, fitted and evaluated with the same methodological rigor as the downstream predictive model.</p>

<p>The most relevant question is not whether clustering can produce an image. It is whether a particular unsupervised representation preserves information that a visual architecture can exploit more effectively, robustly or interpretably than alternative tabular representations.</p>

<hr />

<h2 id="references-and-resources">References and resources</h2>

<ol>
  <li>
    <p>Salvador Martínez Moreno. <strong>Generación de imágenes sintéticas mediante métodos no supervisados para la librería TINTOlib</strong>. Master’s Thesis, Universidad Nacional de Educación a Distancia (UNED), 2026.</p>
  </li>
  <li>
    <p>TINTOlib documentation. <strong>Clusters</strong>. <a href="https://tintolib.readthedocs.io/en/latest/clusters.html">Read the current parameter and API documentation</a>.</p>
  </li>
</ol>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Clusters" /><category term="Synthetic Images" /><category term="Tabular Data" /><category term="Unsupervised Learning" /><category term="Clustering" /><category term="K-Means" /><category term="K-Medoids" /><category term="Gaussian Mixture Models" /><category term="Kernel Density Estimation" /><category term="Factor Analysis" /><category term="Deep Learning" /><summary type="html"><![CDATA[Technical introduction to the new Clusters method in TINTOlib, which transforms tabular data into grayscale or RGB synthetic images using distance-based, probabilistic, density-based and latent unsupervised representations.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-07-20-06-clusters-family-map.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-07-20-06-clusters-family-map.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">TINTO vs REFINED vs IGTD: Comparing Tabular-to-Image Methods in TINTOlib</title><link href="https://www.manuelcastillo.eu/blog/2026/06/27-tinto-vs-refined-vs-igtd-comparison/" rel="alternate" type="text/html" title="TINTO vs REFINED vs IGTD: Comparing Tabular-to-Image Methods in TINTOlib" /><published>2026-06-27T00:00:00+02:00</published><updated>2026-06-27T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/06/05-TINTO_REFINED_IGTD</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/06/27-tinto-vs-refined-vs-igtd-comparison/"><![CDATA[<link rel="canonical" href="https://www.manuelcastillo.eu/blog/2026/06/27-tinto-vs-refined-vs-igtd-comparison/" />

<meta name="robots" content="index,follow,max-image-preview:large" />

<meta name="description" content="Comparative analysis of TINTO, REFINED and IGTD, three representative tabular data into synthetic image transformation methods available in TINTOlib for generating synthetic images from tabular data." />

<meta property="og:type" content="article" />

<meta property="og:title" content="TINTO vs REFINED vs IGTD: Comparing Tabular-to-Image Methods in TINTOlib" />

<meta property="og:description" content="Comparative analysis of TINTO, REFINED and IGTD, three representative tabular data into synthetic image transformation methods available in TINTOlib for generating synthetic images from tabular data." />

<meta property="og:url" content="https://www.manuelcastillo.eu/blog/2026/06/27-tinto-vs-refined-vs-igtd-comparison/" />

<meta property="og:image" content="https://www.manuelcastillo.eu/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png" />

<meta property="article:published_time" content="2026-06-27T00:00:00+02:00" />

<meta property="article:modified_time" content="2026-06-27T00:00:00+02:00" />

<meta property="article:author" content="Manuel Castillo-Cara" />

<meta property="article:section" content="TINTOlib" />

<meta property="article:tag" content="TINTOlib" />

<meta property="article:tag" content="Synthetic Images" />

<meta property="article:tag" content="Tabular Data" />

<meta property="article:tag" content="Deep Learning" />

<meta property="article:tag" content="Computer Vision" />

<meta property="article:tag" content="Spatial Encoding" />

<meta property="article:tag" content="IGTD" />

<meta property="article:tag" content="REFINED" />

<meta property="article:tag" content="TINTO" />

<meta name="twitter:card" content="summary_large_image" />

<meta name="twitter:title" content="TINTO vs REFINED vs IGTD: Comparing Tabular-to-Image Methods in TINTOlib" />

<meta name="twitter:description" content="Comparative analysis of TINTO, REFINED and IGTD, three representative tabular data into synthetic image transformation methods available in TINTOlib for generating synthetic images from tabular data." />

<meta name="twitter:image" content="https://www.manuelcastillo.eu/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png" />

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "TINTO vs REFINED vs IGTD: Comparing Tabular-to-Image Methods in TINTOlib",
  "description": "Comparative analysis of TINTO, REFINED and IGTD, three representative tabular data into synthetic image transformation methods available in TINTOlib for generating synthetic images from tabular data.",
  "image": "https://www.manuelcastillo.eu/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png",
  "author": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "publisher": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "datePublished": "2026-06-27T00:00:00+02:00",
  "dateModified": "2026-06-27T00:00:00+02:00",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://www.manuelcastillo.eu/blog/2026/06/27-tinto-vs-refined-vs-igtd-comparison/"
  },
  "articleSection": "TINTOlib",
  "keywords": "TINTOlib, Synthetic Images, Tabular Data, Deep Learning, Computer Vision, Spatial Encoding, IGTD, REFINED, TINTO"
}
</script>

<div style="background: linear-gradient(135deg, #0f172a 0%, #1e3a8a 45%, #14532d 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #bfdbfe; font-weight: 600;">TINTOlib · Synthetic Images · Tabular Data</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">TINTO vs REFINED vs IGTD</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #dbeafe; line-height: 1.55;">A methodological comparison of three representative tabular data into synthetic image methods for generating synthetic images from tabular data.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">TINTO</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">REFINED</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">IGTD</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">TINTOlib</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 260px; width: 100%;">
    <img src="/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png" alt="Comparison of TINTO, REFINED and IGTD for tabular data into synthetic image transformation" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<h2 id="tutorial-metadata">Tutorial metadata</h2>

<ul>
  <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
  <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
  <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
  <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
</ul>

<hr />

<h2 id="video-overview">Video overview</h2>

<p>This post provides a comprehensive methodological comparison derived from our ongoing research on spatial encoding strategies within the <strong>TINTOlib</strong> ecosystem.</p>

<p>The following short video provides an English overview of the core architectural paradigms compared across this tutorial: how different parametric mapping techniques—namely <strong>TINTO</strong>, <strong>REFINED</strong>, and <strong>IGTD</strong>—construct entirely distinct spatial layouts from the same underlying tabular dataset, and how these unique image topologies influence downstream deep learning pipelines, hybrid neural networks, and visual explainability (XAI) frameworks.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-06-27-05-TINTO_REFINED_IGTD.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<blockquote>
  <p><strong>Additional material.</strong> The original technical workflow and benchmark code are fully documented in our open-source repositories. This blog post provides the corresponding English technical synthesis, pipeline formalization, and a decision map to help you select the optimal transformation method for your tabular data.</p>
</blockquote>

<h2 id="the-challenge-of-organizing-tabular-space">The challenge of organizing tabular space</h2>

<p>As discussed in previous posts, applying computer vision architectures —such as Convolutional Neural Networks (CNNs) or Vision Transformers (ViTs)— to classical tabular datasets is not straightforward. The main reason is methodological: <strong>tabular data do not have an intrinsic spatial structure</strong>.</p>

<p>In natural images, neighbouring pixels usually encode meaningful local relationships: edges, textures, shapes or spatial continuity. In tabular data, however, the order of the columns is often arbitrary. If we simply reshape a row of numerical values into a square matrix, we are imposing a spatial topology that may not correspond to any real relationship among the original variables.</p>

<p>This is precisely the problem addressed by <strong>tabular data into synthetic image transformation methods</strong>. These algorithms aim to arrange tabular features on a two-dimensional grid so that spatial proximity reflects some form of statistical, geometric or relational similarity among variables.</p>

<p><img src="/images/Blog/2026-06-27-05-tabular-space-problem.png" alt="Why tabular data needs spatial encoding" />
<em>(Figure 1. Conceptual illustration of the core problem in tabular data into synthetic image transformation. A raw tabular vector has no intrinsic spatial neighbourhood, so directly reshaping it into a matrix may impose arbitrary local relationships. Spatial encoding methods aim to construct a more meaningful two-dimensional layout before applying vision-based models.)</em></p>

<p>In this post, we compare three representative methods implemented in <strong>TINTOlib</strong>:</p>

<ul>
  <li><strong>TINTO</strong>, based on dimensionality reduction and optional blurring.</li>
  <li><strong>REFINED</strong>, based on distance-preserving geometric optimization.</li>
  <li><strong>IGTD</strong>, based on preserving the ranking of feature relationships in a dense image layout.</li>
</ul>

<p>The objective is not to claim that one method is universally superior, but to understand their different assumptions, strengths, computational costs and practical use cases.</p>

<p><img src="/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png" alt="Same tabular sample transformed with TINTO, REFINED and IGTD" />
<em>(Figure 2. Synthetic image representations generated from the same tabular sample using TINTO, REFINED and IGTD. Although all three methods pursue the same objective —constructing a spatial representation from tabular features— they produce different image topologies due to their distinct optimization criteria and spatial encoding assumptions.)</em></p>

<hr />

<h2 id="1-tinto-dimensionality-reduction-and-blurring">1. TINTO: dimensionality reduction and blurring</h2>

<p><strong>TINTO</strong> addresses the tabular data into synthetic image problem by projecting the features of the dataset into a two-dimensional space using dimensionality-reduction techniques such as <strong>PCA</strong> or <strong>t-SNE</strong>. Once the features have been located in a continuous coordinate space, their positions are mapped to a discrete image grid.</p>

<h3 id="how-it-works">How it works</h3>

<p>The general workflow followed by TINTO can be summarized as follows:</p>

<ol>
  <li>A feature-level representation is constructed from the original tabular dataset.</li>
  <li>Dimensionality reduction is applied to obtain two-dimensional coordinates for the features.</li>
  <li>These coordinates are scaled and mapped onto an image grid of size (N \times N).</li>
  <li>Each tabular sample is converted into an image by placing the feature values in their corresponding spatial positions.</li>
  <li>Optional <strong>blurring</strong> is applied to diffuse feature intensities across neighbouring pixels.</li>
</ol>

<p>The blurring step is particularly relevant. When two or more features are projected into nearby or overlapping coordinates, direct pixel assignment can produce sparse or unstable representations. Blurring spreads the feature intensity over local neighbourhoods, creating smoother synthetic images and making local patterns more accessible to convolutional filters.</p>

<p><img src="/images/Blog/2026-06-27-05-tinto-pipeline.png" alt="TINTO transformation pipeline" />
<em>(Figure 3. TINTO transformation pipeline. Features are projected into a two-dimensional space using PCA or t-SNE, mapped onto a discrete image grid, and optionally smoothed through blurring to generate synthetic images with local spatial continuity.)</em></p>

<h3 id="strengths-and-limitations">Strengths and limitations</h3>

<p>TINTO is especially useful when the objective is to generate visually interpretable synthetic images and to experiment rapidly with different spatial configurations. It is flexible, relatively efficient, and well suited for hybrid neural architectures that combine the original tabular vector with the generated synthetic image.</p>

<p>However, the final representation depends on the selected dimensionality-reduction algorithm, the image size, the blurring configuration and the characteristics of the dataset. As with any tabular data into synthetic image method, these hyperparameters should be evaluated under a rigorous validation protocol.</p>

<hr />

<h2 id="2-refined-geometric-mapping-and-neighbourhood-dependencies">2. REFINED: geometric mapping and neighbourhood dependencies</h2>

<p><strong>REFINED</strong> stands for <em>REpresentation of Features as Images with NEighborhood Dependencies</em>. It was originally proposed as a way to represent high-dimensional tabular data as images by preserving feature relationships in a spatial layout.</p>

<p>Unlike direct reshaping approaches, REFINED tries to construct a meaningful feature map where spatial proximity reflects similarity or dependency among variables. It has been especially influential in biomedical, chemical and omics-related datasets, where high-dimensional feature spaces are common.</p>

<h3 id="how-it-works-1">How it works</h3>

<p>A simplified REFINED workflow can be described as follows:</p>

<ol>
  <li>A dissimilarity or distance matrix is computed among features.</li>
  <li>A dimensionality-reduction or multidimensional-scaling step is used to generate an initial two-dimensional feature map.</li>
  <li>An iterative optimization process adjusts the location of features on the grid.</li>
  <li>The objective is to preserve the original feature relationships as faithfully as possible in the image space.</li>
  <li>Each sample is converted into an image by filling the feature positions with the corresponding sample values.</li>
</ol>

<p>The optimization process used by REFINED is more computationally demanding than a simple projection, but it can produce layouts that better preserve both local and global relationships among variables.</p>

<p><img src="/images/Blog/2026-06-27-05-refined-pipeline.png" alt="REFINED transformation pipeline" />
<em>(Figure 4. REFINED transformation pipeline. Feature relationships are first represented through a distance or dissimilarity matrix. A two-dimensional map is then optimized so that neighbouring pixels encode variables with strong statistical or geometric relationships.)</em></p>

<h3 id="strengths-and-limitations-1">Strengths and limitations</h3>

<p>REFINED is particularly attractive when the preservation of distance relationships among features is important. It can be useful in domains where variables have complex dependency structures and where a carefully optimized spatial map may improve the behaviour of convolutional architectures.</p>

<p>Its main limitation is computational cost. For datasets with thousands of features, the optimization process can become expensive. In addition, the quality of the resulting representation depends on the distance metric, the optimization strategy and the resolution of the image grid.</p>

<hr />

<h2 id="3-igtd-image-generator-for-tabular-data">3. IGTD: Image Generator for Tabular Data</h2>

<p><strong>IGTD</strong> (<em>Image Generator for Tabular Data</em>) follows a different strategy. Instead of relying mainly on dimensionality reduction or geometric projection, IGTD aims to preserve the <strong>ranking of feature relationships</strong> when assigning features to image pixels.</p>

<p>The central idea is that if two features are highly similar in the original tabular space, they should be placed close to each other in the image grid. Conversely, features that are less related should be placed farther apart.</p>

<h3 id="how-it-works-2">How it works</h3>

<p>The IGTD workflow can be summarized as follows:</p>

<ol>
  <li>A feature-similarity or feature-distance matrix is computed from the tabular dataset.</li>
  <li>A target image grid is defined.</li>
  <li>Each feature is assigned to a unique pixel in the grid.</li>
  <li>The method iteratively swaps feature positions to reduce the discrepancy between:
    <ul>
      <li>the ranking of feature distances in the original tabular space;</li>
      <li>the ranking of pixel distances in the image space.</li>
    </ul>
  </li>
  <li>The final image representation is dense: each selected feature occupies one pixel.</li>
</ol>

<p>This makes IGTD especially suitable when compact image representations are desired. Unlike methods that may create sparse images or require blurring, IGTD tends to generate dense grids where most pixels carry feature information.</p>

<p><img src="/images/Blog/2026-06-27-05-igtd-pipeline.png" alt="IGTD transformation pipeline" />
<em>(Figure 5. IGTD transformation pipeline. The method searches for a dense assignment of features to pixels by minimizing the discrepancy between feature-distance rankings in the original tabular space and spatial-distance rankings in the generated image.)</em></p>

<h3 id="strengths-and-limitations-2">Strengths and limitations</h3>

<p>IGTD is useful when the objective is to create compact synthetic images with a direct relationship between features and pixels. This can reduce the input size required by CNNs and improve computational efficiency during neural training.</p>

<p>However, the optimization process can still be costly for high-dimensional datasets. In addition, the resulting images may be less visually intuitive than TINTO representations, especially when the grid is very dense or when feature relationships are complex.</p>

<hr />

<h2 id="comparative-pipeline-overview">Comparative pipeline overview</h2>

<p>Although TINTO, REFINED and IGTD all transform tabular samples into images, their assumptions are different. TINTO emphasizes projection and optional smoothing. REFINED emphasizes distance-preserving spatial optimization. IGTD emphasizes dense pixel assignment based on ranking preservation.</p>

<h2 id="comparative-summary">Comparative summary</h2>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Dimension</th>
      <th style="text-align: left">TINTO</th>
      <th style="text-align: left">REFINED</th>
      <th style="text-align: left">IGTD</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>Core idea</strong></td>
      <td style="text-align: left">Dimensionality reduction + pixel mapping + optional blurring</td>
      <td style="text-align: left">Distance-preserving feature map optimization</td>
      <td style="text-align: left">Ranking-preserving dense pixel assignment</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Mathematical basis</strong></td>
      <td style="text-align: left">PCA / t-SNE and blurring</td>
      <td style="text-align: left">MDS / Bayesian MDS + hill climbing</td>
      <td style="text-align: left">Feature similarity ranking vs. pixel-distance ranking</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Computational cost</strong></td>
      <td style="text-align: left">Low to medium</td>
      <td style="text-align: left">Medium to high</td>
      <td style="text-align: left">Medium to high</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Visual representation</strong></td>
      <td style="text-align: left">Sparse or semi-sparse with blurring</td>
      <td style="text-align: left">Optimized spatial grid</td>
      <td style="text-align: left">Dense and compact grid</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>One feature per pixel</strong></td>
      <td style="text-align: left">Not necessarily</td>
      <td style="text-align: left">Usually spatially assigned</td>
      <td style="text-align: left">Yes, dense assignment</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Best suited for</strong></td>
      <td style="text-align: left">Fast experimentation, visual intuition, hybrid models</td>
      <td style="text-align: left">High-dimensional scientific datasets where distance preservation matters</td>
      <td style="text-align: left">Compact representations and efficient CNN input</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Main limitation</strong></td>
      <td style="text-align: left">Sensitive to dimensionality-reduction choices</td>
      <td style="text-align: left">Higher optimization cost</td>
      <td style="text-align: left">Optimization can be expensive for many features</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Data leakage risk</strong></td>
      <td style="text-align: left">Must fit only on training data</td>
      <td style="text-align: left">Must fit only on training data</td>
      <td style="text-align: left">Must fit only on training data</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Interpretability</strong></td>
      <td style="text-align: left">High visual intuition due to blurring and spatial patterns</td>
      <td style="text-align: left">Strong geometric interpretation</td>
      <td style="text-align: left">Compact but sometimes less visually intuitive</td>
    </tr>
  </tbody>
</table>

<p><img src="/images/Blog/2026-06-27-05-method-selection-map.png" alt="Decision map for selecting TINTO, REFINED or IGTD" />
<em>(Figure 6. Practical decision map for selecting among TINTO, REFINED and IGTD depending on the experimental objective. The choice depends on whether the priority is fast experimentation, distance-preserving spatial optimization, dense image construction, interpretability, or computational efficiency.)</em></p>

<hr />

<h2 id="methodological-note-avoid-data-leakage">Methodological note: avoid data leakage</h2>

<p>A critical issue in tabular data into synthetic image transformation is <strong>data leakage</strong>.</p>

<p>If the spatial layout of the features is learned using the full dataset before splitting into training and test partitions, information from the test set may influence the generated image representation. This can lead to overly optimistic results and invalid generalization estimates.</p>

<p>For rigorous experimentation, the recommended workflow is:</p>

<ol>
  <li>Split the original tabular dataset into training and test partitions.</li>
  <li>Fit the tabular data into synthetic images transformation only on the training data.</li>
  <li>Apply the learned transformation to both training and test data.</li>
  <li>Train the neural model using only the generated training images.</li>
  <li>Evaluate the final model on the generated test images.</li>
</ol>

<p>This principle is especially important when comparing TINTO, REFINED and IGTD, because the comparison should reflect the generalization capacity of each representation, not hidden information transferred from the test set.</p>

<hr />

<h2 id="practical-implementation-in-python-with-tintolib">Practical implementation in Python with TINTOlib</h2>

<p>One of the main advantages of <strong>TINTOlib</strong> is that it provides a unified interface for different tabular data into synthetic image transformation methods. This makes it possible to compare TINTO, REFINED and IGTD within a common experimental workflow.</p>

<p>The following example uses the <em>Breast Cancer Wisconsin</em> dataset from Scikit-Learn. The key methodological point is that the train/test split is performed before fitting any transformation.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">os</span>
<span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>

<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_breast_cancer</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>

<span class="kn">from</span> <span class="nn">TINTOlib.tinto</span> <span class="kn">import</span> <span class="n">TINTO</span>
<span class="kn">from</span> <span class="nn">TINTOlib.igtd</span> <span class="kn">import</span> <span class="n">IGTD</span>
<span class="kn">from</span> <span class="nn">TINTOlib.refined</span> <span class="kn">import</span> <span class="n">REFINED</span>

<span class="c1"># ---------------------------------------------------------
# 1. Load a reproducible tabular dataset
# ---------------------------------------------------------
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_breast_cancer</span><span class="p">()</span>

<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span><span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span> <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span><span class="p">)</span>
<span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span>

<span class="c1"># ---------------------------------------------------------
# 2. Split before fitting any tabular data into synthetic images transformation
# ---------------------------------------------------------
</span><span class="n">train_df</span><span class="p">,</span> <span class="n">test_df</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">df</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.2</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="mi">42</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span>
<span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 3. Create output folders
# ---------------------------------------------------------
</span><span class="n">output_dirs</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"TINTO"</span><span class="p">:</span> <span class="p">{</span>
        <span class="s">"train"</span><span class="p">:</span> <span class="s">"synthetic_images/tinto/train"</span><span class="p">,</span>
        <span class="s">"test"</span><span class="p">:</span> <span class="s">"synthetic_images/tinto/test"</span>
    <span class="p">},</span>
    <span class="s">"IGTD"</span><span class="p">:</span> <span class="p">{</span>
        <span class="s">"train"</span><span class="p">:</span> <span class="s">"synthetic_images/igtd/train"</span><span class="p">,</span>
        <span class="s">"test"</span><span class="p">:</span> <span class="s">"synthetic_images/igtd/test"</span>
    <span class="p">},</span>
    <span class="s">"REFINED"</span><span class="p">:</span> <span class="p">{</span>
        <span class="s">"train"</span><span class="p">:</span> <span class="s">"synthetic_images/refined/train"</span><span class="p">,</span>
        <span class="s">"test"</span><span class="p">:</span> <span class="s">"synthetic_images/refined/test"</span>
    <span class="p">}</span>
<span class="p">}</span>

<span class="k">for</span> <span class="n">method_dirs</span> <span class="ow">in</span> <span class="n">output_dirs</span><span class="p">.</span><span class="n">values</span><span class="p">():</span>
    <span class="n">os</span><span class="p">.</span><span class="n">makedirs</span><span class="p">(</span><span class="n">method_dirs</span><span class="p">[</span><span class="s">"train"</span><span class="p">],</span> <span class="n">exist_ok</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
    <span class="n">os</span><span class="p">.</span><span class="n">makedirs</span><span class="p">(</span><span class="n">method_dirs</span><span class="p">[</span><span class="s">"test"</span><span class="p">],</span> <span class="n">exist_ok</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>

<span class="c1"># ---------------------------------------------------------
# 4. Define the transformation methods
# ---------------------------------------------------------
</span><span class="n">methods</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"TINTO"</span><span class="p">:</span> <span class="n">TINTO</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"supervised"</span><span class="p">,</span>
        <span class="n">algorithm</span><span class="o">=</span><span class="s">"t-SNE"</span><span class="p">,</span>
        <span class="n">pixels</span><span class="o">=</span><span class="mi">30</span><span class="p">,</span>
        <span class="n">blur</span><span class="o">=</span><span class="bp">True</span>
    <span class="p">),</span>
    <span class="s">"IGTD"</span><span class="p">:</span> <span class="n">IGTD</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"supervised"</span>
    <span class="p">),</span>
    <span class="s">"REFINED"</span><span class="p">:</span> <span class="n">REFINED</span><span class="p">(</span>
        <span class="n">problem</span><span class="o">=</span><span class="s">"supervised"</span>
    <span class="p">)</span>
<span class="p">}</span>

<span class="c1"># ---------------------------------------------------------
# 5. Fit each method only on the training partition
#    and then transform both train and test partitions
# ---------------------------------------------------------
</span><span class="k">for</span> <span class="n">method_name</span><span class="p">,</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">methods</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
    <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Generating synthetic images with </span><span class="si">{</span><span class="n">method_name</span><span class="si">}</span><span class="s">..."</span><span class="p">)</span>

    <span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
        <span class="n">train_df</span><span class="p">,</span>
        <span class="n">output_dirs</span><span class="p">[</span><span class="n">method_name</span><span class="p">][</span><span class="s">"train"</span><span class="p">]</span>
    <span class="p">)</span>

    <span class="n">model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span>
        <span class="n">test_df</span><span class="p">,</span>
        <span class="n">output_dirs</span><span class="p">[</span><span class="n">method_name</span><span class="p">][</span><span class="s">"test"</span><span class="p">]</span>
    <span class="p">)</span>

<span class="k">print</span><span class="p">(</span><span class="s">"Synthetic image generation completed successfully."</span><span class="p">)</span>
</code></pre></div></div>

<p>The generated image folders can then be used with standard PyTorch or TensorFlow pipelines, for example through <code class="language-plaintext highlighter-rouge">torchvision.datasets.ImageFolder</code> or custom dataset loaders.</p>

<p>After executing the transformation pipeline, each method generates a different synthetic image representation from the original tabular samples. Although the input data are the same, the resulting images are not visually equivalent, because each method follows a different criterion to organize the features in the image space.</p>

<ul>
  <li>IGTD produces compact grid-like representations where the feature-to-pixel assignment is guided by the preservation of distance relationships.</li>
  <li>REFINED generates spatial layouts where the arrangement of features is optimized according to pairwise relationships among variables.</li>
  <li>TINTO creates structured synthetic images with an explicit visual encoding, where dimensionality reduction and optional blurring help introduce spatial continuity.</li>
</ul>

<p>The following figure illustrates these differences by showing representative synthetic images generated with the three methods. The goal is not to decide which image is visually more appealing, but to highlight that each method creates a different spatial topology. These topologies may affect how CNNs, Vision Transformers or hybrid neural networks learn from the transformed tabular data.</p>

<p><img src="/images/Blog/2026-06-27-05-tinto-vs-refined-vs-igtd.png" alt="Synthetic images generated with IGTD, REFINED and TINTO" /> 
<em>(Figure 7. Visual comparison of synthetic images generated with IGTD, REFINED and TINTO. Each method transforms the same type of tabular data into a different image topology, reflecting its own spatial encoding criterion and potentially influencing how vision-based neural models learn from the generated representations.)</em></p>

<hr />

<h2 id="practical-interpretation">Practical interpretation</h2>

<p>From a practical point of view, the three methods should be seen as complementary rather than mutually exclusive:</p>

<ul>
  <li>Use <strong>TINTO</strong> when the objective is fast experimentation, visual interpretability and flexible synthetic image generation.</li>
  <li>Use <strong>REFINED</strong> when the dataset contains complex feature relationships and the preservation of geometric distances is central to the experiment.</li>
  <li>Use <strong>IGTD</strong> when dense and compact image representations are needed, especially for efficient CNN-based training.</li>
</ul>

<p>In all cases, the generated images should be evaluated against strong tabular baselines such as Random Forest, XGBoost, LightGBM or CatBoost. Synthetic images are not automatically superior to classical models; their value depends on whether the spatial representation helps the neural architecture exploit meaningful feature interactions.</p>

<hr />

<h2 id="conclusion">Conclusion</h2>

<p>TINTO, REFINED and IGTD represent three different ways of addressing the same fundamental question: <strong>how can we construct a meaningful spatial representation from tabular data?</strong></p>

<p>TINTO provides a flexible and visually intuitive transformation based on dimensionality reduction and optional blurring. REFINED focuses on preserving feature relationships through geometric optimization. IGTD generates dense image layouts by aligning feature-similarity rankings with pixel-distance rankings.</p>

<p>The key point is that these methods should not be evaluated only by the visual appearance of the generated images. They must be assessed through rigorous experimental protocols, strong tabular baselines, leakage-free validation, and downstream performance using CNNs, Vision Transformers or hybrid neural architectures.</p>

<p>TINTOlib makes this comparison practical by providing a unified framework where different tabular data into synthetic image methods can be tested under comparable conditions. This is essential for understanding when synthetic images are genuinely useful, when they provide interpretable spatial structure, and when classical tabular models may still remain the strongest baseline.</p>

<hr />

<h2 id="references-and-related-publications">References and related publications</h2>

<p>The concepts discussed in this tutorial are connected to the following research and software publications on TINTO, TINTOlib, tabular data into synthetic images transformation, synthetic spatial representations, hybrid neural networks and indoor localisation.</p>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Synthetic Images" /><category term="Tabular Data" /><category term="Deep Learning" /><category term="Computer Vision" /><category term="Spatial Encoding" /><category term="IGTD" /><category term="REFINED" /><category term="TINTO" /><summary type="html"><![CDATA[Comparative analysis of TINTO, REFINED and IGTD, three representative tabular data into synthetic image transformation methods available in TINTOlib for generating synthetic images from tabular data.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-06-27-05-same-sample-tinto-refined-igtd.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Improving Deep Learning by Exploiting Synthetic Images — Part II: From Synthetic Images to Hybrid Neural Networks</title><link href="https://www.manuelcastillo.eu/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks/" rel="alternate" type="text/html" title="Improving Deep Learning by Exploiting Synthetic Images — Part II: From Synthetic Images to Hybrid Neural Networks" /><published>2026-06-03T00:00:00+02:00</published><updated>2026-06-03T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks-part-2</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks/"><![CDATA[<link rel="canonical" href="https://www.manuelcastillo.eu/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks/" />

<meta name="robots" content="index,follow,max-image-preview:large" />

<meta name="description" content="Part II of a theoretical and technical series on synthetic images for tabular data, focusing on TINTOlib, preferred spatial encoding methods, hybrid neural networks, and explainable AI." />

<meta property="og:type" content="article" />

<meta property="og:title" content="Improving Deep Learning by Exploiting Synthetic Images — Part II: From Synthetic Images to Hybrid Neural Networks" />

<meta property="og:description" content="Part II of a theoretical and technical series on synthetic images for tabular data, focusing on TINTOlib, preferred spatial encoding methods, hybrid neural networks, and explainable AI." />

<meta property="og:url" content="https://www.manuelcastillo.eu/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks/" />

<meta property="og:image" content="https://www.manuelcastillo.eu/images/Blog/2026-06-02-04-xai-hynn.png" />

<meta property="article:published_time" content="2026-06-03T00:00:00+02:00" />

<meta property="article:modified_time" content="2026-06-03T00:00:00+02:00" />

<meta property="article:author" content="Manuel Castillo-Cara" />

<meta property="article:section" content="TINTOlib" />

<meta property="article:tag" content="TINTOlib" />

<meta property="article:tag" content="Synthetic Images" />

<meta property="article:tag" content="Tabular-to-Image" />

<meta property="article:tag" content="Hybrid Neural Networks" />

<meta property="article:tag" content="Deep Learning" />

<meta property="article:tag" content="CNN" />

<meta property="article:tag" content="Vision Transformer" />

<meta property="article:tag" content="Explainable AI" />

<meta property="article:tag" content="Spatial Encoding" />

<meta name="twitter:card" content="summary_large_image" />

<meta name="twitter:title" content="Improving Deep Learning by Exploiting Synthetic Images — Part II: From Synthetic Images to Hybrid Neural Networks" />

<meta name="twitter:description" content="Part II of a theoretical and technical series on synthetic images for tabular data, focusing on TINTOlib, preferred spatial encoding methods, hybrid neural networks, and explainable AI." />

<meta name="twitter:image" content="https://www.manuelcastillo.eu/images/Blog/2026-06-02-04-xai-hynn.png" />

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "Improving Deep Learning by Exploiting Synthetic Images — Part II: From Synthetic Images to Hybrid Neural Networks",
  "description": "Part II of a theoretical and technical series on synthetic images for tabular data, focusing on TINTOlib, preferred spatial encoding methods, hybrid neural networks, and explainable AI.",
  "image": "https://www.manuelcastillo.eu/images/Blog/2026-06-02-04-xai-hynn.png",
  "author": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "publisher": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "datePublished": "2026-06-03T00:00:00+02:00",
  "dateModified": "2026-06-03T00:00:00+02:00",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://www.manuelcastillo.eu/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks/"
  },
  "articleSection": "TINTOlib",
  "keywords": "TINTOlib, Synthetic Images, Tabular-to-Image, Hybrid Neural Networks, Deep Learning, CNN, Vision Transformer, Explainable AI, Spatial Encoding"
}
</script>

<div style="background: linear-gradient(135deg, #1a237e 0%, #4a148c 45%, #065f46 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #c4b5fd; font-weight: 600;">TINTOlib · Hybrid Neural Networks · Explainable AI</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">From Synthetic Images to Hybrid Neural Networks</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #ede9fe; line-height: 1.55;">Part II — How TINTOlib transforms tabular data into spatial representations, which methods should be preferred, and how CNNs, ViTs and XAI fit into the pipeline.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ede9fe;">Synthetic Images</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ede9fe;">CNN</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ede9fe;">Vision Transformer</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #ede9fe;">XAI</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 260px; width: 100%;">
    <img src="/images/Blog/2026-06-02-04-xai-hynn.png" alt="From synthetic images to hybrid neural networks with TINTOlib" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<blockquote>
  <blockquote>
    <ul>
      <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
      <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
      <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
      <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
    </ul>
  </blockquote>
</blockquote>

<hr />

<h2 id="video-overview">Video overview</h2>

<p>This post is part of a two-part technical summary derived from the conference <em>Improving Deep Learning by Exploiting Synthetic Images</em>, delivered in Peru.</p>

<p>The following short video provides an English overview of the main ideas discussed across both posts: why tabular data remains challenging for deep learning, how synthetic images can introduce spatial representations, and how TINTOlib connects structured data with computer vision, hybrid neural networks and explainable AI.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-06-02-03-improving-deep-learning.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<blockquote>
  <p><strong>Additional material.</strong> The original conference recording is available in <strong>Spanish</strong>. The two blog posts provide an English technical synthesis and discussion based on that conference.</p>

  <p><a href="https://unedo365-my.sharepoint.com/:v:/g/personal/manuelcastillo_dia_uned_es/IQDov79-I54sS7jNgIIAaTS3AVs0L5cVinne29xXLZZNsc0?e=DVgrOZ">Open the original conference recording in SharePoint</a></p>
</blockquote>

<h2 id="from-theory-to-modelling">From theory to modelling</h2>

<p><a href="/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1/">Part I</a> introduced the theoretical motivation behind synthetic images for tabular data. The central point was that deep learning does not fail on tabular data because it is weak, but because many of its most successful architectures require structural assumptions that tables do not naturally provide.</p>

<p>This second part moves from the theoretical problem to the modelling pipeline. Once we accept that representation is central, the next questions are more practical:</p>

<ul>
  <li>How should the spatial representation be constructed?</li>
  <li>Which transformation methods are methodologically preferable?</li>
  <li>How can synthetic images be connected with CNNs, Vision Transformers and hybrid neural networks?</li>
  <li>How can visual explainability be mapped back to original tabular variables?</li>
</ul>

<p>These questions define the practical contribution of TINTOlib.</p>

<h2 id="tintolib-as-an-experimental-framework">TINTOlib as an experimental framework</h2>

<p>TINTOlib is not only a library for generating images. It is a framework for experimenting with a family of spatial representations for tabular data.</p>

<p>The value of a unified framework is methodological. Before TINTOlib, many tabular-to-image methods were implemented in separate repositories, with different APIs, assumptions and preprocessing requirements. This made systematic comparison difficult. TINTOlib provides a common interface that allows researchers to instantiate different methods, generate synthetic datasets and evaluate downstream architectures under more controlled conditions.</p>

<p>A typical experimental pipeline contains four stages:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Original tabular dataset
      |
      | train / validation / test split
      v
Fit spatial transformation only on training data
      |
      | transform each split
      v
Synthetic image dataset
      |
      | CNN / ViT / HyNN / XAI
      v
Evaluation and interpretation
</code></pre></div></div>

<p>The separation between fitting and transforming is essential. The spatial layout must be learned only from the training data. If the validation or test set participates in the construction of the feature layout, data leakage occurs. The model would indirectly access information from the evaluation split before prediction.</p>

<h2 id="preferred-families-of-spatial-encodings">Preferred families of spatial encodings</h2>

<p>The most important methodological distinction is between methods that learn or optimize the spatial structure of the features and methods that remain dependent on the arbitrary column order.</p>

<p>Methods such as <strong>TINTO</strong>, <strong>DeepInsight</strong>, <strong>IGTD</strong>, <strong>REFINED</strong>, <strong>Fotomics</strong> and recent unsupervised learning-based approaches such as <strong>Clusters</strong> are preferable when the goal is to build a spatial representation that reflects relationships in the data. They attempt to place related features close to one another through dimensionality reduction, similarity preservation, manifold learning, optimization or unsupervised representation learning.</p>

<p>This is the family of methods that best addresses the original problem. If tabular data have no natural spatial structure, the transformation method should construct one from the data, not inherit one from the arbitrary table layout.</p>

<p>By contrast, <strong>BarGraph</strong>, <strong>DistanceMatrix</strong>, <strong>Combination</strong>, <strong>SuperTML</strong>, <strong>BIE</strong> and <strong>FeatureWrap</strong> are more dependent on the original feature arrangement or on encoding schemes that can be influenced by how variables are ordered. These approaches can still be useful for comparison, teaching or specific datasets with meaningful order, but they should not be the first choice when working with generic tabular data whose column order is arbitrary.</p>

<p>The distinction can be summarized as follows:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Order-dependent encodings
    |
    | risk: inherit arbitrary column order
    v
Useful as baselines, but not recommended as primary methods for unordered tables

Data-driven spatial encodings
    |
    | objective: learn or optimize feature geometry
    v
Recommended for rigorous tabular-to-image experimentation
</code></pre></div></div>

<p>The methodological distinction becomes clearer when we compare the visual outputs of different transformation families. Some approaches generate images by imposing relatively direct or handcrafted encodings over the original feature arrangement. These methods can be useful for comparison, teaching, or specific datasets with meaningful feature order, but they may remain sensitive to the arbitrary ordering of the tabular columns.</p>

<p>Other methods attempt to construct a spatial representation from the data structure itself. In this second family, the image is not merely a visual formatting of the table; it is the result of a projection, optimization, similarity-preserving transformation, or unsupervised representation learning process. This distinction is central when synthetic images are used as input to CNNs, Vision Transformers, or hybrid neural architectures.</p>

<p><img src="/images/Blog/2026-06-02-04-supervised-synthetic-image-methods.png" alt="Supervised tabular-to-image methods" />
<em>(Figure 1. Examples of supervised tabular-to-image transformation methods available in the TINTOlib ecosystem. These methods generate synthetic image representations from structured data, but they differ substantially in how they define or learn the spatial arrangement of the original variables. The methodological relevance of each image depends not only on its visual appearance, but also on whether its spatial structure reflects meaningful relationships between features.)</em></p>

<p><img src="/images/Blog/2026-06-02-04-unsupervised-synthetic-image-methods.png" alt="Unsupervised tabular-to-image methods" />
<em>(Figure 2. Examples of unsupervised tabular-to-image transformation methods. Unlike encodings that directly inherit the original column order, data-driven spatial methods aim to construct image-like representations from statistical, geometric or neighbourhood relationships among variables. This is essential when the original table has no natural spatial layout.)</em></p>

<h2 id="why-blurring-matters">Why blurring matters</h2>

<p>One of the distinctive aspects of the TINTO method is the use of blurring. Blurring should not be understood as a cosmetic operation. It has a representational role.</p>

<p>When a feature value is projected into a pixel grid, the resulting image may be sparse or discontinuous. Blurring smooths local regions and can create more continuous spatial patterns. This may help convolutional filters detect local structures more effectively, because the information is not restricted to isolated pixels.</p>

<p>From a neural network perspective, blurring can be understood as a way of inducing local continuity. It transforms a discrete feature placement into a smoother visual signal. This does not guarantee better performance, but it creates a representation that is more aligned with the assumptions of convolutional processing.</p>

<p>The important point is that blurring must be evaluated empirically. Its usefulness may depend on the dataset, the image size, the density of the feature layout and the architecture used downstream.</p>

<h2 id="connecting-synthetic-images-with-cnns-and-vision-transformers">Connecting synthetic images with CNNs and Vision Transformers</h2>

<p>Once the tabular dataset has been transformed into synthetic images, several visual architectures become available.</p>

<p>A CNN processes the synthetic image through convolutional filters. If the feature layout has been constructed properly, nearby pixels may correspond to related variables, and local filters may capture interactions between them.</p>

<p>A Vision Transformer processes the image as a set of patches. This makes it possible to model longer-range relationships between regions of the synthetic image. For larger synthetic images or richer feature layouts, attention mechanisms may capture interactions that are not strictly local.</p>

<p>However, neither CNNs nor ViTs should be used as black-box replacements for classical models. The correct experimental design should include strong baselines:</p>

<ul>
  <li>tree-based models such as Random Forest, XGBoost, LightGBM or CatBoost;</li>
  <li>an MLP trained directly on the original tabular data;</li>
  <li>several tabular-to-image methods;</li>
  <li>several image sizes;</li>
  <li>CNN, ViT and hybrid architectures;</li>
  <li>ablation studies with and without blurring;</li>
  <li>validation protocols that prevent data leakage.</li>
</ul>

<p>Only under this type of comparison can we determine whether the synthetic image representation adds value.</p>

<h2 id="hybrid-neural-networks">Hybrid Neural Networks</h2>

<p>A particularly relevant architecture is the <strong>Hybrid Neural Network</strong>. Instead of choosing between the original tabular data and the synthetic image, a hybrid model uses both.</p>

<p>A typical design includes:</p>

<ol>
  <li>a tabular branch, usually an MLP that receives the original feature vector;</li>
  <li>an image branch, usually a CNN or ViT that receives the synthetic image;</li>
  <li>a fusion layer, where both representations are concatenated or combined;</li>
  <li>a prediction head for classification or regression.</li>
</ol>

<p>This architecture is conceptually attractive because it avoids discarding the original tabular representation. The tabular branch can learn direct variable-level patterns, while the image branch can learn spatial interactions produced by the transformation method.</p>

<p>Since the main image of this post already summarizes the hybrid-neural-network idea, we will not duplicate that slide here. The important point is architectural: the hybrid model preserves the original tabular information while simultaneously exploiting a synthetic image representation derived from TINTOlib.</p>

<p>In indoor localisation, this design is especially meaningful. Wireless measurements can be represented as tabular features, but they may also contain latent spatial or structural patterns. A hybrid architecture can exploit both perspectives simultaneously.</p>

<p><img src="/images/Blog/2026-06-02-04-from-synthetic-images-to-hybrid-neural-networks.png" alt="Unsupervised tabular-to-image methods" />
<em>(Figure 3. A simplified illustration of the HyNN architecture. This figure shows that either CNN or ViT can be used as the vision component, while the MLP component processes tabular data directly. It also highlights the flexibility of the model, which allows for using only the vision or MLP part, illustrating the different architectures evaluated in this study.)</em></p>

<h2 id="explainable-ai-over-synthetic-images">Explainable AI over synthetic images</h2>

<p>Interpretability is one of the most important motivations for the synthetic image paradigm.</p>

<p>In a conventional neural network trained on tabular data, explanations are usually produced at the variable level. In a CNN trained on synthetic images, explanations can be produced visually. For example, methods such as Grad-CAM or saliency maps can identify regions of the synthetic image that were influential for the prediction.</p>

<p>The key step is to map those regions back to the original variables. Since the synthetic image is generated from a known feature layout, each pixel or region can be associated with one or more original tabular features. This allows a visual explanation to be translated back into the structured-data domain.</p>

<p>The first level of interpretation operates directly over the synthetic image. Since each region of the image is generated from a known spatial encoding of the original variables, visual attribution maps can be inspected not only as image explanations, but also as indirect explanations over the tabular feature space.</p>

<p><img src="/images/Blog/2026-06-02-04-aix-tintolib-feature-map.png" alt="AIX in TINTOlib feature attribution map" />
<em>(Figure 4. AIX-based interpretation of synthetic tabular images in TINTOlib. Visual attribution maps can identify relevant regions of the synthetic image, which can then be related back to the original tabular variables through the known spatial encoding. This provides a bridge between image-based explainability and feature-level interpretation in structured data problems.)</em></p>

<p>In hybrid architectures, this interpretability layer becomes even more relevant. The model can be analysed from two complementary perspectives: the tabular branch, which operates over the original feature vector, and the image branch, which operates over the synthetic spatial representation. This makes it possible to study whether both branches rely on consistent information or whether each one captures different aspects of the problem.</p>

<p><img src="/images/Blog/2026-06-02-04-xai-hynn.png" alt="XAI in hybrid neural networks" />
<em>(Figure 5. Explainable AI workflow for hybrid neural networks combining tabular and synthetic image representations. The image branch enables visual attribution over the generated synthetic representation, while the tabular branch preserves direct access to the original variables. This makes it possible to connect spatial explanations with feature-level reasoning in hybrid deep learning models.)</em></p>

<p>This is one of the reasons why the method is not only useful for prediction. It also creates a framework for studying how neural networks use transformed tabular information.</p>

<h2 id="indoor-localisation-as-a-representative-use-case">Indoor localisation as a representative use case</h2>

<p>The conference used indoor localisation as one of the representative domains for this paradigm. In MIMO-based and Bluetooth-based localisation problems, the input may consist of signal measurements, antenna-related variables or channel-state information. These variables are usually stored as tables, but they may contain complex structural dependencies.</p>

<p>Transforming these signals into synthetic images makes it possible to evaluate whether spatial encodings expose patterns that are difficult to exploit from the raw tabular representation. CNNs and ViTs can then process those patterns, while hybrid architectures can combine them with the original signal vector.</p>

<p>This does not mean that indoor localisation is the only application. The same idea can be applied to biomedical data, industrial monitoring, educational analytics, cybersecurity, financial risk modelling, sensor networks and many other domains where the input is tabular but the relationships between variables are complex.</p>

<h2 id="what-the-paradigm-does-not-claim">What the paradigm does not claim</h2>

<p>A rigorous interpretation of synthetic images for tabular data must avoid exaggerated claims.</p>

<p>The method does not claim that every table should become an image. It does not claim that CNNs will always outperform XGBoost. It does not claim that a synthetic image is semantically equivalent to a natural image.</p>

<p>The claim is more precise:</p>

<blockquote>
  <p>If the feature layout is constructed in a meaningful way, synthetic images can provide a spatial representation that allows visual and hybrid neural architectures to exploit relationships in tabular data.</p>
</blockquote>

<p>This statement is testable. It requires benchmarks, ablations, strong baselines and careful validation.</p>

<h2 id="practical-recommendations">Practical recommendations</h2>

<p>For researchers and students working with TINTOlib, the following recommendations are important.</p>

<p>First, always split the data before fitting the transformation. Data leakage at the representation stage invalidates the evaluation.</p>

<p>Second, do not rely on order-dependent encodings as primary methods when the original feature order is arbitrary. Use them as baselines or teaching tools, but prioritize data-driven spatial encodings such as TINTO, DeepInsight, IGTD, REFINED, Fotomics and Clusters.</p>

<p>Third, compare against strong classical baselines. A synthetic image pipeline should not be evaluated only against weak neural models.</p>

<p>Fourth, evaluate several image sizes and architectures. The optimal spatial resolution may depend on the number of variables and the density of the feature layout.</p>

<p>Fifth, include interpretability analyses. One of the strengths of synthetic images is that they create a bridge between visual explanations and tabular variables.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Synthetic image generation from tabular data is not a superficial visualization technique. It is a representational strategy for connecting structured data with computer vision and hybrid neural architectures.</p>

<p>The central methodological requirement is that the image must have a meaningful spatial structure. If the image merely reflects the arbitrary order of the columns, the transformation reproduces the original limitation of tabular data. If, however, the spatial layout is learned or optimized from the relationships between variables, the resulting representation can provide a useful bridge toward deep learning.</p>

<p>TINTOlib provides the practical environment for exploring this idea. It enables systematic comparison of spatial encodings, integration with CNNs and Vision Transformers, development of hybrid neural networks and application of explainability techniques to synthetic tabular images.</p>

<p>The broader lesson is that deep learning performance depends not only on the architecture, but also on the representation. For tabular data, representation may be the decisive step.</p>

<h2 id="references-and-related-publications">References and related publications</h2>

<p>The concepts presented in this tutorial are connected to the following research and software publications on TINTO, TINTOlib, tabular-to-image transformation, synthetic spatial representations, hybrid neural networks, indoor localisation and explainable artificial intelligence.</p>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Synthetic Images" /><category term="Tabular-to-Image" /><category term="Hybrid Neural Networks" /><category term="Deep Learning" /><category term="CNN" /><category term="Vision Transformer" /><category term="Explainable AI" /><category term="Spatial Encoding" /><summary type="html"><![CDATA[Part II of a theoretical and technical series on synthetic images for tabular data, focusing on TINTOlib, preferred spatial encoding methods, hybrid neural networks, and explainable AI.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-06-02-04-xai-hynn.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-06-02-04-xai-hynn.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Improving Deep Learning by Exploiting Synthetic Images — Part I: Why Tabular Data Needs Spatial Representations</title><link href="https://www.manuelcastillo.eu/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1/" rel="alternate" type="text/html" title="Improving Deep Learning by Exploiting Synthetic Images — Part I: Why Tabular Data Needs Spatial Representations" /><published>2026-06-02T00:00:00+02:00</published><updated>2026-06-02T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1/"><![CDATA[<link rel="canonical" href="https://www.manuelcastillo.eu/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1/" />

<meta name="robots" content="index,follow,max-image-preview:large" />

<meta name="description" content="Part I of a theoretical and technical series on why deep learning still struggles with tabular data, and why synthetic image representations provide a promising bridge between structured data and computer vision architectures." />

<meta property="og:type" content="article" />

<meta property="og:title" content="Improving Deep Learning by Exploiting Synthetic Images — Part I: Why Tabular Data Needs Spatial Representations" />

<meta property="og:description" content="Part I of a theoretical and technical series on why deep learning still struggles with tabular data, and why synthetic image representations provide a promising bridge between structured data and computer vision architectures." />

<meta property="og:url" content="https://www.manuelcastillo.eu/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1/" />

<meta property="og:image" content="https://www.manuelcastillo.eu/images/Blog/2026-06-02-03-improving-deep-learning-exploiting-synthetic-images.png" />

<meta property="article:published_time" content="2026-06-02T00:00:00+02:00" />

<meta property="article:modified_time" content="2026-06-02T00:00:00+02:00" />

<meta property="article:author" content="Manuel Castillo-Cara" />

<meta property="article:section" content="TINTOlib" />

<meta property="article:tag" content="TINTOlib" />

<meta property="article:tag" content="Synthetic Images" />

<meta property="article:tag" content="Tabular-to-Image" />

<meta property="article:tag" content="Tabular Data" />

<meta property="article:tag" content="Deep Learning" />

<meta property="article:tag" content="Computer Vision" />

<meta property="article:tag" content="Spatial Encoding" />

<meta property="article:tag" content="Machine Learning" />

<meta property="article:tag" content="Data Science" />

<meta name="twitter:card" content="summary_large_image" />

<meta name="twitter:title" content="Improving Deep Learning by Exploiting Synthetic Images — Part I: Why Tabular Data Needs Spatial Representations" />

<meta name="twitter:description" content="Part I of a theoretical and technical series on why deep learning still struggles with tabular data, and why synthetic image representations provide a promising bridge between structured data and computer vision architectures." />

<meta name="twitter:image" content="https://www.manuelcastillo.eu/images/Blog/2026-06-02-03-improving-deep-learning-exploiting-synthetic-images.png" />

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "Improving Deep Learning by Exploiting Synthetic Images — Part I: Why Tabular Data Needs Spatial Representations",
  "description": "Part I of a theoretical and technical series on why deep learning still struggles with tabular data, and why synthetic image representations provide a promising bridge between structured data and computer vision architectures.",
  "image": "https://www.manuelcastillo.eu/images/Blog/2026-06-02-03-improving-deep-learning-exploiting-synthetic-images.png",
  "author": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "publisher": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "datePublished": "2026-06-02T00:00:00+02:00",
  "dateModified": "2026-06-02T00:00:00+02:00",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://www.manuelcastillo.eu/blog/2026/06/03-improving-deep-learning-exploiting-synthetic-images-part-1/"
  },
  "articleSection": "TINTOlib",
  "keywords": "TINTOlib, Synthetic Images, Tabular-to-Image, Tabular Data, Deep Learning, Computer Vision, Spatial Encoding, Machine Learning, Data Science"
}
</script>

<div style="background: linear-gradient(135deg, #0f172a 0%, #1e3a8a 45%, #14532d 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #bfdbfe; font-weight: 600;">TINTOlib · Synthetic Images · Tabular Data</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">Improving Deep Learning by Exploiting Synthetic Images</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #dbeafe; line-height: 1.55;">Part I — Why tabular data remains a difficult domain for deep learning, and why representation is the central methodological problem.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">Tabular Data</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">Deep Learning</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">Spatial Encoding</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e0f2fe;">TINTOlib</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 260px; width: 100%;">
    <img src="/images/Blog/2026-06-02-03-improving-deep-learning-exploiting-synthetic-images.png" alt="Improving deep learning by exploiting synthetic images" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<blockquote>
  <blockquote>
    <ul>
      <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
      <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
      <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
      <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
    </ul>
  </blockquote>
</blockquote>

<hr />

<h2 id="video-overview">Video overview</h2>

<p>This post is part of a two-part technical summary derived from the conference <em>Improving Deep Learning by Exploiting Synthetic Images</em>, delivered in Peru.</p>

<p>The following short video provides an English overview of the main ideas discussed across both posts: why tabular data remains challenging for deep learning, how synthetic images can introduce spatial representations, and how TINTOlib connects structured data with computer vision, hybrid neural networks and explainable AI.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <video controls="" preload="metadata" style="position: absolute; top: 0; left: 0; width: 100%; height: 100%; border-radius: 10px; background: #000;">
    <source src="/video/Blog/2026-06-02-03-improving-deep-learning.mp4" type="video/mp4" />
    Your browser does not support the video tag.
  </video>
</div>

<blockquote>
  <p><strong>Additional material.</strong> The original conference recording is available in <strong>Spanish</strong>. The two blog posts provide an English technical synthesis and discussion based on that conference.</p>

  <p><a href="https://unedo365-my.sharepoint.com/:v:/g/personal/manuelcastillo_dia_uned_es/IQDov79-I54sS7jNgIIAaTS3AVs0L5cVinne29xXLZZNsc0?e=DVgrOZ">Open the original conference recording in SharePoint</a></p>
</blockquote>

<h2 id="introduction-why-another-post-on-synthetic-images">Introduction: why another post on synthetic images?</h2>

<p>Most introductions to deep learning start from domains where the data already have a rich native structure: images, text, audio, video or graphs. In those domains, the input representation is not merely a container of values; it already carries some form of organization. Pixels are arranged in a plane. Words appear in sequences. Audio samples evolve over time. Graphs encode nodes and edges.</p>

<p>Tabular data are different. A table is one of the most common data structures in science, industry and public administration, but its geometry is weakly defined. Rows represent samples and columns represent variables, yet the order of those variables is usually arbitrary. A tabular dataset may contain age, sex, income, biomarkers, signal measurements, sensor values or derived indicators, but the fact that one column appears before another rarely means that both variables are spatial neighbours.</p>

<p>This creates a paradox. Deep learning has transformed computer vision, natural language processing and generative modelling, but for many tabular problems classical machine learning models remain extremely strong. Random Forest, XGBoost, LightGBM and CatBoost are still difficult baselines to beat. The problem is not simply that deep learning is less powerful. The problem is that many of its most successful architectures are designed to exploit structure that tabular data do not naturally provide.</p>

<p>The theoretical question addressed in the conference, and in this post, is therefore the following:</p>

<blockquote>
  <p>Can we improve deep learning on tabular data by constructing a meaningful spatial representation before applying the neural architecture?</p>
</blockquote>

<p>This question is the starting point for tabular-to-image transformation, synthetic image generation from structured data and the TINTOlib framework.</p>

<h2 id="data-science-as-a-transformation-from-data-to-knowledge">Data science as a transformation from data to knowledge</h2>

<p>A useful way to frame data science is to see it as a transformation pipeline: data are collected, curated, represented, modelled and interpreted in order to produce knowledge. This knowledge should not be limited to a numerical prediction. It should be reproducible, generalizable and sufficiently interpretable to support scientific or operational decisions.</p>

<p>In practice, the first difficulty is that real-world data are heterogeneous. Data may arrive as images, time series, text, graphs or tables. In many institutional and industrial scenarios, however, the dominant format is tabular. Corporate databases, biomedical registries, educational records, indoor localisation measurements, sensor logs and many scientific datasets are naturally stored as tables.</p>

<p>This is why the tabular domain is so important. A method that improves learning from tabular data can have impact across many applied areas. At the same time, this is why the problem is difficult. Tabular datasets often combine numerical and categorical variables, heterogeneous scales, missing values, non-linear dependencies, interactions between variables and relatively small sample sizes compared with modern image or language datasets.</p>

<p><img src="/images/Blog/2026-06-02-03-tabular-bottleneck.png" alt="Tabular data bottleneck" /></p>

<p><em>(Figure 1. Motivation of the tabular data bottleneck. A large fraction of real-world organisational and scientific data is stored in tabular form, yet standard deep learning architectures do not naturally exploit this representation. The key methodological challenge is to transform structured data into representations that preserve variable relationships while remaining suitable for modern neural architectures.)</em></p>

<p>The central claim of this post is that representation is not a secondary detail. It is a fundamental modelling decision. If the representation is inadequate, even a powerful neural architecture may fail to exploit the relevant structure of the problem.</p>

<h2 id="why-cnns-and-vits-work-so-well-on-images">Why CNNs and ViTs work so well on images</h2>

<p>To understand why tabular data are difficult, it is useful to recall why deep learning works so well in computer vision.</p>

<p>A natural image has spatial locality. Neighbouring pixels tend to be related. They may belong to the same edge, texture, object or background region. CNNs exploit this property through convolutional filters that slide across the image. These filters detect local patterns and reuse them across different spatial positions. This creates an architectural prior: the model assumes that local structures matter and that patterns can appear in different parts of the image.</p>

<p>Vision Transformers follow a different strategy, but they also assume an organized visual representation. An image is divided into patches, each patch is embedded, and attention mechanisms learn relationships between patches. The model is not restricted to local filters in the same way as a CNN, but it still begins from a spatially arranged representation.</p>

<p>In both cases, the input representation supports the architecture. The image is not just a vector. It is a structured object.</p>

<p>A raw tabular dataset does not provide this kind of support. If a table is treated as an image by simply reshaping columns into a matrix, the resulting arrangement may be arbitrary. The position of a feature in the synthetic grid may depend on column order rather than on meaningful relationships. This is precisely the problem that tabular-to-image methods attempt to solve.</p>

<p><img src="/images/Blog/2026-06-02-03-cnn-fails-tabular-direct-matrix.png" alt="Why CNNs fail on direct tabular matrices" /></p>

<p><em>(Figure 2. Visual metaphor illustrating why CNNs are not directly suited to raw tabular matrices. In natural images, neighbouring pixels encode meaningful local and spatial correlations, allowing convolutional filters to detect edges, textures and shapes. In tabular data, however, column order is usually arbitrary: reordering variables such as age, salary or sex changes the apparent pixel arrangement while preserving the semantic content of the sample. A CNN applied directly to such a matrix may therefore learn artefacts induced by column order rather than meaningful feature interactions.)</em></p>

<p>This visual metaphor is also important when evaluating tabular-to-image transformation methods. A method that simply converts a table into an image without solving the ordering problem may still expose a CNN to an arbitrary geometry. The objective is not only to obtain an image, but to construct a spatial representation whose neighbourhoods have methodological meaning.</p>

<h2 id="why-tabular-data-remains-the-difficult-domain">Why tabular data remains the difficult domain</h2>

<p>Deep learning on tabular data is not impossible. There are many neural architectures for structured data, including MLPs, attention-based models, entity embeddings, differentiable trees and transformer variants for tables. However, the empirical picture remains complex. In many benchmarks, strong ensemble models still outperform standard neural networks.</p>

<p>There are several reasons for this.</p>

<p>First, tabular datasets are often small or medium-sized. Deep neural networks usually benefit from large-scale data, while many tabular problems contain hundreds, thousands or tens of thousands of samples rather than millions.</p>

<p>Second, tabular features are heterogeneous. Some are continuous, others categorical, ordinal, binary or derived. Their scales and distributions may differ substantially.</p>

<p>Third, interactions between variables can be sparse, non-linear and dataset-specific. A variable may be informative only in combination with another variable, or only for a subset of the population.</p>

<p>Fourth, tabular data have no canonical spatial arrangement. Unlike images, tables do not tell us which variables should be neighbours.</p>

<p>This fourth point is especially relevant for the synthetic image paradigm. If a CNN is to process a tabular sample as an image, the image must not be an arbitrary reshaping of the table. It must be a constructed representation in which spatial proximity has methodological meaning.</p>

<p><img src="/images/Blog/2026-06-02-03-last-unconquered-castle.png" alt="Deep learning and tabular data as an open problem" />
<em>(Figure 3. Deep learning for tabular data as an open research problem. Although deep neural networks have achieved remarkable success in computer vision, natural language processing and generative AI, tabular data remain a challenging domain where ensemble methods are still strong baselines. This motivates the search for alternative representations rather than naive applications of generic neural architectures.)</em></p>

<h2 id="the-central-problem-is-not-the-model-it-is-the-representation">The central problem is not the model; it is the representation</h2>

<p>A frequent mistake is to treat model selection and data representation as independent decisions. In reality, architecture and representation are deeply coupled.</p>

<p>A CNN is not simply a classifier. It is a classifier designed for spatially organized data. A ViT is not simply an attention mechanism. It assumes a patch-based visual input. A recurrent neural network assumes a sequence. A graph neural network assumes a graph.</p>

<p>Therefore, when applying deep learning to tabular data, we must ask what structure the model is expected to exploit. If no structure is provided, the model must infer everything from scratch. If an arbitrary structure is imposed, the model may learn artifacts.</p>

<p>Synthetic image generation is a representation strategy. It proposes that instead of forcing a neural network to process a raw table, we first map the table into a spatial domain. Then we can use visual architectures in a more coherent way.</p>

<p>The resulting image is not natural. It is synthetic. It does not represent a physical scene. It represents the values of a tabular instance arranged according to a spatial encoding of the variables.</p>

<h2 id="from-tabular-vectors-to-synthetic-images">From tabular vectors to synthetic images</h2>

<p>The transformation can be understood in two stages.</p>

<p>First, the method learns or defines a spatial layout of the features. Each feature is assigned a position in a two-dimensional grid. Ideally, features that are statistically, geometrically or semantically related should be placed close to one another.</p>

<p>Second, each sample is projected into that grid. The feature values of the sample become pixel intensities or spatial patterns, producing a synthetic image.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tabular dataset
    |
    | learn feature layout
    v
2D feature map
    |
    | project each sample
    v
Synthetic image dataset
    |
    | CNN / ViT / hybrid neural network
    v
Prediction and explanation
</code></pre></div></div>

<p>This transformation does not claim that tabular data are images. Rather, it constructs an image-like representation that allows the use of architectures developed for the visual domain.</p>

<p>The methodological quality of the approach depends heavily on how the feature layout is constructed. A good transformation should reduce arbitrariness. A poor transformation may simply reproduce the arbitrary ordering of the original table.</p>

<h2 id="a-necessary-distinction-spatially-informed-methods-vs-order-dependent-methods">A necessary distinction: spatially informed methods vs. order-dependent methods</h2>

<p>This distinction is crucial.</p>

<p>Some tabular-to-image methods are strongly influenced by the original order or structure of the table. Examples include <strong>BarGraph</strong>, <strong>DistanceMatrix</strong>, <strong>Combination</strong>, <strong>SuperTML</strong>, <strong>BIE</strong> and <strong>FeatureWrap</strong>. These methods may be useful as baselines or didactic examples, but they should be used with caution as primary transformation strategies when the feature order is arbitrary.</p>

<p>The reason is methodological. If the generated image depends on whether <code class="language-plaintext highlighter-rouge">age</code> appears before or after <code class="language-plaintext highlighter-rouge">sex</code>, then the transformation inherits the same limitation that motivated the problem in the first place: tabular data do not possess a natural spatial order. In that case, the synthetic image may encode artifacts of the column arrangement rather than meaningful relationships between variables.</p>

<p>This does not mean that these methods are never useful. They can be relevant when the input table has a meaningful pre-existing order, when the objective is educational, or when they are included as comparative baselines. However, for rigorous tabular-to-image modelling, they should not be treated as the preferred family of methods if the feature ordering is arbitrary.</p>

<p>In contrast, methods such as <strong>TINTO</strong>, <strong>DeepInsight</strong>, <strong>IGTD</strong>, <strong>REFINED</strong>, <strong>Fotomics</strong> and recent unsupervised learning-based approaches such as <strong>ILUSTRE/ILUSTRES</strong> aim to construct the spatial representation from the data structure itself. These methods attempt to reduce dependence on the original column order by learning or optimizing the spatial arrangement of features. Their goal is precisely to create a meaningful visual representation where the geometry reflects relationships in the data, not the accidental ordering of the spreadsheet.</p>

<p>This distinction should be made explicit in any serious discussion of synthetic images for tabular data. The key question is not only whether a method produces an image. The key question is whether the image has a defensible spatial structure.</p>

<h2 id="the-paradigm-shift">The paradigm shift</h2>

<p>The paradigm shift introduced by TINTOlib can therefore be understood as a representational shift. Instead of applying deep learning directly to unordered tabular vectors, the method first constructs a spatial representation where feature relationships can be expressed geometrically. Once this representation exists, computer vision architectures can be applied under assumptions that are more coherent with their original design.</p>

<p>This does not mean that synthetic images are universally superior to classical tabular models. Rather, it means that they create a new experimental space: one in which tabular data can be studied through visual, hybrid and explainable neural architectures.</p>

<p>From a teaching perspective, this paradigm is also useful because it makes the problem visible. Students can compare different spatial encodings, inspect the resulting images and observe how representation affects the behaviour of the model.</p>

<h2 id="what-part-ii-will-cover">What Part II will cover</h2>

<p>This first part has focused on the theoretical motivation: why tabular data remain difficult for deep learning, why representation matters, and why spatially meaningful synthetic images are different from arbitrary reshaping.</p>

<p>In the second part, we will move from the conceptual problem to the modelling pipeline. We will discuss how TINTOlib operationalizes this paradigm, how different transformation methods should be compared, how hybrid neural networks combine tabular and visual branches, and how visual explainability methods can be adapted to synthetic tabular images.</p>

<p><a href="/blog/2026/06/04-from-synthetic-images-to-hybrid-neural-networks/">Continue with Part II: From Synthetic Images to Hybrid Neural Networks</a></p>

<h2 id="references-and-related-publications">References and related publications</h2>

<p>The concepts presented in this tutorial are connected to the following research and software publications on TINTO, TINTOlib, tabular-to-image transformation, synthetic spatial representations, hybrid neural networks, indoor localisation and explainable artificial intelligence.</p>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Synthetic Images" /><category term="Tabular-to-Image" /><category term="Tabular Data" /><category term="Deep Learning" /><category term="Computer Vision" /><category term="Spatial Encoding" /><category term="Machine Learning" /><category term="Data Science" /><summary type="html"><![CDATA[Part I of a theoretical and technical series on why deep learning still struggles with tabular data, and why synthetic image representations provide a promising bridge between structured data and computer vision architectures.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-06-02-03-improving-deep-learning-exploiting-synthetic-images.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-06-02-03-improving-deep-learning-exploiting-synthetic-images.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">What is TINTOlib and why should we transform tabular data into synthetic images?</title><link href="https://www.manuelcastillo.eu/blog/2026/05/02-what-is-it-tintolib-synthetic-images/" rel="alternate" type="text/html" title="What is TINTOlib and why should we transform tabular data into synthetic images?" /><published>2026-05-28T00:00:00+02:00</published><updated>2026-05-28T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/05/02-what-is-it-tintolib-synthetic-images</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/05/02-what-is-it-tintolib-synthetic-images/"><![CDATA[<link rel="canonical" href="https://www.manuelcastillo.eu/blog/2026/05/02-what-is-it-tintolib-synthetic-images/" />

<meta name="robots" content="index,follow,max-image-preview:large" />

<meta name="description" content="An introduction to TINTOlib: why tabular data requires spatial encoding, how to generate synthetic images avoiding data leakage, and a complete end-to-end CNN pipeline in PyTorch." />

<meta property="og:type" content="article" />

<meta property="og:title" content="What is TINTOlib and why should we transform tabular data into synthetic images?" />

<meta property="og:description" content="An introduction to TINTOlib: why tabular data requires spatial encoding, how to generate synthetic images avoiding data leakage, and a complete end-to-end CNN pipeline in PyTorch." />

<meta property="og:url" content="https://www.manuelcastillo.eu/blog/2026/05/02-what-is-it-tintolib-synthetic-images/" />

<meta property="og:image" content="https://www.manuelcastillo.eu/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png" />

<meta property="article:published_time" content="2026-05-28T00:00:00+02:00" />

<meta property="article:modified_time" content="2026-05-28T00:00:00+02:00" />

<meta property="article:author" content="Manuel Castillo-Cara" />

<meta property="article:section" content="TINTOlib" />

<meta property="article:tag" content="TINTOlib" />

<meta property="article:tag" content="Tabular Data" />

<meta property="article:tag" content="Synthetic Images" />

<meta property="article:tag" content="Deep Learning" />

<meta property="article:tag" content="CNN" />

<meta property="article:tag" content="PyTorch" />

<meta property="article:tag" content="Python" />

<meta property="article:tag" content="Blurring" />

<meta property="article:tag" content="Tabular-to-Image" />

<meta name="twitter:card" content="summary_large_image" />

<meta name="twitter:title" content="What is TINTOlib and why should we transform tabular data into synthetic images?" />

<meta name="twitter:description" content="An introduction to TINTOlib: why tabular data requires spatial encoding, how to generate synthetic images avoiding data leakage, and a complete end-to-end CNN pipeline in PyTorch." />

<meta name="twitter:image" content="https://www.manuelcastillo.eu/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png" />

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "What is TINTOlib and why should we transform tabular data into synthetic images?",
  "description": "An introduction to TINTOlib: why tabular data requires spatial encoding, how to generate synthetic images avoiding data leakage, and a complete end-to-end CNN pipeline in PyTorch.",
  "image": "https://www.manuelcastillo.eu/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png",
  "author": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "publisher": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "datePublished": "2026-05-28T00:00:00+02:00",
  "dateModified": "2026-05-28T00:00:00+02:00",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://www.manuelcastillo.eu/blog/2026/05/02-what-is-it-tintolib-synthetic-images/"
  },
  "articleSection": "TINTOlib",
  "keywords": "TINTOlib, Tabular Data, Synthetic Images, Deep Learning, CNN, PyTorch, Python, Blurring, Tabular-to-Image"
}
</script>

<div style="background: linear-gradient(135deg, #1a237e 0%, #4a148c 50%, #311b92 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #b39ddb; font-weight: 600;">TINTOlib · Synthetic Images · Tabular-to-Image</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">What is TINTOlib?</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #e1d5f5; line-height: 1.55;">Why does tabular data need spatial encoding? How are synthetic images generated — and what does blurring do? A complete introduction with a first end-to-end CNN pipeline in PyTorch.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">TINTOlib</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">Synthetic Images</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">Blurring</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">Tabular-to-Image</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">Deep Learning</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 260px; width: 100%;">
    <img src="/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png" alt="TINTOlib synthetic images from tabular data" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<blockquote>
  <blockquote>
    <ul>
      <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
      <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
      <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
      <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
    </ul>
  </blockquote>
</blockquote>

<hr />

<!-- ======== TINTOlib: Overview Videos (ES/EN) ======== -->
<section id="tintolib-overview-videos" style="margin: 1.75rem 0 2rem;">
  <h2 style="margin: 0 0 0.5rem;">TINTOlib overview videos</h2>
    <p style="margin: 0 0 1rem; line-height: 1.6;">
      The following short videos provide a bilingual introduction to <strong>TINTOlib</strong>, explaining how tabular data can be transformed into synthetic images and processed with computer vision architectures such as CNNs, Vision Transformers and hybrid neural networks.
    </p>
      <div class="tintolib-video-toggle" role="tablist" aria-label="Select video language">
    <button type="button" class="tintolib-video-btn active" data-target="#tintolib-video-es" role="tab" aria-selected="true">
      Español
    </button>
    <button type="button" class="tintolib-video-btn" data-target="#tintolib-video-en" role="tab" aria-selected="false">
      English
    </button>
  </div>
    <div class="tintolib-video-wrap">
    <video id="tintolib-video-es" class="tintolib-video-panel active" controls="" controlsList="nodownload" preload="metadata" playsinline="" aria-label="TINTOlib overview video in Spanish">
      <source src="/video/TINTOlib-video-Es.mp4" type="video/mp4" />
      Your browser does not support the video tag.
      <a href="/video/TINTOlib-video-Es.mp4">Open the Spanish video</a>.
    </video>
    <video id="tintolib-video-en" class="tintolib-video-panel" controls="" controlsList="nodownload" preload="metadata" playsinline="" aria-label="TINTOlib overview video in English">
  <source src="/video/TINTOlib-video-En.mp4" type="video/mp4" />
  Your browser does not support the video tag.
  <a href="/video/TINTOlib-video-En.mp4">Open the English video</a>.
  </video>
  </div>
</section>
<style>
  #tintolib-overview-videos .tintolib-video-toggle {
    display: flex;
    gap: 0.5rem;
    flex-wrap: wrap;
    margin: 0.75rem 0 1rem;
  }

  #tintolib-overview-videos .tintolib-video-btn {
    background: #eef2ff;
    border: 1px solid #dbe3ff;
    color: #1f2937;
    font-weight: 800;
    border-radius: 999px;
    padding: 0.35rem 0.8rem;
    cursor: pointer;
  }

  #tintolib-overview-videos .tintolib-video-btn.active {
    background: #2563eb;
    color: #fff;
    border-color: #2563eb;
  }

  #tintolib-overview-videos .tintolib-video-wrap {
    position: relative;
    width: 100%;
    max-width: 900px;
    margin: 0 auto;
  }

  #tintolib-overview-videos .tintolib-video-panel {
    display: none;
    width: 100%;
    aspect-ratio: 16 / 9;
    object-fit: cover;
    border: 1px solid #d0d7de;
    border-radius: 12px;
    box-shadow: 0 2px 8px rgba(0,0,0,.08);
    background: #000;
  }

  #tintolib-overview-videos .tintolib-video-panel.active {
    display: block;
  }
</style>

<script>
  document.addEventListener('DOMContentLoaded', function () {
    const container = document.getElementById('tintolib-overview-videos');
    if (!container) return;

    const buttons = container.querySelectorAll('.tintolib-video-btn');
    const panels = container.querySelectorAll('.tintolib-video-panel');

    buttons.forEach(function (button) {
      button.addEventListener('click', function () {
        const target = button.getAttribute('data-target');

        buttons.forEach(function (btn) {
          btn.classList.remove('active');
          btn.setAttribute('aria-selected', 'false');
        });

        button.classList.add('active');
        button.setAttribute('aria-selected', 'true');

        panels.forEach(function (panel) {
          if ('#' + panel.id === target) {
            panel.classList.add('active');
          } else {
            if (panel.tagName.toLowerCase() === 'video') {
              try { panel.pause(); } catch (e) {}
            }
            panel.classList.remove('active');
          }
        });
      });
    });
  });
</script>

<p>In many applied machine learning problems, there is a recurrent practical distinction: for images, text, or audio, we often use Deep Learning; for tabular data, tree-based models and ensembles such as Random Forest, XGBoost, LightGBM, or CatBoost remain extremely competitive.</p>

<p>This distinction is not accidental. Convolutional neural networks were designed to exploit spatial structure: local neighborhoods, edges, textures, shapes, and patterns that repeat across an image. A tabular dataset, however, does not naturally have this type of geometry. The fact that one variable appears in column 2 and another in column 3 does not imply that both variables are semantically or statistically close.</p>

<p>This leads to a relevant research question:</p>

<blockquote>
  <p>Can we transform each tabular instance into a synthetic image so that computer vision architectures can exploit relationships between variables?</p>
</blockquote>

<p>This question motivates the field of tabular-to-image transformation, also referred to as <em>tabular2image</em>, <em>spatial encoding for tabular data</em>, or synthetic image generation from tabular data. In this post, we introduce the main idea, explain where TINTOlib fits, and build a simple convolutional neural network in PyTorch to classify synthetic images generated from tabular data.</p>

<h2 id="the-problem-tabular-data-has-no-natural-spatial-locality">The problem: tabular data has no natural spatial locality</h2>

<p>A digital image can be represented as a matrix of pixels. In a natural image, nearby pixels usually belong to the same visual region: an edge, a texture, a shadow, or an object. This property allows CNNs to apply local filters and learn reusable spatial patterns.</p>

<p>A tabular instance is different. It is usually represented as a vector:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>x = [age, blood_pressure, cholesterol, glucose, ...]
</code></pre></div></div>

<p>The order of the columns is often arbitrary. If two variables are swapped, the semantic meaning of the sample does not necessarily change. For a CNN, however, that change would modify the input geometry. This is one of the reasons why applying convolutions directly to tabular vectors is usually problematic: the model would assume a local neighborhood structure that is not explicitly present.</p>

<p>Tabular-to-image transformation addresses this limitation by constructing an artificial spatial layout. The idea is to place the original variables on a 2D grid so that related variables are positioned close to each other. Then, for each row in the dataset, the values of those variables are projected onto the grid, producing a synthetic image.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tabular data                    Synthetic image

+--------+--------+--------+       +----+----+----+----+
| feat_1 | feat_2 | feat_3 |  --&gt;  |    | f2 |    | f8 |
| feat_4 | feat_5 | feat_6 |       +----+----+----+----+
|  ...   |  ...   |  ...   |       | f1 |    | f5 |    |
+--------+--------+--------+       +----+----+----+----+
                                   |    | f3 | f4 |    |
                                   +----+----+----+----+
</code></pre></div></div>

<p><em>(Conceptual schematic of the transformation from tabular data to a synthetic 2D image. Each feature is mapped to a grid position such that related variables are placed close to each other.)</em></p>

<p>This image is not a natural image. It does not represent a real-world scene. It is a spatial representation of a tabular vector. The important point is not whether the image is visually meaningful to a human observer, but whether the representation encodes useful relationships for a vision-based model.</p>

<p><img src="/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png" alt="Tabular Data into Synthetic Images Methodology" />
<em>(Figure 1. Conceptual workflow of TINTOlib for transforming tabular data into synthetic images. The original tabular features are spatially encoded into a two-dimensional grid, producing image-like representations that preserve feature relationships and can be processed by computer vision models such as convolutional neural networks.)</em></p>

<h2 id="why-transform-tabular-data-into-images">Why transform tabular data into images?</h2>

<p>The transformation of tabular data into synthetic images opens at least three relevant possibilities.</p>

<p>First, it allows us to use computer vision architectures on structured data. Once each tabular instance has been transformed into an image, we can use CNNs, Vision Transformers, pretrained backbones, or hybrid neural architectures.</p>

<p>Second, it introduces a spatial inductive bias. If the transformation method places related variables close to each other, convolutional filters can learn local interactions between features.</p>

<p>Third, it enables visual explainability techniques. Methods such as saliency maps, activation maps, or Grad-CAM can be adapted to study which regions of the synthetic image — and therefore which original variables — contributed most to the prediction.</p>

<p>This does not mean that tabular-to-image transformation will always outperform classical machine learning models. Tree-based models remain strong baselines for tabular data. The value of this approach depends on the dataset, the number of samples, the number of features, the transformation method, the neural architecture, and the evaluation protocol. Its main interest is that it provides an alternative representation that can be combined with modern vision-based deep learning methods.</p>

<h2 id="what-is-tintolib">What is TINTOlib?</h2>

<p>TINTOlib is a Python library for transforming tabular data into synthetic images in a systematic, modular, and reproducible way. Its main goal is to provide a unified interface for different state-of-the-art tabular-to-image transformation methods that were previously scattered across independent implementations, often with heterogeneous APIs.</p>

<p>The library follows a Scikit-Learn-like design, including methods such as <code class="language-plaintext highlighter-rouge">fit</code>, <code class="language-plaintext highlighter-rouge">transform</code>, and <code class="language-plaintext highlighter-rouge">fit_transform</code>. This is particularly useful when designing machine learning pipelines, because it allows us to separate the learning of the spatial representation from the transformation of new data.</p>

<p>TINTOlib includes both parametric and non-parametric methods. Some examples are:</p>

<ul>
  <li><strong>TINTO</strong>, based on dimensionality reduction techniques such as PCA or t-SNE, with optional image blurring.</li>
  <li><strong>IGTD</strong>, which optimizes the feature arrangement to preserve similarity relationships.</li>
  <li><strong>REFINED</strong>, which relies on multidimensional scaling and optimization to preserve feature-neighborhood information.</li>
  <li><strong>DeepInsight</strong>, another projection-based method that arranges features in a 2D space.</li>
  <li><strong>BarGraph</strong>, <strong>DistanceMatrix</strong>, <strong>Combination</strong>, <strong>FeatureWrap</strong>, <strong>SuperTML</strong>, and <strong>BIE</strong>, among others.</li>
</ul>

<p>The documentation is available at <strong><a href="https://tintolib.readthedocs.io/">tintolib.readthedocs.io</a></strong>.<br />
The source code and examples are available at <strong><a href="https://github.com/oeg-upm/TINTOlib">github.com/oeg-upm/TINTOlib</a></strong>.</p>

<p>In practice, TINTOlib allows us to move from this representation:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>samples x features
</code></pre></div></div>

<p>to this one:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>samples x channels x height x width
</code></pre></div></div>

<p>which is the natural input format for computer vision models in PyTorch.</p>

<h2 id="avoiding-data-leakage-fit-only-on-the-training-data">Avoiding data leakage: fit only on the training data</h2>

<p>A critical point when using tabular-to-image methods is data leakage.</p>

<p>The spatial arrangement of the variables must be learned only from the training data. If we use the full dataset to learn the transformation — including validation or test samples — information from the evaluation split can indirectly influence the representation. This would lead to an optimistic and methodologically incorrect estimate of model performance.</p>

<p>Therefore, even though TINTOlib provides <code class="language-plaintext highlighter-rouge">fit_transform</code> for convenience, in a proper experimental pipeline we should use:</p>

<ol>
  <li><code class="language-plaintext highlighter-rouge">fit</code> on the training set only;</li>
  <li><code class="language-plaintext highlighter-rouge">transform</code> on the training set;</li>
  <li><code class="language-plaintext highlighter-rouge">transform</code> on the validation and test sets using the already-fitted transformation.</li>
</ol>

<p>Conceptually, the workflow should be:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Train tabular data  ---- fit ----&gt; learned spatial layout
Train tabular data  -- transform -&gt; train images
Validation data     -- transform -&gt; validation images
Test data           -- transform -&gt; test images
</code></pre></div></div>

<p>This is the same principle used with scalers, imputers, PCA, feature selectors, and other preprocessing methods in standard machine learning pipelines.</p>

<h2 id="first-practical-example-generating-synthetic-images-with-tintolib">First practical example: generating synthetic images with TINTOlib</h2>

<p>For this example, we consider a multiclass classification problem using the Wine dataset from Scikit-Learn. Each row represents a sample, the input columns are numerical features, and the target column identifies the class label.</p>

<p>Install TINTOlib with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>pip <span class="nb">install </span>TINTOlib
</code></pre></div></div>

<p>Then, we prepare the train, validation, and test splits before fitting the tabular-to-image transformation.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">pathlib</span> <span class="kn">import</span> <span class="n">Path</span>

<span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_wine</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>
<span class="kn">from</span> <span class="nn">sklearn.preprocessing</span> <span class="kn">import</span> <span class="n">LabelEncoder</span>

<span class="kn">from</span> <span class="nn">TINTOlib.tinto</span> <span class="kn">import</span> <span class="n">TINTO</span>

<span class="c1"># Reproducibility
</span><span class="n">seed</span> <span class="o">=</span> <span class="mi">42</span>

<span class="c1"># Load multiclass tabular dataset
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_wine</span><span class="p">()</span>

<span class="c1"># Build dataframe
</span><span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span><span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span> <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span><span class="p">)</span>
<span class="n">df</span><span class="p">[</span><span class="s">"target"</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span>

<span class="c1"># Separate features and target
</span><span class="n">target_col</span> <span class="o">=</span> <span class="s">"target"</span>
<span class="n">X</span> <span class="o">=</span> <span class="n">df</span><span class="p">.</span><span class="n">drop</span><span class="p">(</span><span class="n">columns</span><span class="o">=</span><span class="p">[</span><span class="n">target_col</span><span class="p">])</span>
<span class="n">y</span> <span class="o">=</span> <span class="n">df</span><span class="p">[</span><span class="n">target_col</span><span class="p">]</span>

<span class="c1"># Encode labels if needed
</span><span class="n">label_encoder</span> <span class="o">=</span> <span class="n">LabelEncoder</span><span class="p">()</span>
<span class="n">y_encoded</span> <span class="o">=</span> <span class="n">label_encoder</span><span class="p">.</span><span class="n">fit_transform</span><span class="p">(</span><span class="n">y</span><span class="p">)</span>

<span class="c1"># First split: train + temporary set
</span><span class="n">X_train</span><span class="p">,</span> <span class="n">X_tmp</span><span class="p">,</span> <span class="n">y_train</span><span class="p">,</span> <span class="n">y_tmp</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">X</span><span class="p">,</span>
    <span class="n">y_encoded</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.30</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="n">seed</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">y_encoded</span>
<span class="p">)</span>

<span class="c1"># Second split: validation + test
</span><span class="n">X_val</span><span class="p">,</span> <span class="n">X_test</span><span class="p">,</span> <span class="n">y_val</span><span class="p">,</span> <span class="n">y_test</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span>
    <span class="n">X_tmp</span><span class="p">,</span>
    <span class="n">y_tmp</span><span class="p">,</span>
    <span class="n">test_size</span><span class="o">=</span><span class="mf">0.50</span><span class="p">,</span>
    <span class="n">random_state</span><span class="o">=</span><span class="n">seed</span><span class="p">,</span>
    <span class="n">stratify</span><span class="o">=</span><span class="n">y_tmp</span>
<span class="p">)</span>

<span class="c1"># Rebuild dataframes because TINTOlib expects the target column together with the features
</span><span class="n">train_df</span> <span class="o">=</span> <span class="n">X_train</span><span class="p">.</span><span class="n">copy</span><span class="p">()</span>
<span class="n">train_df</span><span class="p">[</span><span class="n">target_col</span><span class="p">]</span> <span class="o">=</span> <span class="n">y_train</span>

<span class="n">val_df</span> <span class="o">=</span> <span class="n">X_val</span><span class="p">.</span><span class="n">copy</span><span class="p">()</span>
<span class="n">val_df</span><span class="p">[</span><span class="n">target_col</span><span class="p">]</span> <span class="o">=</span> <span class="n">y_val</span>

<span class="n">test_df</span> <span class="o">=</span> <span class="n">X_test</span><span class="p">.</span><span class="n">copy</span><span class="p">()</span>
<span class="n">test_df</span><span class="p">[</span><span class="n">target_col</span><span class="p">]</span> <span class="o">=</span> <span class="n">y_test</span>
</code></pre></div></div>

<p>Now we instantiate the TINTO transformation. In this example we use the TINTO method, but the same structure can be used with other TINTOlib methods such as IGTD, REFINED, DeepInsight, BarGraph, DistanceMatrix, SuperTML, or BIE.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Output folders
</span><span class="n">output_root</span> <span class="o">=</span> <span class="n">Path</span><span class="p">(</span><span class="s">"tinto_images"</span><span class="p">)</span>
<span class="n">train_folder</span> <span class="o">=</span> <span class="n">output_root</span> <span class="o">/</span> <span class="s">"train"</span>
<span class="n">val_folder</span> <span class="o">=</span> <span class="n">output_root</span> <span class="o">/</span> <span class="s">"val"</span>
<span class="n">test_folder</span> <span class="o">=</span> <span class="n">output_root</span> <span class="o">/</span> <span class="s">"test"</span>

<span class="c1"># TINTO model
# pixels defines the image size: pixels x pixels
</span><span class="n">image_model</span> <span class="o">=</span> <span class="n">TINTO</span><span class="p">(</span>
    <span class="n">problem</span><span class="o">=</span><span class="s">"supervised"</span><span class="p">,</span>
    <span class="n">algorithm</span><span class="o">=</span><span class="s">"PCA"</span><span class="p">,</span>
    <span class="n">pixels</span><span class="o">=</span><span class="mi">20</span><span class="p">,</span>
    <span class="n">blur</span><span class="o">=</span><span class="bp">True</span><span class="p">,</span>
    <span class="n">random_seed</span><span class="o">=</span><span class="n">seed</span>
<span class="p">)</span>

<span class="c1"># Learn the spatial layout ONLY from the training data
</span><span class="n">image_model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>

<span class="c1"># Transform each split using the same fitted representation
</span><span class="n">image_model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">train_df</span><span class="p">,</span> <span class="n">folder</span><span class="o">=</span><span class="nb">str</span><span class="p">(</span><span class="n">train_folder</span><span class="p">))</span>
<span class="n">image_model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">val_df</span><span class="p">,</span> <span class="n">folder</span><span class="o">=</span><span class="nb">str</span><span class="p">(</span><span class="n">val_folder</span><span class="p">))</span>
<span class="n">image_model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">test_df</span><span class="p">,</span> <span class="n">folder</span><span class="o">=</span><span class="nb">str</span><span class="p">(</span><span class="n">test_folder</span><span class="p">))</span>

<span class="k">print</span><span class="p">(</span><span class="s">"Synthetic images generated successfully."</span><span class="p">)</span>
</code></pre></div></div>

<p>This separation is essential. The validation and test sets are transformed using the spatial layout learned from the training data, but they do not participate in learning that layout.</p>

<div style="display: flex; gap: 0.75rem; justify-content: center; flex-wrap: wrap; margin: 1.5rem 0 0.5rem;">
  <img src="/images/Blog/synthetic_images/2026-05-28-02_TINTO1-class1.png" alt="Synthetic image generated by TINTOlib TINTO with blurring for class 1" style="width: 120px; height: 120px; object-fit: contain; border: 1px solid #e2e8f0; border-radius: 4px; background: #f8fafc;" />
  <img src="/images/Blog/synthetic_images/2026-05-28-02_TINTO1-class2.png" alt="Synthetic image generated by TINTOlib TINTO with blurring for class 2" style="width: 120px; height: 120px; object-fit: contain; border: 1px solid #e2e8f0; border-radius: 4px; background: #f8fafc;" />
  <img src="/images/Blog/synthetic_images/2026-05-28-02_TINTO1-class3.png" alt="Synthetic image generated by TINTOlib TINTO with blurring for class 3" style="width: 120px; height: 120px; object-fit: contain; border: 1px solid #e2e8f0; border-radius: 4px; background: #f8fafc;" />
</div>
<p><em>(Figure 2. Synthetic image samples generated with TINTOlib using the TINTO method with blurring, showing one representative instance from each class of the Wine multiclass dataset. Each image corresponds to a different class and encodes the original tabular feature values into a two-dimensional spatial representation, where local smoothing enhances spatial continuity while preserving class-dependent patterns that can be exploited by CNN-based and hybrid deep learning models.)</em></p>

<h3 id="can-we-use-another-method-instead-of-tinto">Can we use another method instead of TINTO?</h3>

<p>Yes. One of the main advantages of TINTOlib is that the same general workflow can be reused with different transformation methods. For example, depending on the method available in your installation, you could replace the import and model definition with another transformer:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Example: using another TINTOlib method instead of TINTO
# from TINTOlib.igtd import IGTD
# image_model = IGTD(problem="supervised", pixels=20)
</span>
<span class="c1"># from TINTOlib.refined import REFINED
# image_model = REFINED(problem="supervised", pixels=20)
</span></code></pre></div></div>

<p>The high-level logic remains the same:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">image_model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">train_df</span><span class="p">)</span>
<span class="n">image_model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">train_df</span><span class="p">,</span> <span class="n">folder</span><span class="o">=</span><span class="s">"..."</span><span class="p">)</span>
<span class="n">image_model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">val_df</span><span class="p">,</span> <span class="n">folder</span><span class="o">=</span><span class="s">"..."</span><span class="p">)</span>
<span class="n">image_model</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">test_df</span><span class="p">,</span> <span class="n">folder</span><span class="o">=</span><span class="s">"..."</span><span class="p">)</span>
</code></pre></div></div>

<p>For an experimental paper or benchmark, this is particularly useful because it allows us to compare different spatial encodings while keeping the same downstream neural architecture.</p>

<h2 id="loading-the-generated-images-in-pytorch">Loading the generated images in PyTorch</h2>

<p>Once the images have been generated, we can load them in PyTorch. The exact folder structure may depend on the selected TINTOlib method and configuration. For a simple classification pipeline, it is convenient to organize the images using the structure expected by <code class="language-plaintext highlighter-rouge">torchvision.datasets.ImageFolder</code>:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>tinto_images/
├── train/
│   ├── class_0/
│   ├── class_1/
│   └── class_2/
├── val/
│   ├── class_0/
│   ├── class_1/
│   └── class_2/
└── test/
    ├── class_0/
    ├── class_1/
    └── class_2/
</code></pre></div></div>

<p>If your generated files are stored differently, you can either reorganize them into this structure or implement a custom PyTorch <code class="language-plaintext highlighter-rouge">Dataset</code>.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">torch</span>
<span class="kn">from</span> <span class="nn">torch.utils.data</span> <span class="kn">import</span> <span class="n">DataLoader</span>
<span class="kn">from</span> <span class="nn">torchvision</span> <span class="kn">import</span> <span class="n">datasets</span><span class="p">,</span> <span class="n">transforms</span>

<span class="n">batch_size</span> <span class="o">=</span> <span class="mi">32</span>
<span class="n">img_size</span> <span class="o">=</span> <span class="mi">20</span>

<span class="n">transform</span> <span class="o">=</span> <span class="n">transforms</span><span class="p">.</span><span class="n">Compose</span><span class="p">([</span>
    <span class="n">transforms</span><span class="p">.</span><span class="n">Grayscale</span><span class="p">(</span><span class="n">num_output_channels</span><span class="o">=</span><span class="mi">1</span><span class="p">),</span>
    <span class="n">transforms</span><span class="p">.</span><span class="n">Resize</span><span class="p">((</span><span class="n">img_size</span><span class="p">,</span> <span class="n">img_size</span><span class="p">)),</span>
    <span class="n">transforms</span><span class="p">.</span><span class="n">ToTensor</span><span class="p">(),</span>
<span class="p">])</span>

<span class="n">train_dataset</span> <span class="o">=</span> <span class="n">datasets</span><span class="p">.</span><span class="n">ImageFolder</span><span class="p">(</span><span class="n">root</span><span class="o">=</span><span class="n">train_folder</span><span class="p">,</span> <span class="n">transform</span><span class="o">=</span><span class="n">transform</span><span class="p">)</span>
<span class="n">val_dataset</span> <span class="o">=</span> <span class="n">datasets</span><span class="p">.</span><span class="n">ImageFolder</span><span class="p">(</span><span class="n">root</span><span class="o">=</span><span class="n">val_folder</span><span class="p">,</span> <span class="n">transform</span><span class="o">=</span><span class="n">transform</span><span class="p">)</span>
<span class="n">test_dataset</span> <span class="o">=</span> <span class="n">datasets</span><span class="p">.</span><span class="n">ImageFolder</span><span class="p">(</span><span class="n">root</span><span class="o">=</span><span class="n">test_folder</span><span class="p">,</span> <span class="n">transform</span><span class="o">=</span><span class="n">transform</span><span class="p">)</span>

<span class="n">num_classes</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">train_dataset</span><span class="p">.</span><span class="n">classes</span><span class="p">)</span>

<span class="n">train_loader</span> <span class="o">=</span> <span class="n">DataLoader</span><span class="p">(</span>
    <span class="n">train_dataset</span><span class="p">,</span>
    <span class="n">batch_size</span><span class="o">=</span><span class="n">batch_size</span><span class="p">,</span>
    <span class="n">shuffle</span><span class="o">=</span><span class="bp">True</span><span class="p">,</span>
    <span class="n">num_workers</span><span class="o">=</span><span class="mi">2</span>
<span class="p">)</span>

<span class="n">val_loader</span> <span class="o">=</span> <span class="n">DataLoader</span><span class="p">(</span>
    <span class="n">val_dataset</span><span class="p">,</span>
    <span class="n">batch_size</span><span class="o">=</span><span class="n">batch_size</span><span class="p">,</span>
    <span class="n">shuffle</span><span class="o">=</span><span class="bp">False</span><span class="p">,</span>
    <span class="n">num_workers</span><span class="o">=</span><span class="mi">2</span>
<span class="p">)</span>

<span class="n">test_loader</span> <span class="o">=</span> <span class="n">DataLoader</span><span class="p">(</span>
    <span class="n">test_dataset</span><span class="p">,</span>
    <span class="n">batch_size</span><span class="o">=</span><span class="n">batch_size</span><span class="p">,</span>
    <span class="n">shuffle</span><span class="o">=</span><span class="bp">False</span><span class="p">,</span>
    <span class="n">num_workers</span><span class="o">=</span><span class="mi">2</span>
<span class="p">)</span>

<span class="k">print</span><span class="p">(</span><span class="s">"Classes:"</span><span class="p">,</span> <span class="n">train_dataset</span><span class="p">.</span><span class="n">classes</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="s">"Number of classes:"</span><span class="p">,</span> <span class="n">num_classes</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="s">"Training images:"</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="n">train_dataset</span><span class="p">))</span>
<span class="k">print</span><span class="p">(</span><span class="s">"Validation images:"</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="n">val_dataset</span><span class="p">))</span>
<span class="k">print</span><span class="p">(</span><span class="s">"Test images:"</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="n">test_dataset</span><span class="p">))</span>
</code></pre></div></div>

<h2 id="a-simple-cnn-in-pytorch">A simple CNN in PyTorch</h2>

<div style="background: #f8fafc; border-left: 4px solid #4a148c; padding: 1rem 1.25rem; margin: 1.5rem 0; border-radius: 6px;">
  <strong>Note on the neural architecture.</strong>
  The convolutional neural network used in this tutorial is intentionally simple and is not optimized for the Wine dataset. Its purpose is to provide a clear and reproducible baseline showing how synthetic images generated with TINTOlib can be connected to a PyTorch classification pipeline. Students are encouraged to modify the architecture, tune the hyperparameters, and compare alternative designs to improve predictive performance.
</div>

<p>The following network defines a compact CNN baseline for verifying that the synthetic images generated by TINTOlib can be loaded, processed, and classified within a standard PyTorch workflow.</p>

<p>We assume grayscale images of size 20 x 20 pixels.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">torch</span>
<span class="kn">import</span> <span class="nn">torch.nn</span> <span class="k">as</span> <span class="n">nn</span>


<span class="k">class</span> <span class="nc">SimpleTINTOCNN</span><span class="p">(</span><span class="n">nn</span><span class="p">.</span><span class="n">Module</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">num_classes</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">img_size</span><span class="p">:</span> <span class="nb">int</span> <span class="o">=</span> <span class="mi">20</span><span class="p">):</span>
        <span class="nb">super</span><span class="p">().</span><span class="n">__init__</span><span class="p">()</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">features</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Sequential</span><span class="p">(</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">Conv2d</span><span class="p">(</span><span class="n">in_channels</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span> <span class="n">out_channels</span><span class="o">=</span><span class="mi">32</span><span class="p">,</span> <span class="n">kernel_size</span><span class="o">=</span><span class="mi">3</span><span class="p">,</span> <span class="n">padding</span><span class="o">=</span><span class="mi">1</span><span class="p">),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">ReLU</span><span class="p">(),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">MaxPool2d</span><span class="p">(</span><span class="n">kernel_size</span><span class="o">=</span><span class="mi">2</span><span class="p">),</span>

            <span class="n">nn</span><span class="p">.</span><span class="n">Conv2d</span><span class="p">(</span><span class="n">in_channels</span><span class="o">=</span><span class="mi">32</span><span class="p">,</span> <span class="n">out_channels</span><span class="o">=</span><span class="mi">64</span><span class="p">,</span> <span class="n">kernel_size</span><span class="o">=</span><span class="mi">3</span><span class="p">,</span> <span class="n">padding</span><span class="o">=</span><span class="mi">1</span><span class="p">),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">ReLU</span><span class="p">(),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">MaxPool2d</span><span class="p">(</span><span class="n">kernel_size</span><span class="o">=</span><span class="mi">2</span><span class="p">),</span>
        <span class="p">)</span>

        <span class="c1"># For img_size=20: 20 -&gt; 10 -&gt; 5 after two MaxPool2d layers
</span>        <span class="n">reduced_size</span> <span class="o">=</span> <span class="n">img_size</span> <span class="o">//</span> <span class="mi">4</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">classifier</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Sequential</span><span class="p">(</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">Flatten</span><span class="p">(),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="mi">64</span> <span class="o">*</span> <span class="n">reduced_size</span> <span class="o">*</span> <span class="n">reduced_size</span><span class="p">,</span> <span class="mi">128</span><span class="p">),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">ReLU</span><span class="p">(),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">Dropout</span><span class="p">(</span><span class="n">p</span><span class="o">=</span><span class="mf">0.3</span><span class="p">),</span>
            <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="mi">128</span><span class="p">,</span> <span class="n">num_classes</span><span class="p">)</span>
        <span class="p">)</span>

    <span class="k">def</span> <span class="nf">forward</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">):</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">features</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">classifier</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">x</span>


<span class="n">device</span> <span class="o">=</span> <span class="n">torch</span><span class="p">.</span><span class="n">device</span><span class="p">(</span><span class="s">"cuda"</span> <span class="k">if</span> <span class="n">torch</span><span class="p">.</span><span class="n">cuda</span><span class="p">.</span><span class="n">is_available</span><span class="p">()</span> <span class="k">else</span> <span class="s">"cpu"</span><span class="p">)</span>

<span class="n">model</span> <span class="o">=</span> <span class="n">SimpleTINTOCNN</span><span class="p">(</span><span class="n">num_classes</span><span class="o">=</span><span class="n">num_classes</span><span class="p">,</span> <span class="n">img_size</span><span class="o">=</span><span class="n">img_size</span><span class="p">).</span><span class="n">to</span><span class="p">(</span><span class="n">device</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="n">model</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="training-the-model">Training the model</h2>

<p>For multiclass classification, we use <code class="language-plaintext highlighter-rouge">CrossEntropyLoss</code>. In PyTorch, this loss expects raw logits, so the final layer should not include a <code class="language-plaintext highlighter-rouge">softmax</code> activation.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">torch.optim</span> <span class="k">as</span> <span class="n">optim</span>

<span class="n">criterion</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">CrossEntropyLoss</span><span class="p">()</span>
<span class="n">optimizer</span> <span class="o">=</span> <span class="n">optim</span><span class="p">.</span><span class="n">Adam</span><span class="p">(</span><span class="n">model</span><span class="p">.</span><span class="n">parameters</span><span class="p">(),</span> <span class="n">lr</span><span class="o">=</span><span class="mf">1e-3</span><span class="p">)</span>


<span class="k">def</span> <span class="nf">train_one_epoch</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="n">dataloader</span><span class="p">,</span> <span class="n">criterion</span><span class="p">,</span> <span class="n">optimizer</span><span class="p">,</span> <span class="n">device</span><span class="p">):</span>
    <span class="n">model</span><span class="p">.</span><span class="n">train</span><span class="p">()</span>
    <span class="n">running_loss</span> <span class="o">=</span> <span class="mf">0.0</span>
    <span class="n">correct</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="n">total</span> <span class="o">=</span> <span class="mi">0</span>

    <span class="k">for</span> <span class="n">images</span><span class="p">,</span> <span class="n">labels</span> <span class="ow">in</span> <span class="n">dataloader</span><span class="p">:</span>
        <span class="n">images</span> <span class="o">=</span> <span class="n">images</span><span class="p">.</span><span class="n">to</span><span class="p">(</span><span class="n">device</span><span class="p">)</span>
        <span class="n">labels</span> <span class="o">=</span> <span class="n">labels</span><span class="p">.</span><span class="n">to</span><span class="p">(</span><span class="n">device</span><span class="p">)</span>

        <span class="n">optimizer</span><span class="p">.</span><span class="n">zero_grad</span><span class="p">()</span>
        <span class="n">outputs</span> <span class="o">=</span> <span class="n">model</span><span class="p">(</span><span class="n">images</span><span class="p">)</span>
        <span class="n">loss</span> <span class="o">=</span> <span class="n">criterion</span><span class="p">(</span><span class="n">outputs</span><span class="p">,</span> <span class="n">labels</span><span class="p">)</span>
        <span class="n">loss</span><span class="p">.</span><span class="n">backward</span><span class="p">()</span>
        <span class="n">optimizer</span><span class="p">.</span><span class="n">step</span><span class="p">()</span>

        <span class="n">running_loss</span> <span class="o">+=</span> <span class="n">loss</span><span class="p">.</span><span class="n">item</span><span class="p">()</span> <span class="o">*</span> <span class="n">images</span><span class="p">.</span><span class="n">size</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>
        <span class="n">predictions</span> <span class="o">=</span> <span class="n">outputs</span><span class="p">.</span><span class="n">argmax</span><span class="p">(</span><span class="n">dim</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
        <span class="n">correct</span> <span class="o">+=</span> <span class="p">(</span><span class="n">predictions</span> <span class="o">==</span> <span class="n">labels</span><span class="p">).</span><span class="nb">sum</span><span class="p">().</span><span class="n">item</span><span class="p">()</span>
        <span class="n">total</span> <span class="o">+=</span> <span class="n">labels</span><span class="p">.</span><span class="n">size</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>

    <span class="n">epoch_loss</span> <span class="o">=</span> <span class="n">running_loss</span> <span class="o">/</span> <span class="n">total</span>
    <span class="n">epoch_acc</span> <span class="o">=</span> <span class="n">correct</span> <span class="o">/</span> <span class="n">total</span>

    <span class="k">return</span> <span class="n">epoch_loss</span><span class="p">,</span> <span class="n">epoch_acc</span>


<span class="o">@</span><span class="n">torch</span><span class="p">.</span><span class="n">no_grad</span><span class="p">()</span>
<span class="k">def</span> <span class="nf">evaluate</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="n">dataloader</span><span class="p">,</span> <span class="n">criterion</span><span class="p">,</span> <span class="n">device</span><span class="p">):</span>
    <span class="n">model</span><span class="p">.</span><span class="nb">eval</span><span class="p">()</span>
    <span class="n">running_loss</span> <span class="o">=</span> <span class="mf">0.0</span>
    <span class="n">correct</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="n">total</span> <span class="o">=</span> <span class="mi">0</span>

    <span class="k">for</span> <span class="n">images</span><span class="p">,</span> <span class="n">labels</span> <span class="ow">in</span> <span class="n">dataloader</span><span class="p">:</span>
        <span class="n">images</span> <span class="o">=</span> <span class="n">images</span><span class="p">.</span><span class="n">to</span><span class="p">(</span><span class="n">device</span><span class="p">)</span>
        <span class="n">labels</span> <span class="o">=</span> <span class="n">labels</span><span class="p">.</span><span class="n">to</span><span class="p">(</span><span class="n">device</span><span class="p">)</span>

        <span class="n">outputs</span> <span class="o">=</span> <span class="n">model</span><span class="p">(</span><span class="n">images</span><span class="p">)</span>
        <span class="n">loss</span> <span class="o">=</span> <span class="n">criterion</span><span class="p">(</span><span class="n">outputs</span><span class="p">,</span> <span class="n">labels</span><span class="p">)</span>

        <span class="n">running_loss</span> <span class="o">+=</span> <span class="n">loss</span><span class="p">.</span><span class="n">item</span><span class="p">()</span> <span class="o">*</span> <span class="n">images</span><span class="p">.</span><span class="n">size</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>
        <span class="n">predictions</span> <span class="o">=</span> <span class="n">outputs</span><span class="p">.</span><span class="n">argmax</span><span class="p">(</span><span class="n">dim</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
        <span class="n">correct</span> <span class="o">+=</span> <span class="p">(</span><span class="n">predictions</span> <span class="o">==</span> <span class="n">labels</span><span class="p">).</span><span class="nb">sum</span><span class="p">().</span><span class="n">item</span><span class="p">()</span>
        <span class="n">total</span> <span class="o">+=</span> <span class="n">labels</span><span class="p">.</span><span class="n">size</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>

    <span class="n">epoch_loss</span> <span class="o">=</span> <span class="n">running_loss</span> <span class="o">/</span> <span class="n">total</span>
    <span class="n">epoch_acc</span> <span class="o">=</span> <span class="n">correct</span> <span class="o">/</span> <span class="n">total</span>

    <span class="k">return</span> <span class="n">epoch_loss</span><span class="p">,</span> <span class="n">epoch_acc</span>
</code></pre></div></div>

<p>Now we train the network.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">num_epochs</span> <span class="o">=</span> <span class="mi">20</span>

<span class="n">history</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"train_loss"</span><span class="p">:</span> <span class="p">[],</span>
    <span class="s">"train_acc"</span><span class="p">:</span> <span class="p">[],</span>
    <span class="s">"val_loss"</span><span class="p">:</span> <span class="p">[],</span>
    <span class="s">"val_acc"</span><span class="p">:</span> <span class="p">[],</span>
<span class="p">}</span>

<span class="k">for</span> <span class="n">epoch</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">num_epochs</span><span class="p">):</span>
    <span class="n">train_loss</span><span class="p">,</span> <span class="n">train_acc</span> <span class="o">=</span> <span class="n">train_one_epoch</span><span class="p">(</span>
        <span class="n">model</span><span class="p">,</span>
        <span class="n">train_loader</span><span class="p">,</span>
        <span class="n">criterion</span><span class="p">,</span>
        <span class="n">optimizer</span><span class="p">,</span>
        <span class="n">device</span>
    <span class="p">)</span>

    <span class="n">val_loss</span><span class="p">,</span> <span class="n">val_acc</span> <span class="o">=</span> <span class="n">evaluate</span><span class="p">(</span>
        <span class="n">model</span><span class="p">,</span>
        <span class="n">val_loader</span><span class="p">,</span>
        <span class="n">criterion</span><span class="p">,</span>
        <span class="n">device</span>
    <span class="p">)</span>

    <span class="n">history</span><span class="p">[</span><span class="s">"train_loss"</span><span class="p">].</span><span class="n">append</span><span class="p">(</span><span class="n">train_loss</span><span class="p">)</span>
    <span class="n">history</span><span class="p">[</span><span class="s">"train_acc"</span><span class="p">].</span><span class="n">append</span><span class="p">(</span><span class="n">train_acc</span><span class="p">)</span>
    <span class="n">history</span><span class="p">[</span><span class="s">"val_loss"</span><span class="p">].</span><span class="n">append</span><span class="p">(</span><span class="n">val_loss</span><span class="p">)</span>
    <span class="n">history</span><span class="p">[</span><span class="s">"val_acc"</span><span class="p">].</span><span class="n">append</span><span class="p">(</span><span class="n">val_acc</span><span class="p">)</span>

    <span class="k">print</span><span class="p">(</span>
        <span class="sa">f</span><span class="s">"Epoch [</span><span class="si">{</span><span class="n">epoch</span> <span class="o">+</span> <span class="mi">1</span><span class="si">:</span><span class="mi">02</span><span class="n">d</span><span class="si">}</span><span class="s">/</span><span class="si">{</span><span class="n">num_epochs</span><span class="si">}</span><span class="s">] "</span>
        <span class="sa">f</span><span class="s">"Train Loss: </span><span class="si">{</span><span class="n">train_loss</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s"> | Train Acc: </span><span class="si">{</span><span class="n">train_acc</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s"> | "</span>
        <span class="sa">f</span><span class="s">"Val Loss: </span><span class="si">{</span><span class="n">val_loss</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s"> | Val Acc: </span><span class="si">{</span><span class="n">val_acc</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s">"</span>
    <span class="p">)</span>
</code></pre></div></div>

<h2 id="evaluating-on-the-test-set">Evaluating on the test set</h2>

<p>The test set should only be used once the model selection process has finished. Here we report the final test performance using the model selected during validation.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">test_loss</span><span class="p">,</span> <span class="n">test_acc</span> <span class="o">=</span> <span class="n">evaluate</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="n">test_loader</span><span class="p">,</span> <span class="n">criterion</span><span class="p">,</span> <span class="n">device</span><span class="p">)</span>

<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Test Loss: </span><span class="si">{</span><span class="n">test_loss</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Test Accuracy: </span><span class="si">{</span><span class="n">test_acc</span><span class="si">:</span><span class="p">.</span><span class="mi">4</span><span class="n">f</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="visualizing-the-training-curves">Visualizing the training curves</h2>

<p>In a Jupyter notebook, it is useful to visualize the learning curves to check whether the model is learning and whether overfitting appears.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">matplotlib.pyplot</span> <span class="k">as</span> <span class="n">plt</span>

<span class="n">plt</span><span class="p">.</span><span class="n">figure</span><span class="p">(</span><span class="n">figsize</span><span class="o">=</span><span class="p">(</span><span class="mi">7</span><span class="p">,</span> <span class="mi">4</span><span class="p">))</span>
<span class="n">plt</span><span class="p">.</span><span class="n">plot</span><span class="p">(</span><span class="n">history</span><span class="p">[</span><span class="s">"train_loss"</span><span class="p">],</span> <span class="n">label</span><span class="o">=</span><span class="s">"Train loss"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">plot</span><span class="p">(</span><span class="n">history</span><span class="p">[</span><span class="s">"val_loss"</span><span class="p">],</span> <span class="n">label</span><span class="o">=</span><span class="s">"Validation loss"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">xlabel</span><span class="p">(</span><span class="s">"Epoch"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">ylabel</span><span class="p">(</span><span class="s">"Loss"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">title</span><span class="p">(</span><span class="s">"Training and validation loss"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">legend</span><span class="p">()</span>
<span class="n">plt</span><span class="p">.</span><span class="n">grid</span><span class="p">(</span><span class="bp">True</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">show</span><span class="p">()</span>

<span class="n">plt</span><span class="p">.</span><span class="n">figure</span><span class="p">(</span><span class="n">figsize</span><span class="o">=</span><span class="p">(</span><span class="mi">7</span><span class="p">,</span> <span class="mi">4</span><span class="p">))</span>
<span class="n">plt</span><span class="p">.</span><span class="n">plot</span><span class="p">(</span><span class="n">history</span><span class="p">[</span><span class="s">"train_acc"</span><span class="p">],</span> <span class="n">label</span><span class="o">=</span><span class="s">"Train accuracy"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">plot</span><span class="p">(</span><span class="n">history</span><span class="p">[</span><span class="s">"val_acc"</span><span class="p">],</span> <span class="n">label</span><span class="o">=</span><span class="s">"Validation accuracy"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">xlabel</span><span class="p">(</span><span class="s">"Epoch"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">ylabel</span><span class="p">(</span><span class="s">"Accuracy"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">title</span><span class="p">(</span><span class="s">"Training and validation accuracy"</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">legend</span><span class="p">()</span>
<span class="n">plt</span><span class="p">.</span><span class="n">grid</span><span class="p">(</span><span class="bp">True</span><span class="p">)</span>
<span class="n">plt</span><span class="p">.</span><span class="n">show</span><span class="p">()</span>
</code></pre></div></div>

<h2 id="visualizing-synthetic-images">Visualizing synthetic images</h2>

<p>It is also useful to inspect some generated images. This helps to emphasize that these are not natural images, but artificial spatial encodings of tabular samples.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">images</span><span class="p">,</span> <span class="n">labels</span> <span class="o">=</span> <span class="nb">next</span><span class="p">(</span><span class="nb">iter</span><span class="p">(</span><span class="n">train_loader</span><span class="p">))</span>

<span class="n">plt</span><span class="p">.</span><span class="n">figure</span><span class="p">(</span><span class="n">figsize</span><span class="o">=</span><span class="p">(</span><span class="mi">10</span><span class="p">,</span> <span class="mi">4</span><span class="p">))</span>
<span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="nb">min</span><span class="p">(</span><span class="mi">8</span><span class="p">,</span> <span class="n">images</span><span class="p">.</span><span class="n">size</span><span class="p">(</span><span class="mi">0</span><span class="p">))):</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">subplot</span><span class="p">(</span><span class="mi">2</span><span class="p">,</span> <span class="mi">4</span><span class="p">,</span> <span class="n">i</span> <span class="o">+</span> <span class="mi">1</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">imshow</span><span class="p">(</span><span class="n">images</span><span class="p">[</span><span class="n">i</span><span class="p">].</span><span class="n">squeeze</span><span class="p">(</span><span class="mi">0</span><span class="p">),</span> <span class="n">cmap</span><span class="o">=</span><span class="s">"gray"</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">title</span><span class="p">(</span><span class="sa">f</span><span class="s">"Class: </span><span class="si">{</span><span class="n">labels</span><span class="p">[</span><span class="n">i</span><span class="p">].</span><span class="n">item</span><span class="p">()</span><span class="si">}</span><span class="s">"</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">axis</span><span class="p">(</span><span class="s">"off"</span><span class="p">)</span>

<span class="n">plt</span><span class="p">.</span><span class="n">tight_layout</span><span class="p">()</span>
<span class="n">plt</span><span class="p">.</span><span class="n">show</span><span class="p">()</span>
</code></pre></div></div>

<p><img src="/images/Blog/synthetic_images/2026-05-28-02_TINTO-final.png" alt="Examples of TINTO synthetic images" />
<em>(Figure 3. Visualization of a batch of synthetic images generated with TINTOlib using the TINTO method with blurring. Each panel represents an individual tabular sample from the Wine dataset, encoded as a grayscale two-dimensional image and labeled according to its class. The observed spatial intensity patterns illustrate how different classes may produce distinguishable synthetic representations that can be processed by CNN-based models.)</em></p>

<h2 id="what-should-we-compare-next">What should we compare next?</h2>

<p>This first experiment trains a simple CNN, but a rigorous evaluation should include additional baselines and ablations:</p>

<ul>
  <li>a classical machine learning baseline, such as Random Forest, XGBoost, LightGBM, or CatBoost;</li>
  <li>a multilayer perceptron trained on the original tabular data;</li>
  <li>different tabular-to-image transformations, such as TINTO, IGTD, REFINED, DeepInsight, and SuperTML;</li>
  <li>different image sizes;</li>
  <li>deeper CNNs or Vision Transformers;</li>
  <li>hybrid architectures combining a tabular branch and an image branch.</li>
</ul>

<p>The main question is not only whether a CNN can outperform a tree-based model. The scientifically relevant question is when, why, and under which conditions a spatial representation of tabular data is beneficial.</p>

<h2 id="conclusion">Conclusion</h2>

<p>TINTOlib makes it easier to experiment with a powerful idea: transforming tabular data into visual representations that can be processed by computer vision architectures. This transformation does not automatically make a tabular problem easier, but it provides a different representation where spatial inductive biases can be exploited.</p>

<p>The key element is the spatial arrangement of the features. If related variables are placed close to each other, CNN filters can learn local interactions that are not directly available in the original table. In addition, this representation enables hybrid architectures, Vision Transformers, and visual explainability methods for structured data.</p>

<p>In this post, we introduced the motivation behind tabular-to-image transformation, the role of TINTOlib, the importance of avoiding data leakage, and a first CNN implementation in PyTorch. In future posts, we will compare different TINTOlib methods, build hybrid tabular-image neural networks, and apply explainability techniques to recover the relevance of the original variables.</p>

<h2 id="references-and-related-publications">References and related publications</h2>

<p>The concepts presented in this tutorial are connected to the following research and software publications on TINTO, TINTOlib, tabular-to-image transformation, synthetic spatial representations, hybrid neural networks, and indoor localisation.</p>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Tabular Data" /><category term="Synthetic Images" /><category term="Deep Learning" /><category term="CNN" /><category term="PyTorch" /><category term="Python" /><category term="Blurring" /><category term="Tabular-to-Image" /><summary type="html"><![CDATA[An introduction to TINTOlib: why tabular data requires spatial encoding, how to generate synthetic images avoiding data leakage, and a complete end-to-end CNN pipeline in PyTorch.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-05-28-02-what-is-it-tintolib-synthetic-images.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Introduction to TINTOlib: Unlocking the Power of Vision Architectures for Tabular Data</title><link href="https://www.manuelcastillo.eu/blog/2026/05/01-introduction-to-tintolib-tabular-to-image/" rel="alternate" type="text/html" title="Introduction to TINTOlib: Unlocking the Power of Vision Architectures for Tabular Data" /><published>2026-05-27T00:00:00+02:00</published><updated>2026-05-27T00:00:00+02:00</updated><id>https://www.manuelcastillo.eu/blog/2026/05/01-introduction-to-tintolib-tabular-to-image</id><content type="html" xml:base="https://www.manuelcastillo.eu/blog/2026/05/01-introduction-to-tintolib-tabular-to-image/"><![CDATA[<link rel="canonical" href="https://www.manuelcastillo.eu/blog/2026/05/01-introduction-to-tintolib-tabular-to-image/" />

<meta name="robots" content="index,follow,max-image-preview:large" />

<meta name="description" content="Technical introduction to TINTOlib, a Python framework for transforming tabular data into synthetic images and applying CNN-based deep learning architectures." />

<meta property="og:type" content="article" />

<meta property="og:title" content="Introduction to TINTOlib: Unlocking the Power of Vision Architectures for Tabular Data" />

<meta property="og:description" content="Technical introduction to TINTOlib, a Python framework for transforming tabular data into synthetic images and applying CNN-based deep learning architectures." />

<meta property="og:url" content="https://www.manuelcastillo.eu/blog/2026/05/01-introduction-to-tintolib-tabular-to-image/" />

<meta property="og:image" content="https://www.manuelcastillo.eu/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png" />

<meta property="article:published_time" content="2026-05-27T00:00:00+02:00" />

<meta property="article:modified_time" content="2026-05-27T00:00:00+02:00" />

<meta property="article:author" content="Manuel Castillo-Cara" />

<meta property="article:section" content="TINTOlib" />

<meta property="article:tag" content="TINTOlib" />

<meta property="article:tag" content="Tabular-to-Image" />

<meta property="article:tag" content="Synthetic Images" />

<meta property="article:tag" content="Deep Learning" />

<meta property="article:tag" content="CNN" />

<meta property="article:tag" content="PyTorch" />

<meta property="article:tag" content="Machine Learning" />

<meta name="twitter:card" content="summary_large_image" />

<meta name="twitter:title" content="Introduction to TINTOlib: Unlocking the Power of Vision Architectures for Tabular Data" />

<meta name="twitter:description" content="Technical introduction to TINTOlib, a Python framework for transforming tabular data into synthetic images and applying CNN-based deep learning architectures." />

<meta name="twitter:image" content="https://www.manuelcastillo.eu/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png" />

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "Introduction to TINTOlib: Unlocking the Power of Vision Architectures for Tabular Data",
  "description": "Technical introduction to TINTOlib, a Python framework for transforming tabular data into synthetic images and applying CNN-based deep learning architectures.",
  "image": "https://www.manuelcastillo.eu/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png",
  "author": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "publisher": {
    "@type": "Person",
    "name": "Manuel Castillo-Cara",
    "url": "https://www.manuelcastillo.eu/"
  },
  "datePublished": "2026-05-27T00:00:00+02:00",
  "dateModified": "2026-05-27T00:00:00+02:00",
  "mainEntityOfPage": {
    "@type": "WebPage",
    "@id": "https://www.manuelcastillo.eu/blog/2026/05/01-introduction-to-tintolib-tabular-to-image/"
  },
  "articleSection": "TINTOlib",
  "keywords": "TINTOlib, Tabular-to-Image, Synthetic Images, Deep Learning, CNN, PyTorch, Machine Learning"
}
</script>

<div style="background: linear-gradient(135deg, #1a237e 0%, #4a148c 50%, #311b92 100%); border-radius: 12px; padding: 2.5rem 2rem; margin: 1.5rem 0 2.5rem; display: flex; flex-wrap: wrap; align-items: center; gap: 2rem; color: #fff;">
  <div style="flex: 1 1 280px; min-width: 0;">
    <p style="margin: 0 0 0.4rem; font-size: 0.78rem; letter-spacing: 0.12em; text-transform: uppercase; color: #b39ddb; font-weight: 600;">TINTOlib · Deep Learning · Tabular-to-Image</p>
    <h1 style="margin: 0 0 0.75rem; font-size: clamp(1.5rem, 4vw, 2.1rem); font-weight: 800; line-height: 1.2; color: #fff;">Introduction to TINTOlib</h1>
    <p style="margin: 0 0 1rem; font-size: 0.97rem; color: #e1d5f5; line-height: 1.55;">A Python framework for transforming tabular data into synthetic images and applying CNN-based vision architectures — bridging the gap between structured data and deep learning.</p>
    <div style="display: flex; flex-wrap: wrap; gap: 0.5rem;">
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">PyTorch</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">CNN</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">Tabular Data</span>
      <span style="background: rgba(255,255,255,0.15); border-radius: 20px; padding: 0.25rem 0.75rem; font-size: 0.78rem; color: #e8d5ff;">Synthetic Images</span>
    </div>
  </div>
  <div style="flex: 0 0 auto; max-width: 260px; width: 100%;">
    <img src="/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png" alt="TINTOlib tabular-to-image transformation" style="width: 100%; border-radius: 10px; box-shadow: 0 8px 32px rgba(0,0,0,0.45); display: block;" />
  </div>
</div>

<hr />

<blockquote>
  <blockquote>
    <ul>
      <li><strong>Author:</strong> Manuel Castillo-Cara, PhD</li>
      <li><strong>Affiliation:</strong> Dpt. of Artificial Intelligence, Universidad Nacional de Educación a Distancia (UNED), Spain</li>
      <li><strong>Role:</strong> Researcher, Professor, and TINTOlib Python Library Developer</li>
      <li><strong>License:</strong> <a href="https://creativecommons.org/licenses/by-nc/4.0/">CC BY-NC 4.0</a> unless otherwise stated.</li>
    </ul>
  </blockquote>
</blockquote>

<hr />

<!-- ======== TINTOlib: Overview Videos (ES/EN) ======== -->
<section id="tintolib-overview-videos" style="margin: 1.75rem 0 2rem;">
  <h2 style="margin: 0 0 0.5rem;">TINTOlib overview videos</h2>
    <p style="margin: 0 0 1rem; line-height: 1.6;">
      The following short videos provide a bilingual introduction to <strong>TINTOlib</strong>, explaining how tabular data can be transformed into synthetic images and processed with computer vision architectures such as CNNs, Vision Transformers and hybrid neural networks.
    </p>
      <div class="tintolib-video-toggle" role="tablist" aria-label="Select video language">
    <button type="button" class="tintolib-video-btn active" data-target="#tintolib-video-es" role="tab" aria-selected="true">
      Español
    </button>
    <button type="button" class="tintolib-video-btn" data-target="#tintolib-video-en" role="tab" aria-selected="false">
      English
    </button>
  </div>
    <div class="tintolib-video-wrap">
    <video id="tintolib-video-es" class="tintolib-video-panel active" controls="" controlsList="nodownload" preload="metadata" playsinline="" aria-label="TINTOlib overview video in Spanish">
      <source src="/video/TINTOlib-video-Es.mp4" type="video/mp4" />
      Your browser does not support the video tag.
      <a href="/video/TINTOlib-video-Es.mp4">Open the Spanish video</a>.
    </video>
    <video id="tintolib-video-en" class="tintolib-video-panel" controls="" controlsList="nodownload" preload="metadata" playsinline="" aria-label="TINTOlib overview video in English">
  <source src="/video/TINTOlib-video-En.mp4" type="video/mp4" />
  Your browser does not support the video tag.
  <a href="/video/TINTOlib-video-En.mp4">Open the English video</a>.
  </video>
  </div>
</section>
<style>
  #tintolib-overview-videos .tintolib-video-toggle {
    display: flex;
    gap: 0.5rem;
    flex-wrap: wrap;
    margin: 0.75rem 0 1rem;
  }

  #tintolib-overview-videos .tintolib-video-btn {
    background: #eef2ff;
    border: 1px solid #dbe3ff;
    color: #1f2937;
    font-weight: 800;
    border-radius: 999px;
    padding: 0.35rem 0.8rem;
    cursor: pointer;
  }

  #tintolib-overview-videos .tintolib-video-btn.active {
    background: #2563eb;
    color: #fff;
    border-color: #2563eb;
  }

  #tintolib-overview-videos .tintolib-video-wrap {
    position: relative;
    width: 100%;
    max-width: 900px;
    margin: 0 auto;
  }

  #tintolib-overview-videos .tintolib-video-panel {
    display: none;
    width: 100%;
    aspect-ratio: 16 / 9;
    object-fit: cover;
    border: 1px solid #d0d7de;
    border-radius: 12px;
    box-shadow: 0 2px 8px rgba(0,0,0,.08);
    background: #000;
  }

  #tintolib-overview-videos .tintolib-video-panel.active {
    display: block;
  }
</style>

<script>
  document.addEventListener('DOMContentLoaded', function () {
    const container = document.getElementById('tintolib-overview-videos');
    if (!container) return;

    const buttons = container.querySelectorAll('.tintolib-video-btn');
    const panels = container.querySelectorAll('.tintolib-video-panel');

    buttons.forEach(function (button) {
      button.addEventListener('click', function () {
        const target = button.getAttribute('data-target');

        buttons.forEach(function (btn) {
          btn.classList.remove('active');
          btn.setAttribute('aria-selected', 'false');
        });

        button.classList.add('active');
        button.setAttribute('aria-selected', 'true');

        panels.forEach(function (panel) {
          if ('#' + panel.id === target) {
            panel.classList.add('active');
          } else {
            if (panel.tagName.toLowerCase() === 'video') {
              try { panel.pause(); } catch (e) {}
            }
            panel.classList.remove('active');
          }
        });
      });
    });
  });
</script>

<p>In contemporary Data Science, an established paradigm governs model selection: Deep Learning architectures dominate unstructured modalities such as computer vision and natural language processing, whereas gradient-boosted decision trees (GBDTs)—including <strong>XGBoost</strong>, <strong>LightGBM</strong>, and <strong>CatBoost</strong>—remain the gold standard for structured tabular datasets.</p>

<p>However, recent advancements in deep learning have challenged this dichotomy through the introduction of <strong>spatial encoding techniques</strong>. By transforming tabular features into synthetic multi-dimensional images, researchers can leverage the structural inductive biases of advanced computer vision networks, such as Convolutional Neural Networks (CNNs) and Vision Transformers (ViTs). This article provides a comprehensive theoretical and practical introduction to <strong>TINTOlib</strong>, the state-of-the-art Python library designed to streamline this transformation pipeline.</p>

<h2 id="the-theoretical-framework-why-map-tables-to-images">The Theoretical Framework: Why Map Tables to Images?</h2>

<p>The primary impediment to directly applying CNNs to tabular datasets is the <strong>absence of spatial locality</strong>. In natural images, adjacent pixels exhibit strong semantic and structural correlations (e.g., forming edges, textures, and continuous geometric shapes). Conversely, rows and columns in a standard tabular matrix possess an arbitrary ordering; swapping column 2 and column $d$ changes the array indices but preserves the underlying data semantics. This structural format violates the <strong>spatial inductive bias</strong>—specifically, translation invariance and locality—upon which convolutional filters rely.</p>

<p>To overcome this limitation, spatial encoding methodologies project the feature space onto a discrete 2D coordinate system. Features that exhibit strong statistical correlations or mutual dependencies are mapped to proximal spatial coordinates within a synthetic “canvas,” generating a <strong>synthetic pseudo-image</strong>.</p>

<p><img src="/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png" alt="Tabular Data into Synthetic Images Methodology" />
<em>(Figure 1: Conceptual diagram illustrating the topological mapping of tabular feature vectors into a structured 2D pixel grid via TINTOlib spatial encoding).</em></p>

<p>Through this transformation, the vision model’s convolutional kernels can extract higher-order hierarchical feature interactions. Furthermore, this paradigm shifts tabular analysis from black-box numeric mapping to a visual space, enabling the direct integration of post-hoc Explainable AI (XAI) frameworks—such as <strong>Grad-CAM</strong>, <strong>SHAP</strong>, or <strong>PermGrad</strong>—to visually interpret feature attributions via saliency maps.</p>

<h2 id="what-is-tintolib">What is TINTOlib?</h2>

<p><strong><a href="https://github.com/oeg-upm/TINTOlib">TINTOlib</a></strong> is an open-source Python framework that unifies a comprehensive suite of state-of-the-art tabular-to-image transformation algorithms under a single, cohesive, Scikit-Learn-compliant interface. For a comprehensive overview of the framework’s capabilities, consult the official <strong><a href="https://tintolib.readthedocs.io/en/latest/">TINTOlib Documentation</a></strong>.</p>

<p>Historically, evaluating different spatial encoding strategies required integrating disjointed, unstandardized repositories written across varying programming languages. TINTOlib resolves this fragmentation by categorizing and implementing both parametric and non-parametric approaches. While this tutorial focuses on the <strong>TINTO</strong> method (which utilizes manifold learning techniques like t-SNE or Principal Component Analysis to determine spatial feature positions), the library allows researchers to pivot to <strong>any other methodology</strong>—such as <strong>IGTD</strong>, <strong>REFINED</strong>, <strong>SuperTML</strong>, <strong>BarGraph</strong>, or <strong>Binary Image Encoding (BIE)</strong>—by modifying a single line of code, ensuring a seamless benchmarking experience.</p>

<h2 id="practical-implementation-building-your-first-pytorch-cnn-pipeline">Practical Implementation: Building Your First PyTorch CNN Pipeline</h2>

<p>To demonstrate the efficacy of this paradigm, we will construct an end-to-end classification pipeline. To ensure strict reproducibility, we will utilize the standard <em>Breast Cancer Wisconsin</em> dataset from Scikit-Learn.</p>

<h3 id="1-spatial-encoding-and-data-leakage-mitigation">1. Spatial Encoding and Data Leakage Mitigation</h3>

<p>A critical methodological vulnerability in spatial encoding is <strong>Data Leakage</strong>. Algorithms that learn the optimal spatial arrangement of pixels based on feature similarities (such as t-SNE, PCA, or distance-matrix optimizations) must <strong>never</strong> be exposed to the validation or testing partitions during the fitting phase. Doing so allows the topological properties of the unseen test data to influence the coordinate mapping, invalidating subsequent generalization metrics.</p>

<p>To ensure rigorous validation, the pipeline must strictly segregate data prior to mapping: call <code class="language-plaintext highlighter-rouge">.fit()</code> exclusively on the training partition to define the spatial configuration, and subsequently apply <code class="language-plaintext highlighter-rouge">.transform()</code> to generate the synthetic images for both sets independently.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="kn">from</span> <span class="nn">sklearn.datasets</span> <span class="kn">import</span> <span class="n">load_breast_cancer</span>
<span class="kn">from</span> <span class="nn">sklearn.model_selection</span> <span class="kn">import</span> <span class="n">train_test_split</span>
<span class="kn">from</span> <span class="nn">TINTOlib.tinto</span> <span class="kn">import</span> <span class="n">TINTO</span>

<span class="c1"># 1. Load the structured tabular dataset (Breast Cancer - 30 numeric features)
</span><span class="n">raw_data</span> <span class="o">=</span> <span class="n">load_breast_cancer</span><span class="p">()</span>
<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span><span class="n">raw_data</span><span class="p">.</span><span class="n">data</span><span class="p">,</span> <span class="n">columns</span><span class="o">=</span><span class="n">raw_data</span><span class="p">.</span><span class="n">feature_names</span><span class="p">)</span>
<span class="c1"># Append the target variable as the final column, conforming to tidy data standards
</span><span class="n">df</span><span class="p">[</span><span class="s">'target'</span><span class="p">]</span> <span class="o">=</span> <span class="n">raw_data</span><span class="p">.</span><span class="n">target</span> 

<span class="c1"># 2. Partition the dataset to guarantee strict validation boundaries
</span><span class="n">X_train</span><span class="p">,</span> <span class="n">X_test</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span><span class="n">df</span><span class="p">,</span> <span class="n">test_size</span><span class="o">=</span><span class="mf">0.2</span><span class="p">,</span> <span class="n">random_state</span><span class="o">=</span><span class="mi">42</span><span class="p">)</span>

<span class="c1"># 3. Instantiate the spatial encoder (TINTO via t-SNE optimization, outputting a 20x20 canvas)
# Note: To alternate methods, simply import and instantiate IGTD or REFINED here.
</span><span class="n">encoder</span> <span class="o">=</span> <span class="n">TINTO</span><span class="p">(</span><span class="n">problem</span><span class="o">=</span><span class="s">"supervised"</span><span class="p">,</span> <span class="n">algorithm</span><span class="o">=</span><span class="s">"t-SNE"</span><span class="p">,</span> <span class="n">pixels</span><span class="o">=</span><span class="mi">20</span><span class="p">,</span> <span class="n">blur</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>

<span class="c1"># 4. Fit the spatial coordinate mapping matrix ONLY using the training split
</span><span class="n">encoder</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">X_train</span><span class="p">)</span>

<span class="c1"># 5. Transform the tabular matrices into synthetic image repositories
</span><span class="n">encoder</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">X_train</span><span class="p">,</span> <span class="s">"synthetic_dataset/train/"</span><span class="p">)</span>
<span class="n">encoder</span><span class="p">.</span><span class="n">transform</span><span class="p">(</span><span class="n">X_test</span><span class="p">,</span> <span class="s">"synthetic_dataset/test/"</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="s">"Transformation completed successfully. Spatial representations isolated."</span><span class="p">)</span>
</code></pre></div></div>

<div style="display: flex; gap: 0.75rem; justify-content: center; flex-wrap: wrap; margin: 1.5rem 0 0.5rem;">
  <img src="/images/Blog/synthetic_images/2026-05-27-01_TINTO1.png" alt="Synthetic image 1 generated by TINTOlib TINTO with blurring" style="width: 120px; height: 120px; object-fit: contain; border: 1px solid #e2e8f0; border-radius: 4px; background: #f8fafc;" />
  <img src="/images/Blog/synthetic_images/2026-05-27-01_TINTO2.png" alt="Synthetic image 2 generated by TINTOlib TINTO with blurring" style="width: 120px; height: 120px; object-fit: contain; border: 1px solid #e2e8f0; border-radius: 4px; background: #f8fafc;" />
  <img src="/images/Blog/synthetic_images/2026-05-27-01_TINTO3.png" alt="Synthetic image 3 generated by TINTOlib TINTO with blurring" style="width: 120px; height: 120px; object-fit: contain; border: 1px solid #e2e8f0; border-radius: 4px; background: #f8fafc;" />
</div>
<p><em>(Figure 2. Synthetic image samples generated with TINTOlib using the TINTO method with blurring. Each image corresponds to an individual tabular instance from the Breast Cancer Wisconsin dataset and encodes its feature values into a two-dimensional spatial representation. The resulting intensity patterns can be processed by CNN-based and hybrid neural architectures.)</em></p>

<h3 id="2-architectural-specification-in-pytorch">2. Architectural Specification in PyTorch</h3>

<p>Following image generation, we construct a standard Convolutional Neural Network tailored to ingest the single-channel (grayscale) $20 \times 20$ pixel representations yielded by TINTOlib.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">torch</span>
<span class="kn">import</span> <span class="nn">torch.nn</span> <span class="k">as</span> <span class="n">nn</span>
<span class="kn">import</span> <span class="nn">torch.nn.functional</span> <span class="k">as</span> <span class="n">F</span>

<span class="k">class</span> <span class="nc">TabularCNN</span><span class="p">(</span><span class="n">nn</span><span class="p">.</span><span class="n">Module</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">num_classes</span><span class="o">=</span><span class="mi">2</span><span class="p">):</span>
        <span class="nb">super</span><span class="p">(</span><span class="n">TabularCNN</span><span class="p">,</span> <span class="bp">self</span><span class="p">).</span><span class="n">__init__</span><span class="p">()</span>
        
        <span class="c1"># Convolutional Block 1: Input channels = 1, Output feature maps = 32
</span>        <span class="bp">self</span><span class="p">.</span><span class="n">conv1</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Conv2d</span><span class="p">(</span><span class="n">in_channels</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span> <span class="n">out_channels</span><span class="o">=</span><span class="mi">32</span><span class="p">,</span> <span class="n">kernel_size</span><span class="o">=</span><span class="mi">3</span><span class="p">,</span> <span class="n">padding</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">pool1</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">MaxPool2d</span><span class="p">(</span><span class="n">kernel_size</span><span class="o">=</span><span class="mi">2</span><span class="p">,</span> <span class="n">stride</span><span class="o">=</span><span class="mi">2</span><span class="p">)</span>
        
        <span class="c1"># Convolutional Block 2: Input channels = 32, Output feature maps = 64
</span>        <span class="bp">self</span><span class="p">.</span><span class="n">conv2</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Conv2d</span><span class="p">(</span><span class="n">in_channels</span><span class="o">=</span><span class="mi">32</span><span class="p">,</span> <span class="n">out_channels</span><span class="o">=</span><span class="mi">64</span><span class="p">,</span> <span class="n">kernel_size</span><span class="o">=</span><span class="mi">3</span><span class="p">,</span> <span class="n">padding</span><span class="o">=</span><span class="mi">1</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">pool2</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">MaxPool2d</span><span class="p">(</span><span class="n">kernel_size</span><span class="o">=</span><span class="mi">2</span><span class="p">,</span> <span class="n">stride</span><span class="o">=</span><span class="mi">2</span><span class="p">)</span>
        
        <span class="c1"># Given a 20x20 input, two successive MaxPool reductions yield a 5x5 spatial size
</span>        <span class="bp">self</span><span class="p">.</span><span class="n">flatten</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Flatten</span><span class="p">()</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">fc1</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="mi">64</span> <span class="o">*</span> <span class="mi">5</span> <span class="o">*</span> <span class="mi">5</span><span class="p">,</span> <span class="mi">128</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">fc2</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="mi">128</span><span class="p">,</span> <span class="n">num_classes</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">forward</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">):</span>
        <span class="c1"># Block 1 forward pass
</span>        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">pool1</span><span class="p">(</span><span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">conv1</span><span class="p">(</span><span class="n">x</span><span class="p">)))</span>
        <span class="c1"># Block 2 forward pass
</span>        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">pool2</span><span class="p">(</span><span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">conv2</span><span class="p">(</span><span class="n">x</span><span class="p">)))</span>
        <span class="c1"># Classification head
</span>        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">flatten</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
        <span class="n">x</span> <span class="o">=</span> <span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">fc1</span><span class="p">(</span><span class="n">x</span><span class="p">))</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">fc2</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">x</span>

<span class="c1"># Instantiate the model architecture for binary classification
</span><span class="n">vision_model</span> <span class="o">=</span> <span class="n">TabularCNN</span><span class="p">(</span><span class="n">num_classes</span><span class="o">=</span><span class="mi">2</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="n">vision_model</span><span class="p">)</span>
</code></pre></div></div>

<p>The generated synthetic images stored in <code class="language-plaintext highlighter-rouge">synthetic_dataset/</code> can be seamlessly loaded via PyTorch’s standard <code class="language-plaintext highlighter-rouge">torchvision.datasets.ImageFolder</code> class combined with a <code class="language-plaintext highlighter-rouge">DataLoader</code> loop, optimizing models using typical criteria like <code class="language-plaintext highlighter-rouge">CrossEntropyLoss</code> or <code class="language-plaintext highlighter-rouge">BCEWithLogitsLoss</code>.</p>

<h2 id="conclusion-and-open-horizons">Conclusion and Open Horizons</h2>

<p>Transforming tabular features into synthetic spatial layouts offers a compelling methodology to bridge classical data problems with state-of-the-art visual architectures. Utilizing <strong>TINTOlib</strong> provides data scientists with a rigorous, reproducible, and standardized framework to systematically test, compare, and scale these transformations while avoiding common pitfalls such as data leakage.</p>

<p>In subsequent entries, we will delve deeper into benchmarking comparative analysis (e.g., non-parametric IGTD vs. parallelized REFINED), evaluating performance shifts when deploying Vision Transformers (ViTs), and rendering feature importance maps through advanced XAI methods.</p>

<h2 id="references-and-related-publications">References and related publications</h2>

<p>The concepts presented in this tutorial are connected to the following research and software publications on TINTO, TINTOlib, tabular-to-image transformation, synthetic spatial representations, hybrid neural networks, and indoor localisation.</p>

<h3 id="research-articles">Research articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro, Luis Orozco-Barbosa. <strong>Interpretable Hybrid Vision Transformer Architectures for MIMO-Based Indoor Localization using Synthetic Spatial Representations</strong>. <em>IEEE Internet of Things</em>. DOI: <a href="https://doi.org/10.1109/JIOT.2026.3696106">10.1109/JIOT.2026.3696106</a></p>
  </li>
  <li>
    <p>Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>A Comprehensive Benchmark of Spatial Encoding Methods for Tabular Data with Deep Neural Networks</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2025.104088">10.1016/j.inffus.2025.104088</a></p>
  </li>
  <li>
    <p>Giovanny Mondragon-Ruiz, Jiayun Liu, Manuel Castillo-Cara, Raúl García-Castro. <strong>Interpretable CNN–KAN hybrid architectures for tabular data with synthetic image encoding</strong>. <em>Information Processing and Management</em>. DOI: <a href="https://doi.org/10.1016/j.ipm.2026.104954">10.1016/j.ipm.2026.104954</a></p>
  </li>
  <li>
    <p>Felipe Escalera-González, Manuel Castillo-Cara, Mariano Rincón-Zamorano, Luis Orozco-Barbosa. <strong>PermGrad: Interpretable Hybrid Neural Networks with synthetic images for tabular data</strong>. <em>Knowledge-Based Systems</em>. DOI: <a href="https://doi.org/10.1016/j.knosys.2026.116507">10.1016/j.knosys.2026.116507</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Jesus Martínez-Gómez, Javier Ballesteros-Jerez, Ismael García-Varea, Raúl García-Castro, Luis Orozco-Barbosa. <strong>MIMO-Based Indoor Localisation with Hybrid Neural Networks</strong>. <em>IEEE Journal of Selected Topics in Signal Processing</em>. DOI: <a href="https://doi.org/10.1109/JSTSP.2025.3555067">10.1109/JSTSP.2025.3555067</a></p>
  </li>
  <li>
    <p>Reewos Talla-Chumpitaz, Manuel Castillo-Cara, Luis Orozco-Barbosa, Raúl García-Castro. <strong>Blurring Image Techniques for Bluetooth-based Indoor Localisation</strong>. <em>Information Fusion</em>. DOI: <a href="https://doi.org/10.1016/j.inffus.2022.10.011">10.1016/j.inffus.2022.10.011</a></p>
  </li>
</ol>

<h3 id="software-articles">Software articles</h3>

<ol>
  <li>
    <p>Jiayun Liu, David González-Fernández, Manuel Castillo-Cara, Raúl García-Castro. <strong>TINTOlib: A Python library for transforming tabular data into synthetic images for deep neural networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2025.102444">10.1016/j.softx.2025.102444</a></p>
  </li>
  <li>
    <p>Manuel Castillo-Cara, Reewos Talla-Chumpitaz, Raúl García-Castro, Luis Orozco-Barbosa. <strong>TINTO: Converting Tidy Data into Image for Classification with 2-Dimensional Convolutional Neural Networks</strong>. <em>SoftwareX</em>. DOI: <a href="https://doi.org/10.1016/j.softx.2023.101391">10.1016/j.softx.2023.101391</a></p>
  </li>
</ol>

<!-- ===== Blog Post Footer: CTA → Author → License → Export ===== -->
<style>
  /* Hide default Minimal Mistakes related posts (replaced by custom cards below) */
  .page__related { display: none !important; }

  /* ----- Copy-code button ----- */
  .page__content pre { position: relative; }
  .copy-code-btn {
    position: absolute;
    top: 0.35rem;
    right: 0.45rem;
    padding: 0.15rem 0.55rem;
    font-size: 0.72rem;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
    background: #eff6ff;
    color: #1d4ed8;
    border: 1px solid #bfdbfe;
    border-radius: 4px;
    cursor: pointer;
    transition: background 0.15s, color 0.15s;
    line-height: 1.5;
    z-index: 2;
    user-select: none;
    font-weight: 600;
  }
  .copy-code-btn:hover { background: #dbeafe; color: #1e40af; border-color: #93c5fd; }
  .copy-code-btn.copied { background: #d1fae5; color: #065f46; border-color: #6ee7b7; }

  /* ----- Post footer wrapper ----- */
  .blog-post-footer {
    margin-top: 3rem;
    border-top: 2px solid #e2e8f0;
    padding-top: 2rem;
  }

  /* ----- CTA (first) ----- */
  .blog-cta {
    background: linear-gradient(135deg, #1565c0 0%, #6d28d9 100%);
    color: #fff;
    border-radius: 12px;
    padding: 1.4rem 1.75rem;
    display: flex;
    flex-wrap: wrap;
    align-items: center;
    justify-content: space-between;
    gap: 1rem;
    margin-bottom: 1.5rem;
    box-shadow: 0 4px 18px rgba(21,101,192,0.22);
  }
  .blog-cta-text h3 { margin: 0 0 0.3rem; font-size: 1.05rem; color: #fff; }
  .blog-cta-text p  { margin: 0; font-size: 0.88rem; color: rgba(255,255,255,0.85); }
  .blog-cta-btn {
    display: inline-block;
    background: #fff;
    color: #1565c0 !important;
    font-weight: 800;
    font-size: 0.9rem;
    text-decoration: none !important;
    padding: 0.55rem 1.3rem;
    border-radius: 8px;
    white-space: nowrap;
    transition: box-shadow 0.15s, transform 0.1s;
  }
  .blog-cta-btn:hover { box-shadow: 0 4px 14px rgba(0,0,0,.22); transform: translateY(-1px); }

  /* ----- Author card (second) ----- */
  .blog-author-card {
    display: flex;
    align-items: center;
    gap: 0.85rem;
    background: #f8fafc;
    border: 1px solid #e2e8f0;
    border-radius: 12px;
    padding: 0.8rem 1.1rem;
    margin-bottom: 0.75rem;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
  }
  .blog-author-avatar {
    width: 58px;
    height: 76px;
    border-radius: 999px;
    object-fit: cover;
    flex-shrink: 0;
    border: 2px solid #c7d9f0;
    background: #e8edf5;
    box-shadow: 0 2px 8px rgba(0,0,0,.12);
  }
  .blog-author-info { flex: 1; min-width: 0; }
  .blog-author-card p { margin: 0; line-height: 1.25; }
  .blog-author-name { font-weight: 800; font-size: 0.95rem !important; color: #1f2937; }
  .blog-author-role { font-size: 0.82rem !important; color: #374151; }
  .blog-author-spec { font-size: 0.82rem !important; color: #374151; }
  .blog-author-dept { font-size: 0.78rem !important; color: #4b5563; }
  .blog-author-inst { font-size: 0.76rem !important; color: #6b7280; }

  /* ----- License (third) ----- */
  .blog-license {
    font-size: 0.81rem;
    color: #6b7280;
    background: #f1f5f9;
    border: 1px solid #e2e8f0;
    border-radius: 8px;
    padding: 0.55rem 1rem;
    margin-bottom: 1.1rem;
  }
  .blog-license a { color: #1976d2; }

  /* ----- Resource / export buttons (fourth) ----- */
  .blog-resources {
    display: flex;
    flex-wrap: wrap;
    gap: 0.5rem;
    margin-bottom: 0.5rem;
  }
  .blog-resource-btn {
    display: inline-flex;
    align-items: center;
    gap: 0.3rem;
    padding: 0.38rem 0.9rem;
    border-radius: 8px;
    font-size: 0.82rem;
    font-weight: 700;
    text-decoration: none !important;
    cursor: pointer;
    border: 1px solid transparent;
    transition: box-shadow 0.15s, transform 0.1s;
    line-height: 1.4;
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
  }
  .blog-resource-btn:hover { box-shadow: 0 4px 12px rgba(0,0,0,.14); transform: translateY(-1px); }
  .blog-resource-btn--notebook { background: #fff3e0; color: #e65100 !important; border-color: #ffcc80; }
  .blog-resource-btn--pdf      { background: #fce4ec; color: #c62828 !important; border-color: #f48fb1; }
  .blog-resource-btn--print    { background: #e8f5e9; color: #2e7d32 !important; border-color: #a5d6a7; }
  .blog-resource-btn--save     { background: #e8eaf6; color: #283593 !important; border-color: #9fa8da; }
  .blog-resource-btn--python   { background: #fef9c3; color: #713f12 !important; border-color: #fde68a; }
  .blog-resource-btn--ipynb    { background: #fff7ed; color: #92400e !important; border-color: #fed7aa; }

  /* ----- Related posts grid ----- */
  .bpf-related { margin-top: 2rem; padding-top: 1.5rem; border-top: 1px solid #e2e8f0; }
  .bpf-related-title {
    font-size: 0.78rem;
    font-weight: 800;
    letter-spacing: 0.12em;
    text-transform: uppercase;
    color: #6b7280;
    margin: 0 0 1rem;
  }
  .bpf-related-grid {
    display: grid;
    grid-template-columns: repeat(3, minmax(0,1fr));
    gap: 1rem;
  }
  @media (max-width: 860px) { .bpf-related-grid { grid-template-columns: repeat(2, minmax(0,1fr)); } }
  @media (max-width: 540px) { .bpf-related-grid { grid-template-columns: 1fr; } }
  .bpf-card {
    background: #f4f7fb;
    border: 1px solid #cfd8dc;
    border-radius: 12px;
    overflow: hidden;
    display: flex;
    flex-direction: column;
    box-shadow: 0 2px 8px rgba(0,0,0,.05);
    transition: box-shadow .15s, transform .12s;
    text-decoration: none !important;
  }
  .bpf-card:hover { box-shadow: 0 6px 20px rgba(0,0,0,.1); transform: translateY(-2px); }
  .bpf-card-thumb {
    width: 100%;
    aspect-ratio: 16/9;
    object-fit: cover;
    display: block;
    background: #e8edf5;
  }
  .bpf-card-body { padding: .75rem .9rem .9rem; display: flex; flex-direction: column; flex: 1; }
  .bpf-card-meta {
    display: flex; align-items: center; gap: .45rem;
    font-size: .78rem; color: #6b7280; margin-bottom: .35rem; flex-wrap: wrap;
  }
  .bpf-card-cat {
    background: #e0ecff; color: #0f3d8a;
    font-weight: 700; font-size: .72rem;
    padding: .12rem .45rem; border-radius: 999px;
  }
  .bpf-card-title {
    font-size: .95rem; font-weight: 800; color: #1565c0;
    line-height: 1.3; margin: 0 0 .45rem;
  }
  .bpf-card-title a { color: inherit; text-decoration: none; }
  .bpf-card-title a:hover { text-decoration: underline; }
  .bpf-card-tags { display: flex; flex-wrap: wrap; gap: .25rem; margin-bottom: .65rem; }
  .bpf-tag {
    background: #f1f5f9; border: 1px solid #cbd5e1;
    color: #6b7280; font-size: .72rem;
    padding: .1rem .4rem; border-radius: 999px;
  }
  .bpf-btn {
    display: inline-block;
    background: #1976d2; color: #fff !important;
    text-decoration: none !important;
    padding: .4rem .85rem; border-radius: 10px;
    font-weight: 800; font-size: .84rem; text-align: center;
    transition: background .15s, box-shadow .15s;
    align-self: flex-start; margin-top: auto;
  }
  .bpf-btn:hover { background: #0f60b6; box-shadow: 0 4px 12px rgba(0,0,0,.12); }

  @media (max-width: 560px) {
    .blog-author-card { flex-direction: column; align-items: center; text-align: center; }
    .blog-author-avatar { width: 52px; height: 68px; }
    .blog-cta { text-align: center; justify-content: center; }
    .blog-resources { justify-content: center; }
  }
</style>

<div class="blog-post-footer">

  <!-- 1. CTA -->
  <div class="blog-cta">
    <div class="blog-cta-text">
      <h3>Continue learning Artificial Intelligence</h3>
      <p>Explore practical courses on AI, Machine Learning, Deep Learning, Python, R and applied data science.</p>
    </div>
    <a class="blog-cta-btn" href="https://www.manuelcastillo.eu/udemy/" target="_blank" rel="noopener noreferrer">View AI Courses &rarr;</a>
  </div>

  <!-- 2. Author card -->
  <div class="blog-author-card">
    <img class="blog-author-avatar" src="/images/profile.jpg" alt="Manuel Castillo-Cara" onerror="this.style.display='none'" />
    <div class="blog-author-info">
      <p class="blog-author-name">Manuel Castillo-Cara, PhD</p>
      <p class="blog-author-spec">TINTOlib Python Library Developer</p>
      <p class="blog-author-role">Researcher &amp; Professor</p>
      <p class="blog-author-dept">Department of Artificial Intelligence</p>
      <p class="blog-author-inst">Universidad Nacional de Educación a Distancia (UNED)</p>
      <p class="blog-author-inst">Almerimar (Almería), Spain</p>
    </div>
  </div>

  <!-- 3. License -->
  <p class="blog-license">
    &copy; Manuel Castillo-Cara, PhD. Content licensed under
    <a href="https://creativecommons.org/licenses/by-nc/4.0/" target="_blank" rel="noopener noreferrer">CC BY-NC 4.0</a>
    unless otherwise stated.
  </p>

  <!-- 4. Export / resource buttons -->
  <div class="blog-resources">
    
    
    <button type="button" class="blog-resource-btn blog-resource-btn--print" onclick="window.print()">
      🖨️ Print / Save as PDF
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--save" id="btn-save-html">
      💾 Save as HTML
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--python" id="btn-download-py">
      🐍 Download Python
    </button>
    <button type="button" class="blog-resource-btn blog-resource-btn--ipynb" id="btn-download-ipynb">
      📓 Notebook (.ipynb)
    </button>
  </div>

  <!-- 5. Related posts -->
  
  
    <div class="bpf-related">
      <p class="bpf-related-title">You may also enjoy</p>
      <div class="bpf-related-grid">


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-08-09-rgb-fusion-structural-stability.png" alt="Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-08T00:00:00+02:00">08 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Part 4 — RGB Fusion and Structural Stability in TINTOlib: mixMethod and SSIM-Based Automatic Selection</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/08-rgb-fusion-structural-stability-mixmethod-ssim/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-08-06-08-three-representation-families.png" alt="Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-08-06T00:00:00+02:00">06 Aug 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Part 3 — Probabilities, Densities and Latent Factors in TINTOlib: gaussianMix, KDE and Factor Analysis</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/08/06-probabilities-densities-latent-factors-gaussianmix-kde-factor/">Read article →</a>
            </div>
          </article>


          <article class="bpf-card">
            
              <img class="bpf-card-thumb" src="/images/Blog/2026-07-24-07-centroids-medoids-aggloknn.png" alt="Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN" loading="lazy" />
            
            <div class="bpf-card-body">
              <div class="bpf-card-meta">
                <time datetime="2026-07-24T00:00:00+02:00">24 Jul 2026</time>
                <span class="bpf-card-cat">TINTOlib</span>
              </div>
              <h3 class="bpf-card-title">
                <a href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Part 2 — Distance-Based Encodings in TINTOlib: k-Means, k-Medoids and aggloKNN</a>
              </h3>
              
                <div class="bpf-card-tags">
                  
                    <span class="bpf-tag">TINTOlib</span>
                  
                    <span class="bpf-tag">Clusters</span>
                  
                    <span class="bpf-tag">Synthetic Images</span>
                  
                    <span class="bpf-tag">Tabular Data</span>
                  
                </div>
              
              <a class="bpf-btn" href="/blog/2026/07/24-distance-based-encodings-kmeans-kmedoids-aggloknn/">Read article →</a>
            </div>
          </article>
        
      </div>
    </div>
  

</div>

<!-- ===== Copy-code + Export logic ===== -->
<script>
(function () {

  /* ---------- helpers ---------- */
  function slugify(str) {
    return (str || 'blog-post')
      .replace(/[^a-z0-9\-_]/gi, '-')
      .replace(/-+/g, '-')
      .toLowerCase()
      .substring(0, 60)
      .replace(/^-+|-+$/g, '');
  }

  function download(content, filename, mime) {
    var blob = new Blob([content], { type: mime });
    var url  = URL.createObjectURL(blob);
    var a    = document.createElement('a');
    a.href = url;
    a.download = filename;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    setTimeout(function () { URL.revokeObjectURL(url); }, 5000);
  }

  function getCodeBlocks() {
    var nodes = document.querySelectorAll('.page__content pre code');
    var blocks = [];
    nodes.forEach(function (node) {
      var text = node.textContent.trimEnd();
      if (text) blocks.push(text);
    });
    return blocks;
  }

  /* ---------- Copy-code buttons ---------- */
  var pres = document.querySelectorAll('.page__content pre');
  pres.forEach(function (pre) {
    var code = pre.querySelector('code');
    var getText = function () {
      if (code) return code.textContent;
      var clone = pre.cloneNode(true);
      clone.querySelectorAll('.copy-code-btn').forEach(function (b) { b.parentNode.removeChild(b); });
      return clone.textContent;
    };
    var btn = document.createElement('button');
    btn.type = 'button';
    btn.className = 'copy-code-btn';
    btn.textContent = 'Copy';
    btn.setAttribute('aria-label', 'Copy code to clipboard');
    pre.appendChild(btn);
    btn.addEventListener('click', function () {
      var text = getText();
      if (navigator.clipboard && navigator.clipboard.writeText) {
        navigator.clipboard.writeText(text).then(function () { flash(btn); });
      } else {
        var ta = document.createElement('textarea');
        ta.value = text;
        ta.style.cssText = 'position:fixed;opacity:0;top:0;left:0';
        document.body.appendChild(ta);
        ta.focus(); ta.select();
        try { document.execCommand('copy'); } catch (e) {}
        document.body.removeChild(ta);
        flash(btn);
      }
    });
  });
  function flash(btn) {
    btn.textContent = 'Copied \u2713';
    btn.classList.add('copied');
    setTimeout(function () { btn.textContent = 'Copy'; btn.classList.remove('copied'); }, 1600);
  }

  /* ---------- Save as HTML ---------- */
  var saveHtmlBtn = document.getElementById('btn-save-html');
  if (saveHtmlBtn) {
    saveHtmlBtn.addEventListener('click', function () {
      var clone = document.documentElement.cloneNode(true);
      var origin = window.location.origin;
      clone.querySelectorAll('img[src]').forEach(function (img) {
        var src = img.getAttribute('src');
        if (src && src.charAt(0) === '/') img.setAttribute('src', origin + src);
      });
      clone.querySelectorAll('link[href]').forEach(function (el) {
        var href = el.getAttribute('href');
        if (href && href.charAt(0) === '/') el.setAttribute('href', origin + href);
      });
      clone.querySelectorAll('script[src]').forEach(function (el) {
        var src = el.getAttribute('src');
        if (src && src.charAt(0) === '/') el.setAttribute('src', origin + src);
      });
      var html = '<!doctype html>\n' + clone.outerHTML;
      download(html, slugify(document.title) + '.html', 'text/html;charset=utf-8');
    });
  }

  /* ---------- Download Python ---------- */
  var pyBtn = document.getElementById('btn-download-py');
  if (pyBtn) {
    pyBtn.addEventListener('click', function () {
      var blocks = getCodeBlocks();
      var lines;
      if (blocks.length === 0) {
        lines = ['# No code blocks found in this post.\n'];
      } else {
        lines = [];
        blocks.forEach(function (block, i) {
          lines.push('# ---- Code block ' + (i + 1) + ' ----\n');
          lines.push(block + '\n\n');
        });
      }
      download(lines.join(''), slugify(document.title) + '.py', 'text/x-python;charset=utf-8');
    });
  }

  /* ---------- Download Notebook (.ipynb) — full article walker ---------- */
  var ipynbBtn = document.getElementById('btn-download-ipynb');
  if (ipynbBtn) {
    ipynbBtn.addEventListener('click', function () {

      function mdLines(text) {
        /* Split into source array as Jupyter expects (lines ending with \n except last) */
        var lines = text.split('\n');
        return lines.map(function (l, i) { return i < lines.length - 1 ? l + '\n' : l; });
      }

      function mkdCell(text) {
        var t = (text || '').trim();
        if (!t) return null;
        return { cell_type: 'markdown', metadata: {}, source: mdLines(t) };
      }

      function codeCell(text) {
        var t = (text || '').trimEnd();
        if (!t) return null;
        return { cell_type: 'code', execution_count: null, metadata: {}, outputs: [], source: mdLines(t) };
      }

      function nodeToMd(el) {
        var tag = el.tagName ? el.tagName.toLowerCase() : '';
        /* headings */
        if (/^h[1-6]$/.test(tag)) {
          var level = parseInt(tag.slice(1), 10);
          return Array(level + 1).join('#') + ' ' + el.textContent.trim();
        }
        /* paragraph */
        if (tag === 'p') return el.textContent.trim();
        /* blockquote */
        if (tag === 'blockquote') {
          return el.textContent.trim().split('\n').map(function (l) { return '> ' + l; }).join('\n');
        }
        /* lists */
        if (tag === 'ul' || tag === 'ol') {
          var items = [];
          el.querySelectorAll('li').forEach(function (li, i) {
            items.push((tag === 'ol' ? (i + 1) + '. ' : '- ') + li.textContent.trim());
          });
          return items.join('\n');
        }
        /* figure / img */
        if (tag === 'figure') {
          var img = el.querySelector('img');
          if (img) {
            var src = img.getAttribute('src') || '';
            if (src.charAt(0) === '/') src = window.location.origin + src;
            var alt = img.getAttribute('alt') || '';
            var cap = el.querySelector('figcaption');
            return '!['+ alt +']('+ src +')' + (cap ? '\n*' + cap.textContent.trim() + '*' : '');
          }
        }
        if (tag === 'img') {
          var src2 = el.getAttribute('src') || '';
          if (src2.charAt(0) === '/') src2 = window.location.origin + src2;
          return '![' + (el.getAttribute('alt') || '') + '](' + src2 + ')';
        }
        return '';
      }

      function getArticleCellsForNotebook() {
        var container = document.querySelector('.page__content');
        if (!container) return [];

        var clone = container.cloneNode(true);
        /* Remove footer, scripts, styles, copy buttons */
        ['script','style','.blog-post-footer','.copy-code-btn'].forEach(function (sel) {
          clone.querySelectorAll(sel).forEach(function (n) { n.parentNode.removeChild(n); });
        });

        var cells = [];
        var INLINE_TAGS = /^(h[1-6]|p|ul|ol|blockquote|figure|img)$/;

        function walk(node) {
          if (node.nodeType !== 1) return; /* element nodes only */
          var tag = node.tagName.toLowerCase();

          /* code block */
          if (tag === 'pre') {
            var code = node.querySelector('code');
            var text = (code ? code : node).textContent.trimEnd();
            var cell = codeCell(text);
            if (cell) cells.push(cell);
            return;
          }

          /* inline-mappable tags */
          if (INLINE_TAGS.test(tag)) {
            var md = nodeToMd(node);
            var cell2 = mkdCell(md);
            if (cell2) cells.push(cell2);
            return;
          }

          /* containers: div, section, article — recurse children */
          Array.prototype.forEach.call(node.childNodes, function (child) {
            walk(child);
          });
        }

        Array.prototype.forEach.call(clone.childNodes, function (child) {
          walk(child);
        });

        return cells;
      }

      var cells = [];
      /* Header cells */
      cells.push(mkdCell('# ' + (document.title || 'Blog Post')));
      var pageUrl = window.location.href;
      cells.push(mkdCell('**Source:** [' + pageUrl + '](' + pageUrl + ')'));

      /* Article body cells */
      var bodyCells = getArticleCellsForNotebook();
      if (bodyCells.length === 0) {
        cells.push(mkdCell('*No content extracted from this post.*'));
      } else {
        cells = cells.concat(bodyCells);
      }

      var nb = {
        nbformat: 4,
        nbformat_minor: 5,
        metadata: {
          kernelspec: { display_name: 'Python 3', language: 'python', name: 'python3' },
          language_info: { name: 'python', version: '3.x' }
        },
        cells: cells
      };

      download(JSON.stringify(nb, null, 2), slugify(document.title) + '.ipynb', 'application/json;charset=utf-8');
    });
  }

}());
</script>]]></content><author><name>Ph.D. Manuel Castillo-Cara</name><email>manwest.c@gmail.com</email></author><category term="TINTOlib" /><category term="TINTOlib" /><category term="Tabular-to-Image" /><category term="Synthetic Images" /><category term="Deep Learning" /><category term="CNN" /><category term="PyTorch" /><category term="Machine Learning" /><summary type="html"><![CDATA[Technical introduction to TINTOlib, a Python framework for transforming tabular data into synthetic images and applying CNN-based deep learning architectures.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.manuelcastillo.eu/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png" /><media:content medium="image" url="https://www.manuelcastillo.eu/images/Blog/2026-05-27-01-introduction-to-tintolib-tabular-to-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>